Skip to content
Start free

Author Profile

Raluca Penciuc

Full-Stack Developer26 articles

Raluca Penciuc is a Full Stack Developer at WebScrapingAPI, building scrapers, improving evasions, and finding reliable ways to reduce detection across target websites.

Raluca Penciuc, Full-Stack Developer @ WebScrapingAPI

Published Articles

26 articles

Web scrapingProxy rotationPython web scrapingRuby web scrapingJava web scrapingR web scrapingC++ web scrapingData extraction automation

Published Articles

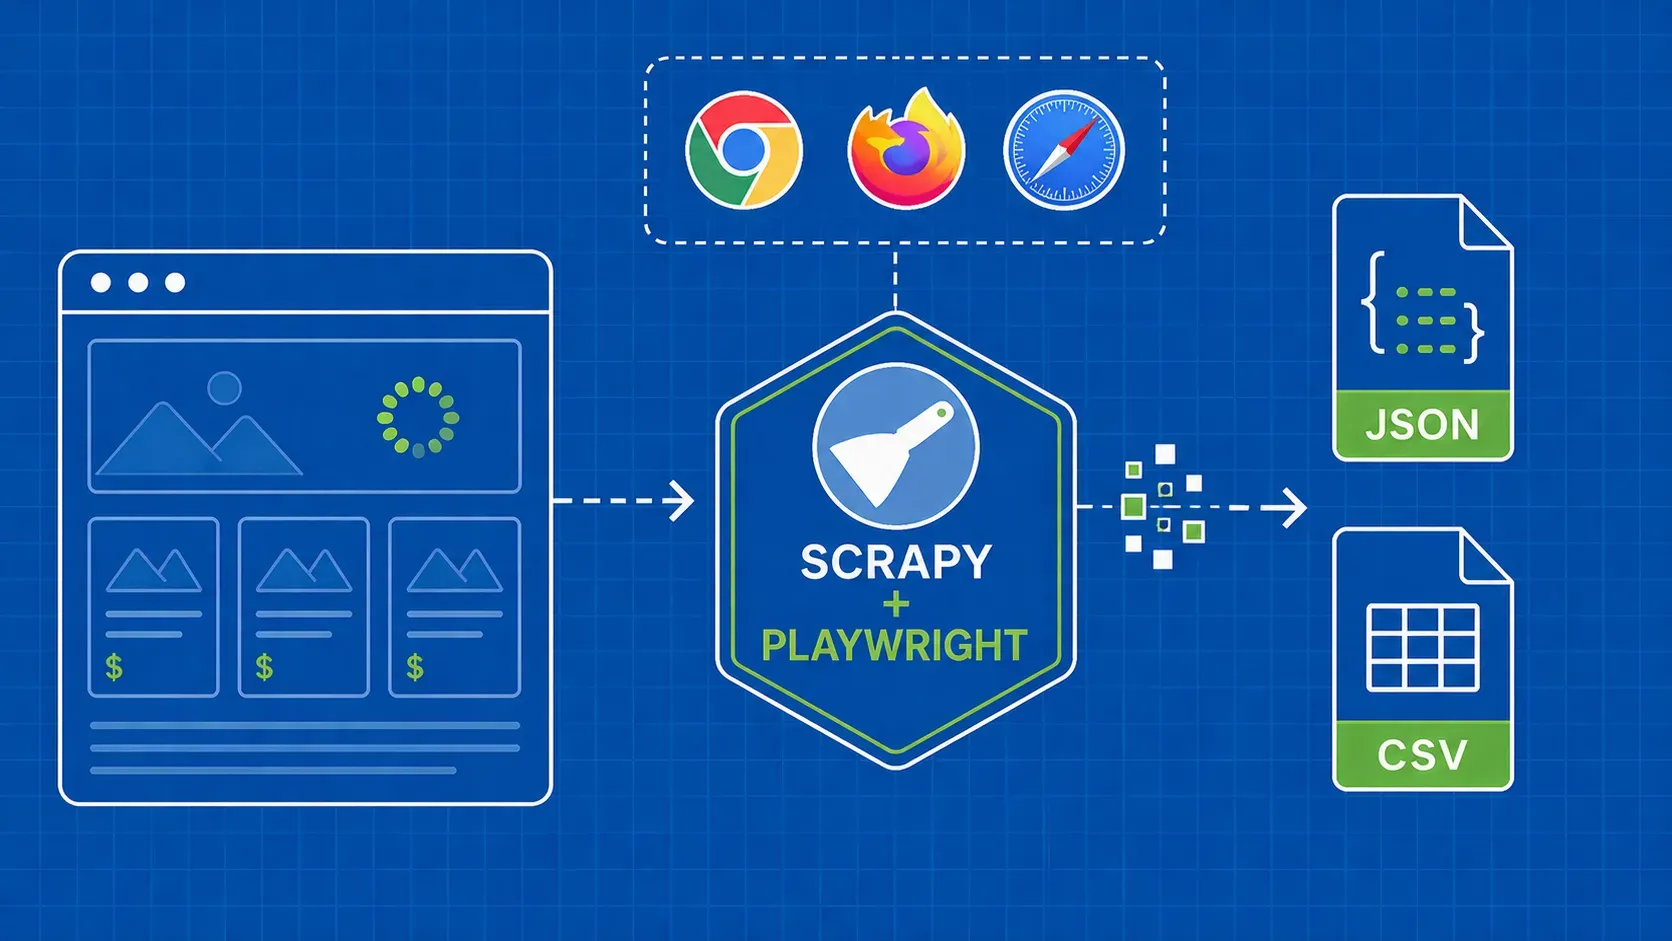
Scrapy-Playwright Tutorial: Scrape JS-Heavy Sites
Guides

Scrapy-Playwright Tutorial: Scrape JS-Heavy Sites

TL;DR: Scrapy-Playwright lets you render JavaScript-heavy pages directly inside Scrapy spiders by controlling real Chromium, Firefox, or WebKit browsers through Playwright. This tutorial walks you through installation, configuration, page interactions, AJAX interception, anti-detection, and a production-ready project structure so you can scrape dynamic sites without leaving the Scrapy ecosystem.

Raluca Penciuc17 min read
Read Article
Scrape Amazon Product Data with Python: Hands-On Guide
Guides

Scrape Amazon Product Data with Python: Hands-On Guide

TL;DR: Amazon product pages are packed with valuable data (prices, ratings, reviews, ASINs), but extracting it reliably requires more than a basic HTTP request. This guide walks you through building a Python scraper with Requests and BeautifulSoup, handling pagination and anti-bot defenses, exporting to CSV or JSON, and feeding the results into LLM workflows. You will also learn when to use a scraping API instead of rolling your own solution.

Raluca Penciuc15 min read
Read Article
Scraping Twitter Data: Sentiment Analysis and Marketing
Guides

Scraping Twitter Data: Sentiment Analysis and Marketing

TL;DR: Maximize Twitter data with expert web scraping. Learn scraping Twitter for sentiment analysis, marketing, and business intel. Comprehensive guide using TypeScript.

Raluca Penciuc9 min read
Read Article
How to Scrape Realtor.com: A Practical 2026 Guide
Guides

How to Scrape Realtor.com: A Practical 2026 Guide

TL;DR: If you're working out how to scrape Realtor.com cleanly, three things matter most: stable selectors that survive their hashed class names, a request layer that survives Realtor's anti-bot stack, and code that walks both list pages and detail pages. This guide is the full Python build, with anti-block tactics and LLM-ready exports.

Raluca Penciuc12 min read
Read Article
Web Scraping Booking.com: Hotels, Prices, Reviews
Guides

Web Scraping Booking.com: Hotels, Prices, Reviews

TL;DR: This guide walks through web scraping Booking.com end to end in Python: pulling search listings, hotel pages, nightly prices, and guest reviews. You get two complementary methods: a Selenium Wire workflow for JS-rendered pages and a faster path that calls Booking.com's internal /dml/graphql endpoint directly, plus an anti-block playbook, currency handling, and a workaround for the roughly 1,000-result paging cap.

Raluca Penciuc13 min read
Read Article
How to Scrape Data from Idealista: A 2026 Playbook
Guides

How to Scrape Data from Idealista: A 2026 Playbook

TL;DR: Idealista is the largest property marketplace in Spain, Italy, and Portugal, but it sits behind a serious anti-bot stack that blocks naive scrapers fast. This guide walks you through how to scrape data from Idealista end-to-end in Python, covering site mapping, Selenium with undetected-chromedriver, DataDome handling, proxy rotation, and clean exports, with production hardening competitors usually skip.

Raluca Penciuc14 min read
Read Article
How to Scrape Yelp with Python: Reviews and Listings
Guides

How to Scrape Yelp with Python: Reviews and Listings

TL;DR: This guide walks you through building a complete Yelp scraper in Python, covering search results, business details, and reviews with working code. You'll also learn how to handle anti-bot protections, export data to CSV or JSON, and feed scraped reviews into an LLM for sentiment analysis, something no other Yelp scraping tutorial covers.

Raluca Penciuc13 min read
Read Article
How to Scrape Walmart.com: 2026 End-to-End Guide
Guides

How to Scrape Walmart.com: 2026 End-to-End Guide

TL;DR: This guide walks through how to web scrape Walmart product data end-to-end in Python, from parsing the hidden __NEXT_DATA__ JSON to scaling with proxies, retries, and async fetches. It also draws an honest line for when a managed scraper API beats DIY.

Raluca Penciuc12 min read
Read Article
Web Scraping YouTube with Python: Videos, Comments, Data
Guides

Web Scraping YouTube with Python: Videos, Comments, Data

TL;DR: This is a 2026 playbook for how to scrape YouTube with Python. You'll pick the right method (Data API v3, yt-dlp, hidden /youtubei/v1/ endpoints, or a managed scraper) using a decision matrix, then run code for video metadata, comments, channels, search, Shorts, and transcripts, with a production section on proxies, headers, and 429 backoff so you don't get blocked.

Raluca Penciuc17 min read
Read Article
HTTP Headers Web Scraping: Stop Getting Blocked
Science of Web Scraping

HTTP Headers Web Scraping: Stop Getting Blocked

TL;DR: HTTP headers are usually why your scraper gets a 403 while your browser loads the same URL fine. This guide shows which headers anti-bot systems actually inspect, how to capture a real browser's header set from DevTools, how to send and rotate them correctly in Python and Node.js, and when manual tuning stops paying off and a managed scraping API is the better move.

Raluca Penciuc12 min read
Read Article
Ruby HTML and XML Parsers: A Workload-Based Comparison
Guides

Ruby HTML and XML Parsers: A Workload-Based Comparison

TL;DR: Choose Ruby HTML and XML parsers by workload, not by a generic ranking. Start with Nokogiri for broad HTML and XML tree parsing, consider Ox or LibXML Ruby for XML-specific jobs, and add Selenium only when a real browser must render or interact with the page.

Raluca Penciuc11 min read
Read Article
Web Scraping with Ruby: Faraday, Nokogiri, and Selenium
Guides

Web Scraping with Ruby: Faraday, Nokogiri, and Selenium

TL;DR: Build a production-minded Ruby web scraper with Faraday, Nokogiri, CSV, retries, tests, and Selenium for JavaScript-rendered pages.

Raluca Penciuc15 min read
Read Article
Rotating Proxies: How IP Rotation Works for Web Scraping
Science of Web Scraping

Rotating Proxies: How IP Rotation Works for Web Scraping

TL;DR: So what are rotating proxies, in one line? Proxy servers that assign a different IP to each request from a managed pool, which is how scrapers slip past per-IP rate limits, CAPTCHAs, and geo-filters. This guide covers how rotation works, the four pool types, setup code in three languages, and how to pick a provider.

Raluca Penciuc10 min read
Read Article
Cheerio Web Scraping in Node.js: load() to a Tested Scraper
Guides

Cheerio Web Scraping in Node.js: load() to a Tested Scraper

TL;DR: Cheerio is a fast HTML parser for Node.js with a jQuery-style API, so it suits web scraping when the data is already in the page's raw HTML. Use fetch plus Cheerio for static pages, call the page's JSON directly when it loads data that way, and render with a browser only when JavaScript builds the content. This guide builds a tested scraper with pagination, retries, and JSON or CSV export.

Raluca Penciuc17 min read
Read Article
Yahoo Finance API Alternatives: A Developer's Guide
Guides

Yahoo Finance API Alternatives: A Developer's Guide

TL;DR: Compare documented market-data providers, then migrate with explicit feed, timezone, adjustment, licensing, and validation requirements.

Raluca Penciuc12 min read
Read Article
9 Best Google Image Search APIs for Developers
Guides

9 Best Google Image Search APIs for Developers

TL;DR: Explore the top 9 Google Image Search API tools for efficient image scraping. Learn how to optimize your image search and improve your data collection with these powerful APIs.

Raluca Penciuc9 min read
Read Article
Scrapebox Alternative: Pick by Job Type
Guides

Scrapebox Alternative: Pick by Job Type

TL;DR: Find the right replacement for site audits, custom crawling, browser interactions, visual extraction, or dataset cleanup, then validate the switch with a pilot.

Raluca Penciuc12 min read
Read Article
Screen Scraping Websites with Playwright
Guides

Screen Scraping Websites with Playwright

TL;DR: Build a browser collector with explicit readiness, validated records, and reliable stopping conditions. Learn when DOM extraction is preferable to screenshots and OCR.

Raluca Penciuc11 min read
Read Article
node-fetch Alternatives: Native Fetch, Axios, Got, and Ky
Guides

node-fetch Alternatives: Native Fetch, Axios, Got, and Ky

TL;DR: Start with native Fetch on supported Node.js versions, then add a dependency only when it replaces meaningful custom code. Axios favors cross-runtime convenience, Got offers deeper Node-specific control, Ky improves Fetch ergonomics, and SuperAgent suits fluent form and file workflows. Whatever you choose, preserve status, timeout, retry, cookie, and stream behavior during migration.

Raluca Penciuc13 min read
Read Article
Web Scraping in R: A Practical rvest and httr2 Guide
Guides

Web Scraping in R: A Practical rvest and httr2 Guide

TL;DR: For web scraping in R, use rvest to parse HTML with CSS selectors or XPath and httr2 to fetch pages with retries and rate limits. rvest alone is fine for one page; once you crawl, fetch with httr2 and parse with rvest, and use read_html_live() when JavaScript builds the page. This guide covers tables, pagination, script-tag data, scraper APIs, and offline tests.

Raluca Penciuc20 min read
Read Article
7 Axios Alternatives for Browsers, Node.js, and Scraping
Guides

7 Axios Alternatives for Browsers, Node.js, and Scraping

TL;DR: Use native Fetch for a dependency-light baseline, Ky for Fetch ergonomics, Got or SuperAgent for richer client behavior, and Alova when frontend request state is the real requirement. Choose Puppeteer or a managed scraping API only when rendering, interaction, proxies, or anti-bot systems make ordinary HTTP transport insufficient.

Raluca Penciuc13 min read
Read Article
Web Scraping Java: Build a Reliable Java Scraper
Guides

Web Scraping Java: Build a Reliable Java Scraper

TL;DR: Start with HttpClient and Jsoup when data is present in returned HTML, call an exposed JSON source when appropriate, and add rendering or Selenium only for browser-dependent state. This web scraping Java tutorial grows one Java 21 codebase through pagination, capped concurrency, retries, sessions, validation, and durable output.

Raluca Penciuc25 min read
Read Article
C and C++ Web Scraping with libcurl and lexbor
Guides

C and C++ Web Scraping with libcurl and lexbor

TL;DR: For C and C++ web scraping, use libcurl to download pages and lexbor to parse HTML5 with CSS selectors; both are plain C, so one stack serves both languages. Choose C++ when the scraper lives in a native codebase, runs on constrained hardware, or parses large volumes of HTML. For quick one-off jobs, Python is faster to write.

Raluca Penciuc24 min read
Read Article
Best Proxy Types for Web Scraping in 2026
Science of Web Scraping

Best Proxy Types for Web Scraping in 2026

TL;DR: Web scraping proxies sit between your scraper and the target site, mask your IP, and let you survive rate limits, geo-walls, and anti-bot defenses. The right type (datacenter, residential, ISP, or mobile) and the right protocol (HTTP/HTTPS or SOCKS5, IPv4 or IPv6) depend on the target's defenses, your geo needs, and how heavy each page is. This guide walks the trade-offs and ends with a vendor-neutral checklist.

Raluca Penciuc12 min read
Read Article
Proxy Management for Web Scraping
Science of Web Scraping

Proxy Management for Web Scraping

TL;DR: Design proxy allocation around work requirements, session leases, layered health, and source-wide limits. Measure accepted records instead of address rotations.

Raluca Penciuc12 min read
Read Article
Python Web Scraping in 2026: A Developer's Playbook
Guides

Python Web Scraping in 2026: A Developer's Playbook

TL;DR: This is a hands-on Python web scraping guide that starts with a decision tree, then walks through Requests plus Beautiful Soup, XPath with lxml, Playwright, Selenium, Scrapy, and a scraping API for hard targets. You will finish with working code, an anti-block playbook, LLM-ready storage patterns, and a production checklist.

Raluca Penciuc28 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.