TL;DR: For web scraping in C#, start on .NET 10 with the built-in HttpClient to download pages and AngleSharp to parse HTML with CSS selectors. Pick HtmlAgilityPack when you prefer XPath or maintain older code, and add Playwright for .NET when JavaScript builds the page. This guide builds one scraper with polite retries, bounded crawling, CSV and JSON export, and offline tests.
Web scraping in C# starts with a familiar problem: the data you need sits on a web page, and you want it as typed C# objects without leaving .NET. On .NET 10, the platform already ships most of what you need, and the few missing pieces are mature NuGet packages.
If you need C or C++ instead of C#, see our guide to C and C++ web scraping.
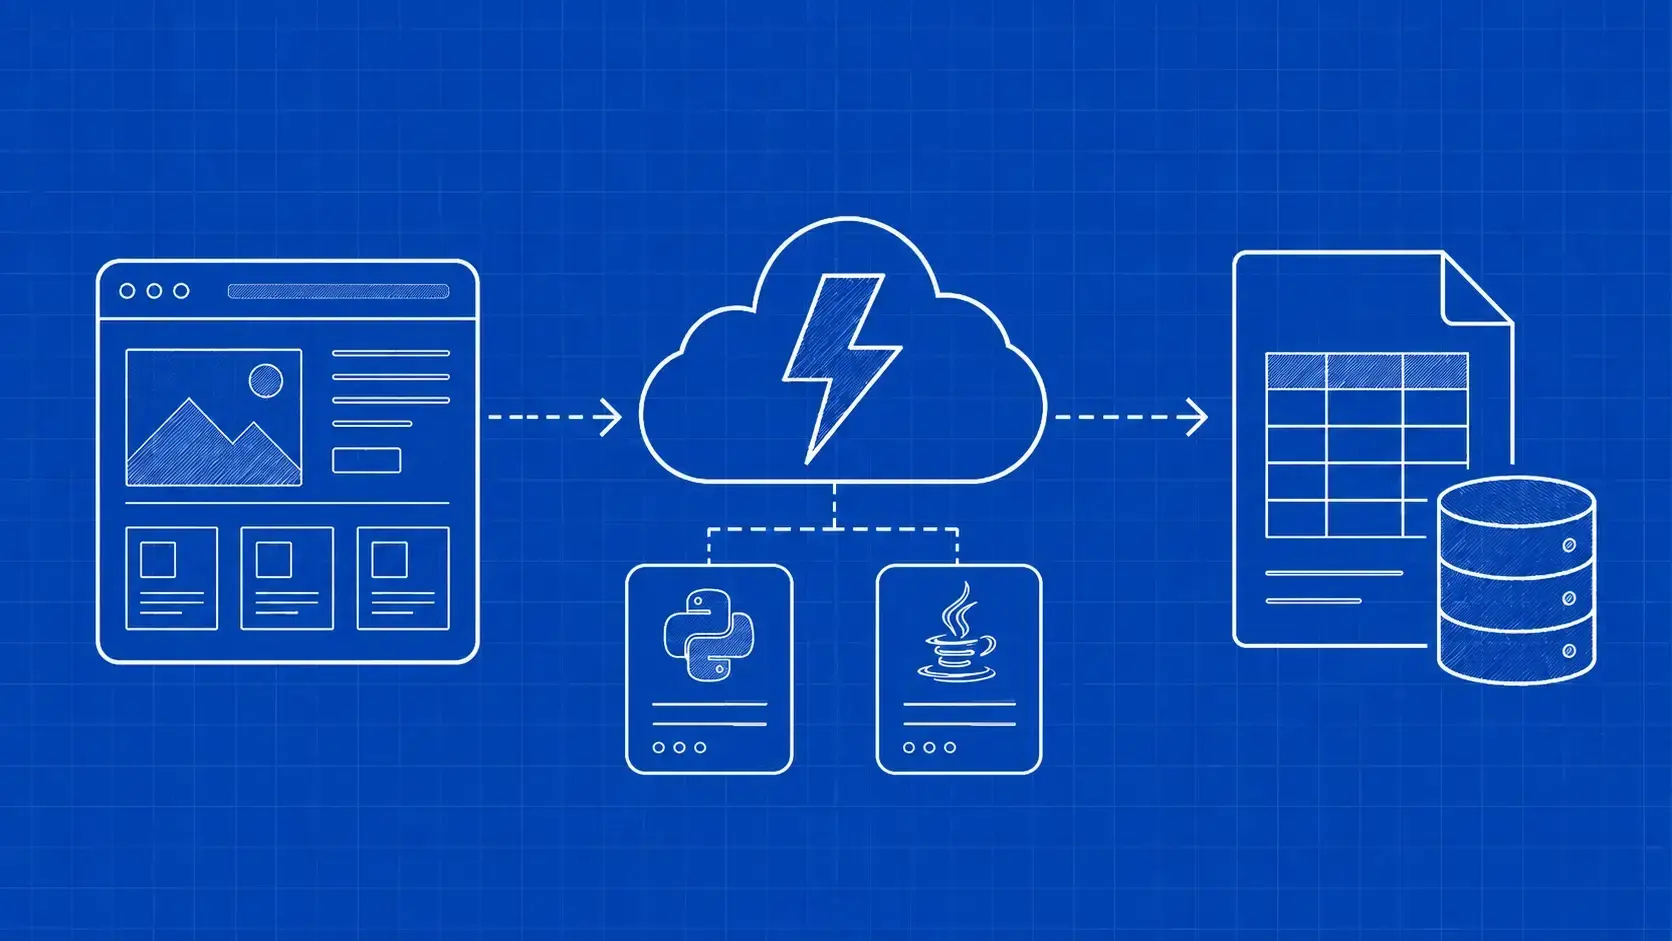
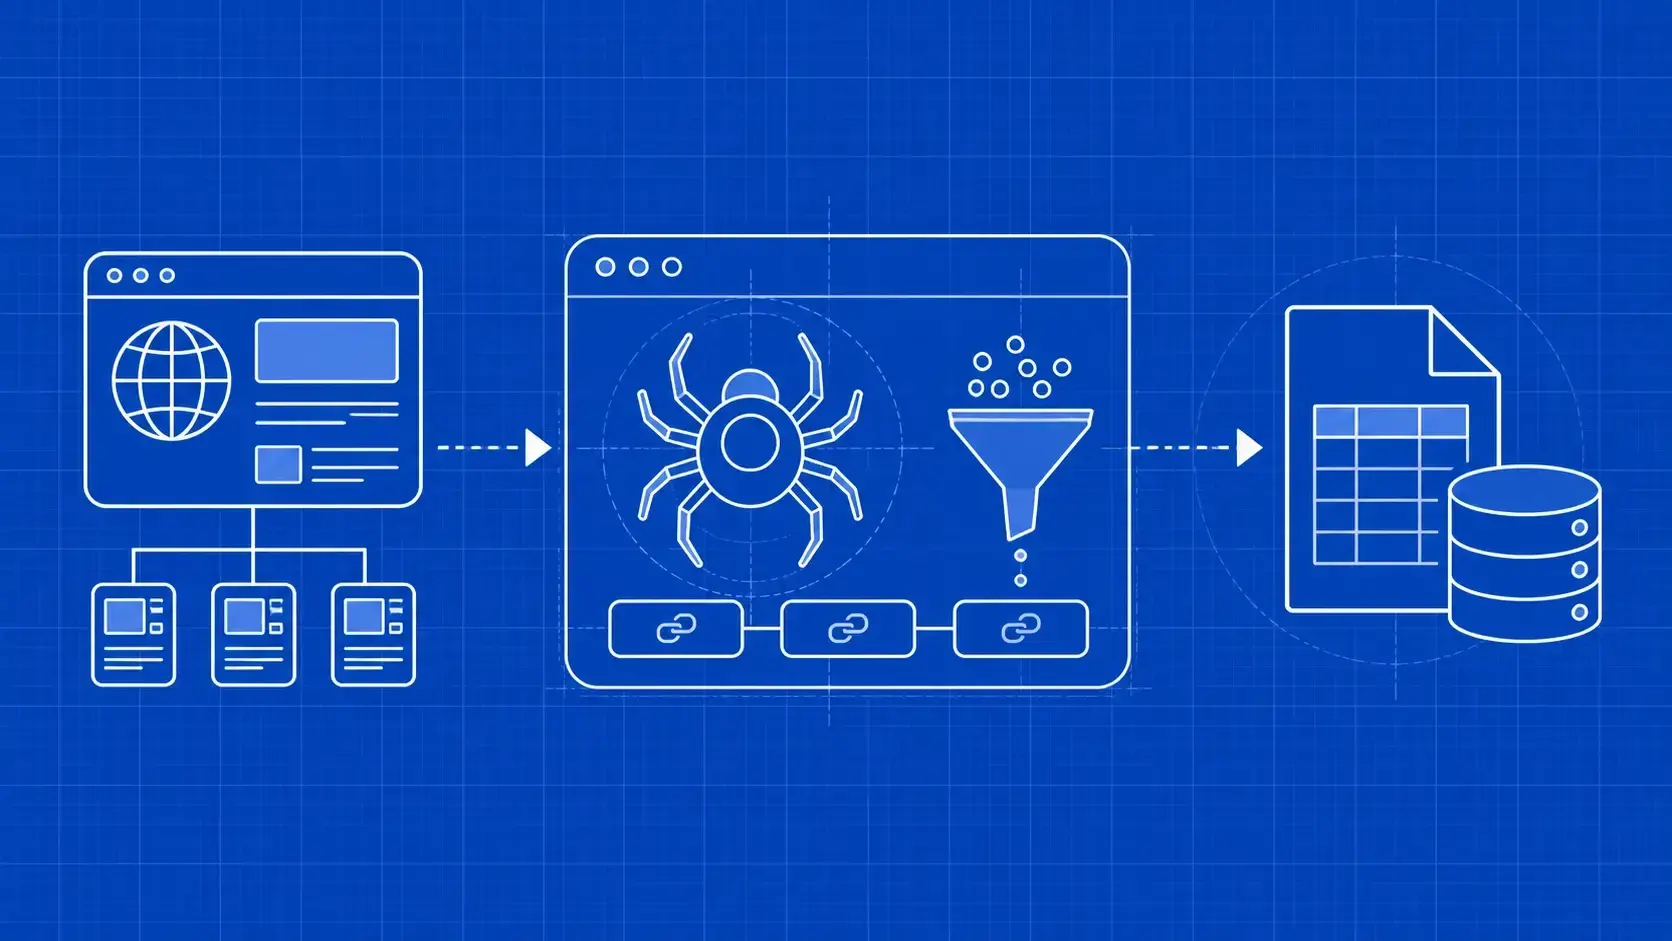
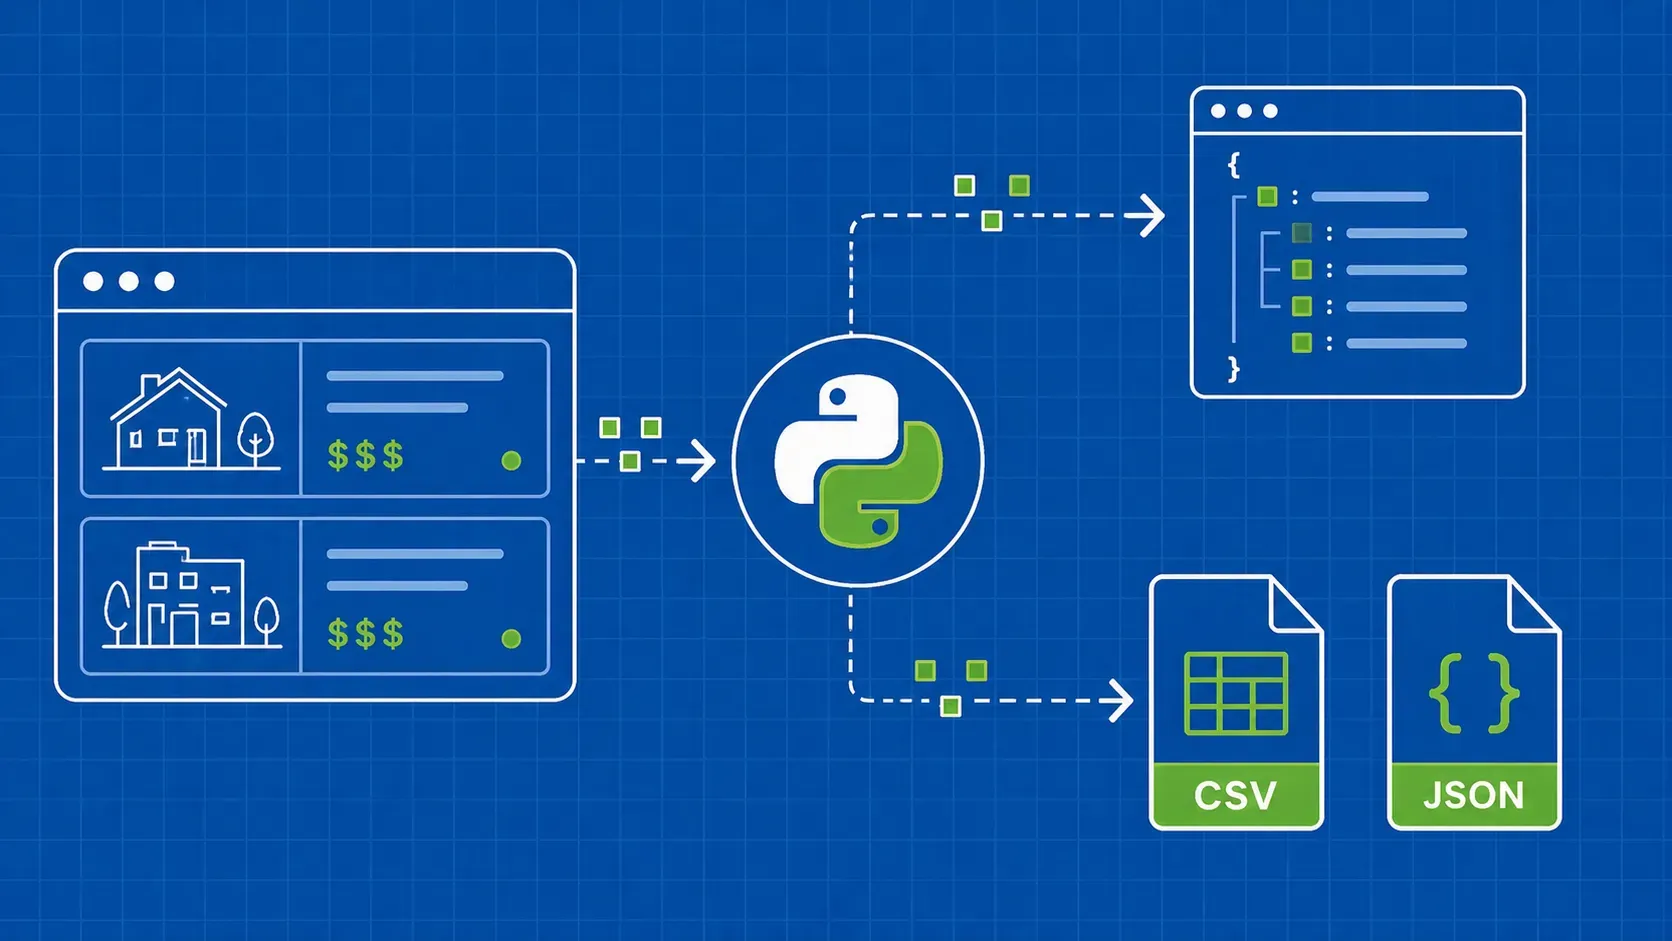
This guide builds one small scraper step by step. You'll parse a page with AngleSharp (or HtmlAgilityPack, if you prefer XPath), fetch politely with one HttpClient that retries 429 responses the right way, crawl paginated listings with bounded concurrency, and export CSV and JSON. Then you'll pull data that JavaScript builds, render pages with Playwright for .NET, hand blocked pages to a scraper API without touching your parser, and test it all offline. The examples use two public practice sites built for scraping: Books to Scrape and the /js/ version of Quotes to Scrape.
Quick start - Install the .NET 10 SDK and create a console app withdotnet new console. - Add a parser:dotnet add package AngleSharp. - Fetch withHttpClient.GetStringAsync(), select withQuerySelectorAll(), and extract withTextContentandGetAttribute(). - Use Playwright for .NET when JavaScript builds the page.