Skip to content
Start free
Back to Blog

Web Scraping vs Web Crawling: A Beginner's Guide

Anda MiuțescuLast updated on 11 min read
Web Scraping vs Web Crawling: A Beginner's Guide
TL;DR: Web crawling discovers and visits relevant pages; web scraping extracts useful information from their content. If you already have the URLs, you can start with extraction. If you need to find pages and collect their data, combine both jobs and check the outputs separately.

Web scraping vs web crawling is the difference between extracting information from web pages and discovering which pages to visit. You use scraping to collect values such as book titles and prices; you use crawling to find the pages that contain them.

Imagine you need a spreadsheet of programming books sold by an online store. The category page gives you a starting point, but it may link to several pages of results. Finding the book addresses is one task. Reading the correct author and price from each book page is another.

Knowing the difference helps you avoid two frustrating outcomes: a long list of links with no usable data, or accurate data from a few pages while the rest of the catalog goes unnoticed. It also helps you understand what a tool actually does when it describes itself as a scraper, crawler, spider, or data extraction service.

This guide compares the outputs, explains the mechanics, and follows a fictional bookstore from discovery to validated records. You will then have a practical way to choose a workflow and test it on a small batch before expanding it.
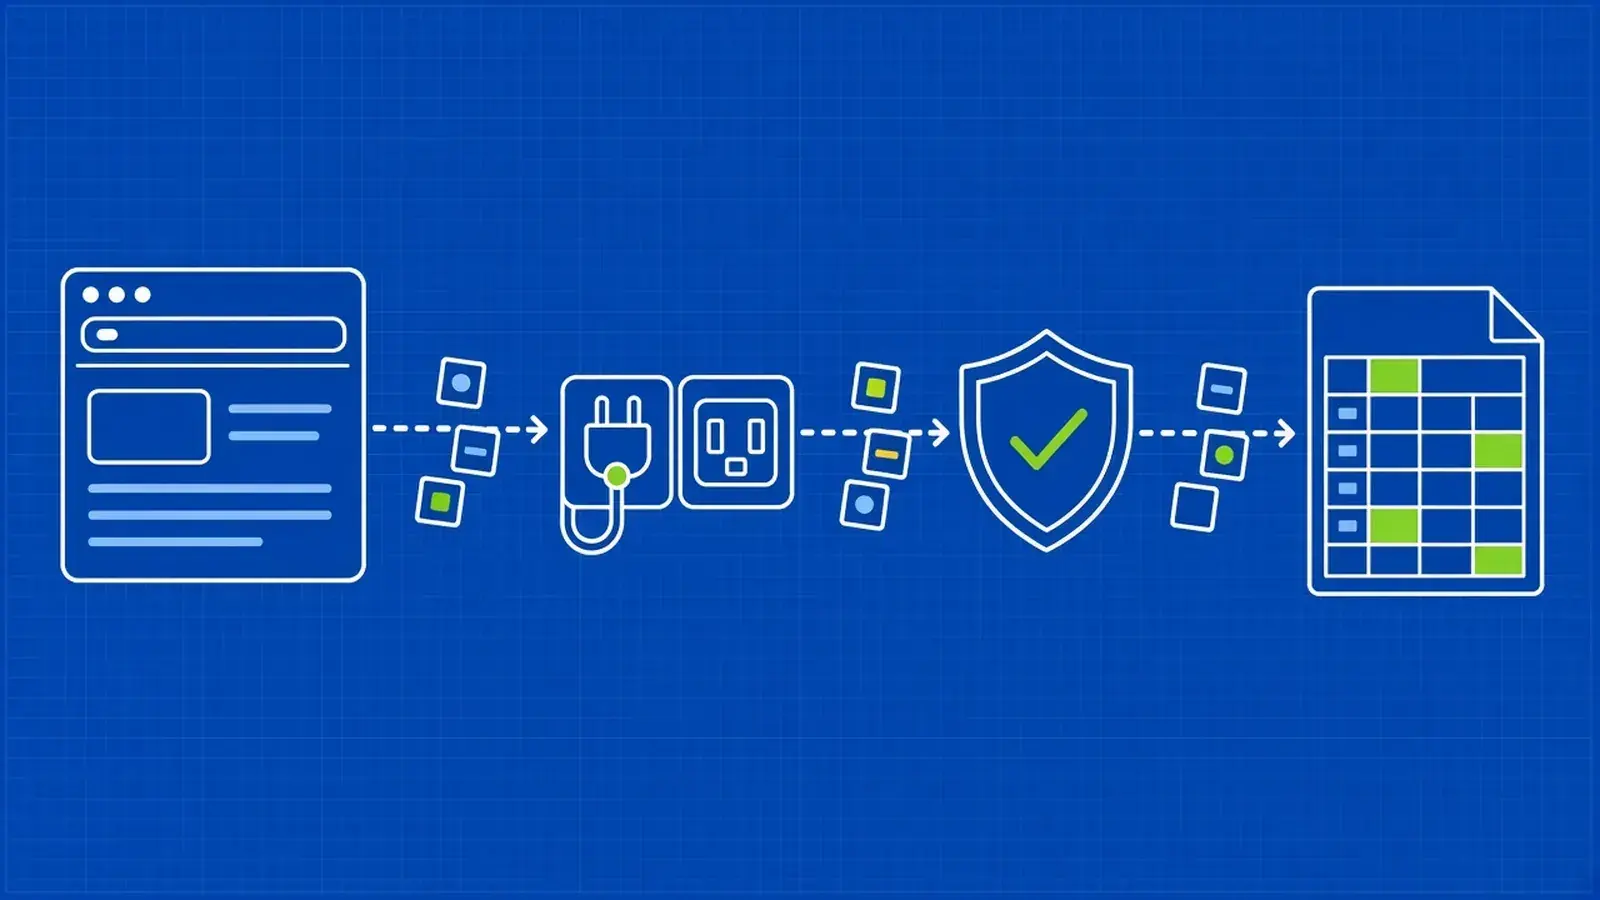
Web Scraping vs Web Crawling: Compare the Outputs

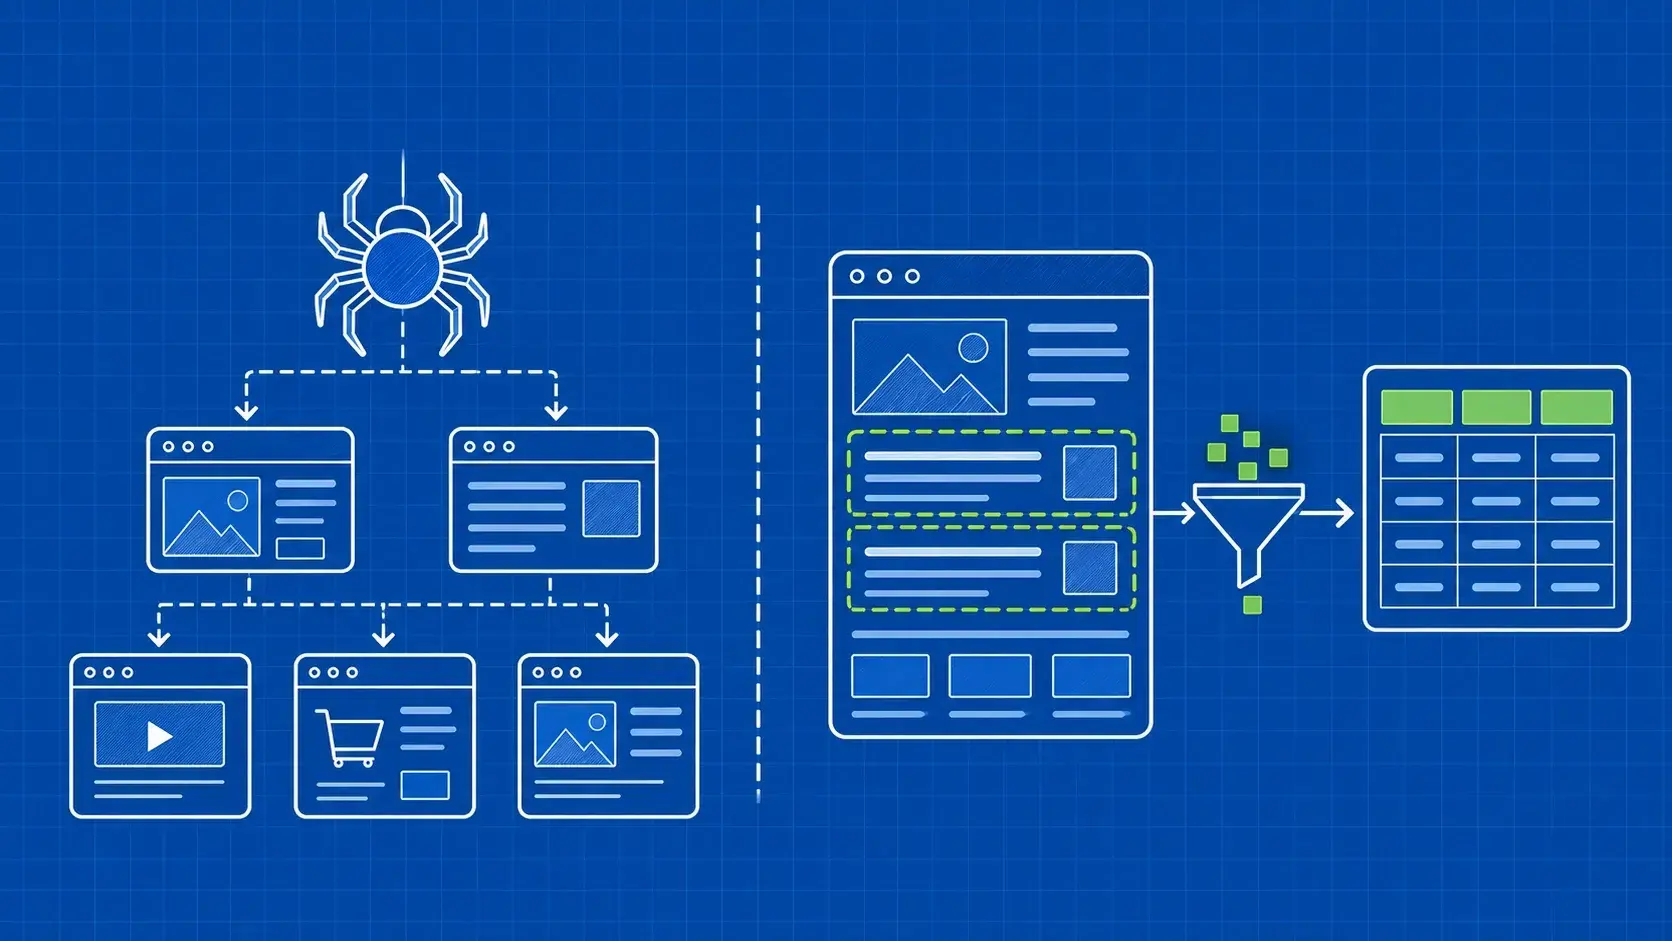
A web crawler discovers pages and decides which ones to visit. A web scraper extracts information from page content. Both retrieve web content, and both can work across many pages, but they solve different parts of a collection task.

What you compare

Web crawling

Web scraping

Main purpose

Find and visit relevant pages

Collect the fields or text you need

Typical input

Starting addresses and navigation rules

Page addresses or content and extraction rules

Useful output

URLs, downloaded pages, and visit information

Structured data such as titles, prices, and dates

Main quality question

Did the job reach the intended pages?

Did it extract the right values?

Common failure

Missing pages or following irrelevant links

Missing fields or reading the wrong element

For example, discovering a store’s product pages is a crawling task. Extracting each product’s price is a scraping task. A project that monitors a changing catalog needs a way to handle both.

The distinction is not “one page versus many pages.” You can scrape a supplied list of thousands of addresses without discovering new links. You can also crawl a small, explicitly bounded section of one site.

When comparing web scraping vs web crawling tools, ask what the tool returns. A list of links does not contain your desired prices. Conversely, a correct price from one known page does not prove that you found the rest of the catalog. Choose the capabilities your final output requires.

How a Web Crawler Discovers Pages

Start with seed URLs, the addresses from which a crawler begins exploring. On a bookstore site, a seed could be the programming category. The crawler fetches that page, identifies eligible links, and places new addresses in a queue, which is simply a list of pages waiting to be visited.

A bounded crawl follows a repeatable sequence:

  1. Fetch an address from the queue.
  2. Read links from the returned page.
  3. Resolve relative links against the page’s address.
  4. Keep addresses allowed by your domain and path rules.
  5. Add unseen addresses to the queue.
  6. Continue until the queue is empty or your stopping limit is reached.

Pagination is one reason this matters. A category’s first page may show only part of its catalog. Following an eligible next-page link can reveal more products, while a page limit keeps the test manageable.

Crawling is also separate from indexing. Google’s explanation of how Search works distinguishes downloading pages from analyzing and storing their content in an index. Discovery or retrieval does not guarantee inclusion in search results. Your own crawler may only need to produce an inventory, with no search index involved.

For web scraping vs web crawling projects, keep that inventory inspectable. Save the discovered address and enough visit information to investigate failures. Our GoSpider crawling guide shows how a dedicated discovery tool fits into a larger collection workflow. The crawler’s job is complete when it has reached the pages defined by your scope, rather than when it has explored every link it encounters.

How a Web Scraper Extracts Useful Fields

A product page contains more than a price. It may include navigation, related products, customer reviews, and several prices for different editions. A scraper needs rules that separate your desired fields from everything else.

The process starts with parsing, reading the page structure so you can locate relevant elements. A CSS selector can identify an element by its type, class, or other attributes. For example, the browser’s querySelector method returns the first matching element, or no element if nothing matches. That behavior is why a scraper needs to handle missing fields explicitly.

A typical extraction job does the following:

  1. Retrieve the page content.
  2. Locate the elements containing the required fields.
  3. Read their values.
  4. Normalize those values into your chosen format.
  5. Validate the record before saving it.

A displayed price of €18.50, for instance, could become 18.50 in a numeric field and EUR in a separate currency field. Decide whether you need the current price, original price, or both before building the extraction rule.

CSS selectors are one option; XPath web scraping provides another way to locate content within document structures. Neither approach replaces checking whether the desired data actually arrived. If a page adds fields through JavaScript, a headless browser may be useful for rendering before extraction.

This is the data-quality side of web scraping vs web crawling. An address can be correct and a download can succeed while the extracted price is missing or belongs to another edition. Validate the values, not just the request result.

Suppose you want a small dataset of programming books. The domain books.example, book titles, and values below are fictional. They illustrate the workflow without suggesting that we ran a live collection job.

Discover the relevant addresses

Give the crawler the category address https://books.example/category/programming. Allow that category’s pagination and product pages on the same domain. Exclude unrelated categories from this exercise and set a small page limit before starting.

The discovery stage might produce these addresses:

https://books.example/book/python-foundations
https://books.example/book/practical-web-data

These URLs are the handoff to extraction. They tell you where to look, but they do not yet answer which book costs what.

Extract and validate each record

For this exercise, define five fields: source URL, title, author, price, and currency. An illustrative extracted record could look like this:

{
  "url": "https://books.example/book/python-foundations",
  "title": "Python Foundations",
  "author": "Taylor Reed",
  "price": 18.5,
  "currency": "EUR"
}

Keep missing values distinct from genuine values. If no price appears, flag the record for review instead of saving zero. If two editions share a title, preserve the identifying address rather than merging them by title alone. A useful rule is to store enough context to find the exact source item again.

Combine the jobs without confusing them

One program can handle both responsibilities. The Scrapy tutorial demonstrates extracting data and following next-page links within the same spider. Separate applications are optional; clear responsibilities are what make problems easier to investigate.

For this bookstore exercise, review the address inventory and the records independently. A missing book may indicate a discovery problem. A present book with the wrong price suggests an extraction problem. Web scraping vs web crawling is a practical distinction because those failures need different fixes.

Choose a Workflow and Test a Small Batch

Choose the simplest workflow that can produce your desired result. Knowing the exact page addresses often removes the need for a separate discovery step.

Starting situation

Useful first approach

You have a fixed list of product URLs

Retrieve and scrape those pages

You need to locate pages in a category

Crawl within explicit boundaries

You need records from a changing catalog

Combine discovery and extraction

You need a page inventory for an audit

Crawl and retain relevant visit information

A suitable export or documented API is available

Evaluate that interface before collecting page content

A web scraping vs web crawling decision should also account for what you are comfortable maintaining. A parser needs field-selection rules. A crawler needs navigation and stopping rules. A framework can bring these capabilities together, while a hosted service can take responsibility for particular parts of the work.

Start on a site you control or a practice environment intended for scraping. Pick one page and write down the expected fields before running anything. Compare its extracted record with the source, then expand to a small batch that you can still review manually.

Define success for that batch in concrete terms: the expected pages were reached, required fields are present, and sampled prices match the intended products. This is more useful than counting successful requests alone.

Once the batch works, change one dimension at a time, such as the number of pages or the category you cover. That makes it easier to connect an unexpected result to the change that introduced it.

Avoid Common Crawling and Scraping Mistakes

Broad link discovery can grow beyond the task you intended. Filters, calendars, and repeated navigation can generate many addresses. Set boundaries and a stopping condition before increasing coverage.

Duplicate handling requires care, too. Some URL parameters merely track a visit; others select a different product edition or region. Check what a parameter changes before removing it. Similarly, identical titles do not prove that two records describe the same item.

Respect the site’s crawling instructions. The Robots Exclusion Protocol standard explains that robots.txt rules are not access authorization. An allowed path should not be treated as blanket permission to access or reuse its content. Keep the collection within the scope you are authorized to run.

Watch response signals as well as extracted data. HTTP 429 means the client has sent too many requests within a period. A Retry-After header may indicate when to try again. Honor that signal rather than immediately repeating the same request in a tight loop.

Finally, measure comparable work. One request for a known page and a crawl discovering hundreds of pages are different jobs. Rendering requirements, page volume, extraction complexity, and request pacing affect the time and resources needed. Web scraping vs web crawling has no universal speed winner. Track discovered URLs, retrieved pages, and valid records separately so you can see where time goes and where the job needs attention.

Key Takeaways

  • Start with the result you need. An inventory of pages calls for discovery; a table of prices also needs field extraction.
  • Keep crawling bounded with allowed domains, relevant paths, and an explicit stopping limit. Review the discovered URLs before expanding coverage.
  • Define required fields before scraping. Treat a missing value as a problem to inspect, rather than replacing it with a plausible-looking default.
  • Check discovery, retrieval, and extraction independently. A successful request does not prove that the correct record was produced.
  • Expand a small, verified batch gradually so you can understand why results change.

FAQ

Can I extract data from HTML files saved on my computer?

Yes. You can parse saved HTML without retrieving the page again, provided the file contains the fields you need. Keep the original URL and download time alongside it so the extracted values remain traceable. If the file was saved before JavaScript added the relevant content, that content will not appear simply because you parse the file later.

A crawler needs another source for that address, such as a sitemap or an explicit seed list. Link-following alone cannot reveal a page that none of the visited pages points to. When completeness matters, compare discovery results with an authoritative inventory you can access. An empty queue means the available exploration finished; it does not prove that every page was found.

How often should I revisit a page?

Set the revisit schedule according to how fresh your dataset needs to be and the source’s operating limits. A one-time archive and a daily price report have different requirements. Record collection times and observe whether the fields actually change between visits. Use those observations to refine the schedule instead of assuming that more frequent collection always produces more useful data.

Do I need to learn Python to start?

No. Crawling and scraping are tasks rather than features of one programming language. You can use another language you already know, such as web scraping in R, or a tool that provides the required workflow through a visual interface. You still need to define the pages and fields you want, inspect the resulting records, and understand which parts of the process the tool handles for you.

Conclusion: Build the Smallest Workflow That Produces Useful Data

The useful outcome of a collection project is data you can understand and check. Web scraping vs web crawling describes two responsibilities that help you reach that outcome: finding relevant pages and extracting the information you need from them.

If you already have the addresses, start by testing extraction on one page. If the addresses are missing, define a limited discovery job first. In either case, decide what a valid record looks like before increasing the volume. The bookstore example works because the output fields and the intended page scope are clear enough to inspect.

Keep the handoff visible as the project grows. Record which pages were discovered, which were retrieved, and which produced valid data. That evidence helps you distinguish a navigation problem from a missing field or a failed request, and it gives you a concrete starting point for fixes.

If page retrieval becomes the part you need help operating, explore the Scraper API from WebScrapingAPI. It can handle the retrieval layer while you keep your collection scope and data checks explicit. Start with a representative page and judge the result against the fields your project actually needs.

About the Author

Anda Miuțescu, Technical Content Writer @ WebScrapingAPI

Anda Miuțescu

Technical Content Writer

Anda Miuțescu is a Technical Content Writer at WebScrapingAPI, creating clear, useful content that helps developers understand the product and its capabilities.

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production
Science of Web Scraping

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production

TL;DR: Nodriver is an async Python library that drives Chromium over the Chrome DevTools Protocol, with no Selenium or chromedriver binary. Use it when a self-hosted stealth browser closer to a real Chrome session beats a WebDriver stack, but know it doesn't remove IP, TLS, or behavioral risk on its own. This tutorial goes from a first script to containerized production and a hosted Browser API.

Suciu Dan11 min read
Read Article
How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper
Science of Web Scraping

How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper

TL;DR: Google /goto URLs with a CAES token, and older /url wrappers, are redirect layers, not destinations, so a SERP scraper that treats every href as final breaks rank tracking and link stores. Prefer a structured SERP API when it returns destination links. When you must parse HTML, classify every href, dedupe redirects, and resolve them with a plain GET. Do not decrypt CAES.

Suciu Dan11 min read
Read Article
HTTP Response Headers in cURL: Every Flag and Recipe
Science of Web Scraping

HTTP Response Headers in cURL: Every Flag and Recipe

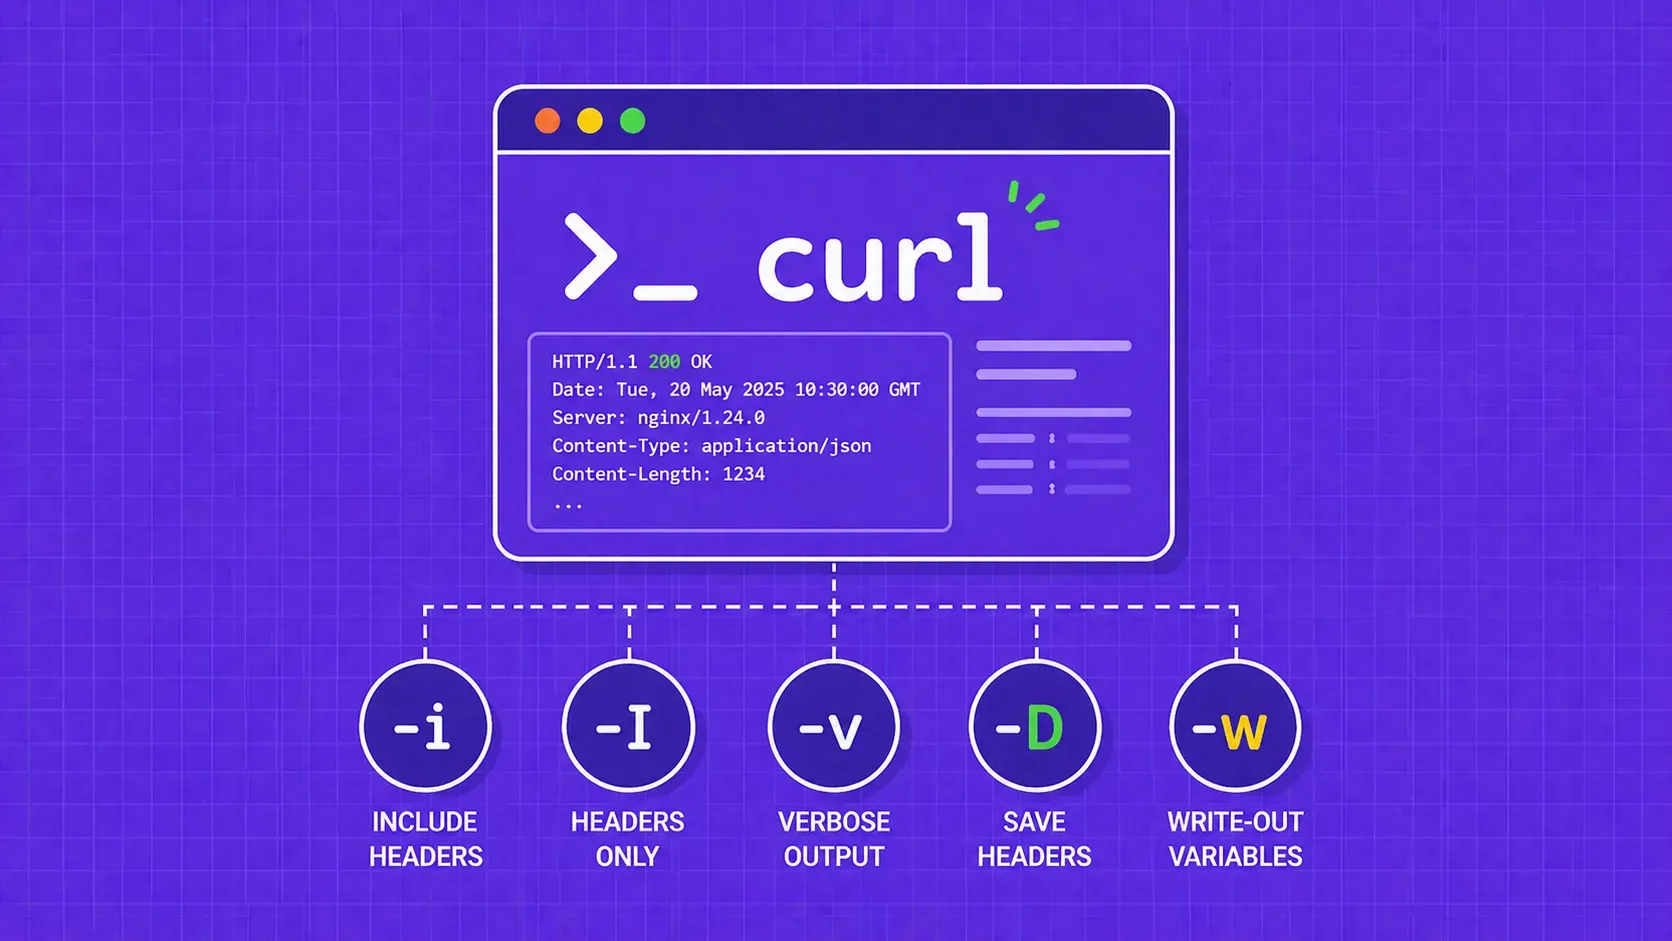
TL;DR: cURL hides response headers by default. Use -i to see headers alongside the body, -I for a HEAD request that returns headers only, -v for full request/response debugging, and -D to save headers to a file. For modern scripting, cURL 7.83+ lets you extract individual headers or dump all of them as JSON with the -w write-out option.

Suciu Dan11 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.