Skip to content
Start free

Blog

Insights & Engineering

Deep dives into web data infrastructure, extraction techniques, and the future of structured data at scale.

Cheerio Web Scraping in Node.js: load() to a Tested Scraper
Guides

Cheerio Web Scraping in Node.js: load() to a Tested Scraper

Raluca Penciuc17 min read
Read Article

Latest Articles

155 articles

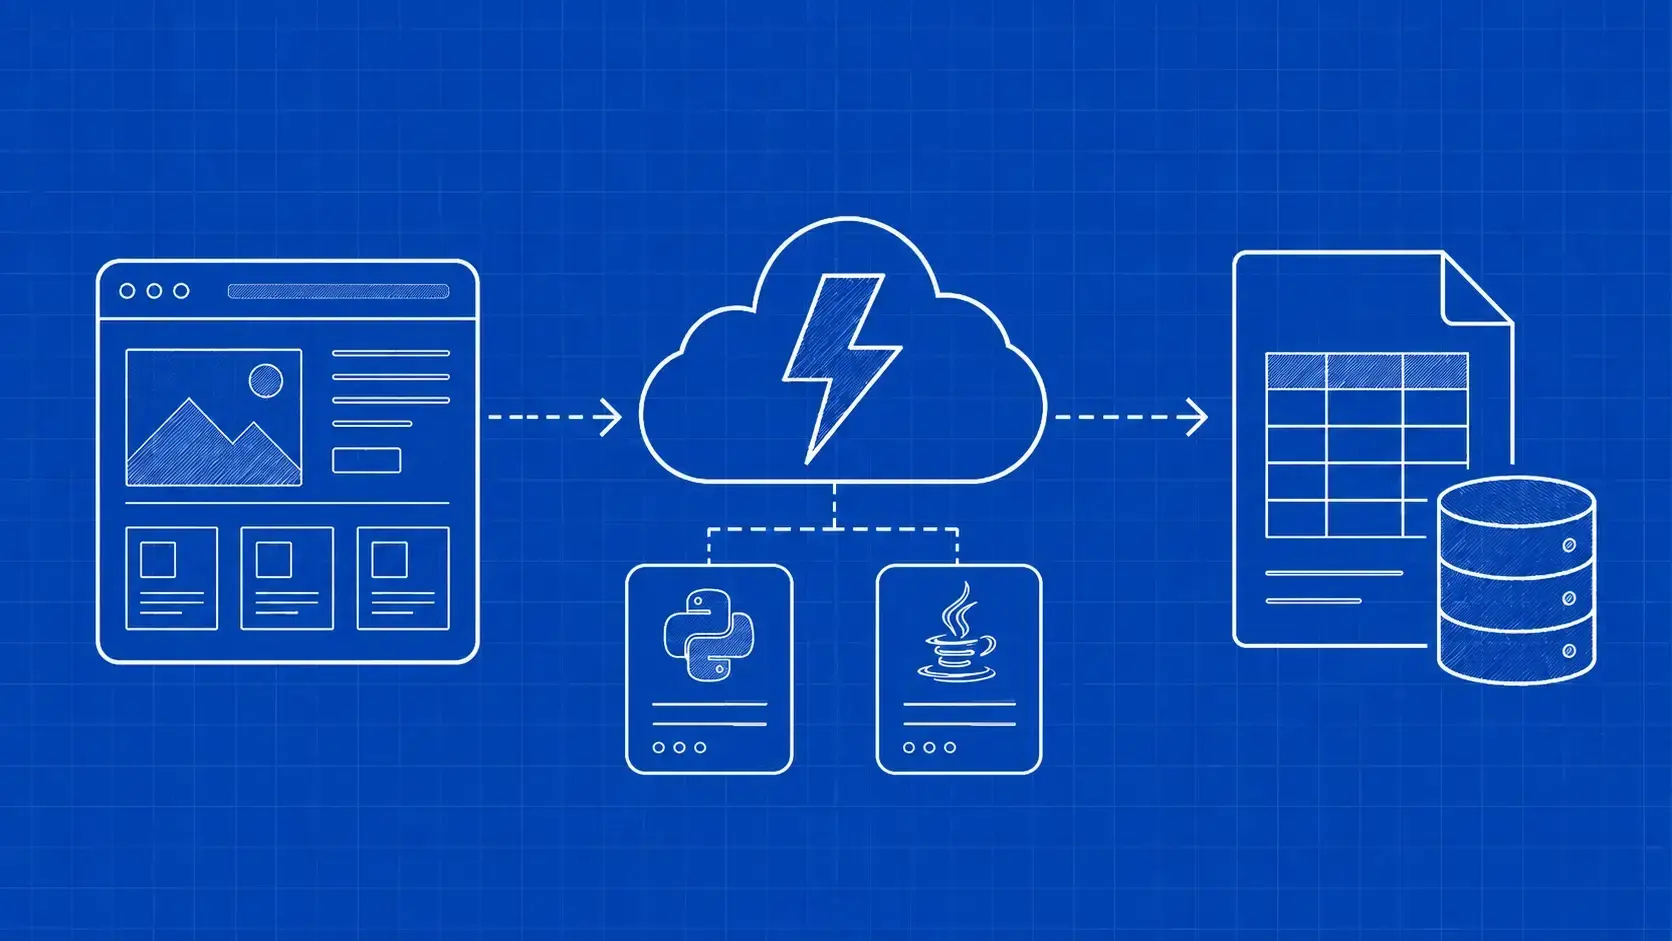
Web Scraping With AWS Lambda: Guide for Python, Java 2026
Guides

Web Scraping With AWS Lambda: Guide for Python, Java 2026

TL;DR: Web Scraping With AWS Lambda works best when each invocation is short, bounded, and independently retryable. Start with direct HTTP, AWS SAM, and S3, then add SQS, containers, browser rendering, proxies, or a managed fetch layer only when the workload proves it needs them.

Suciu Dan24 min read
Read Article
How To Use GoSpider: Crawl, Clean URLs, and Extract Data
Guides

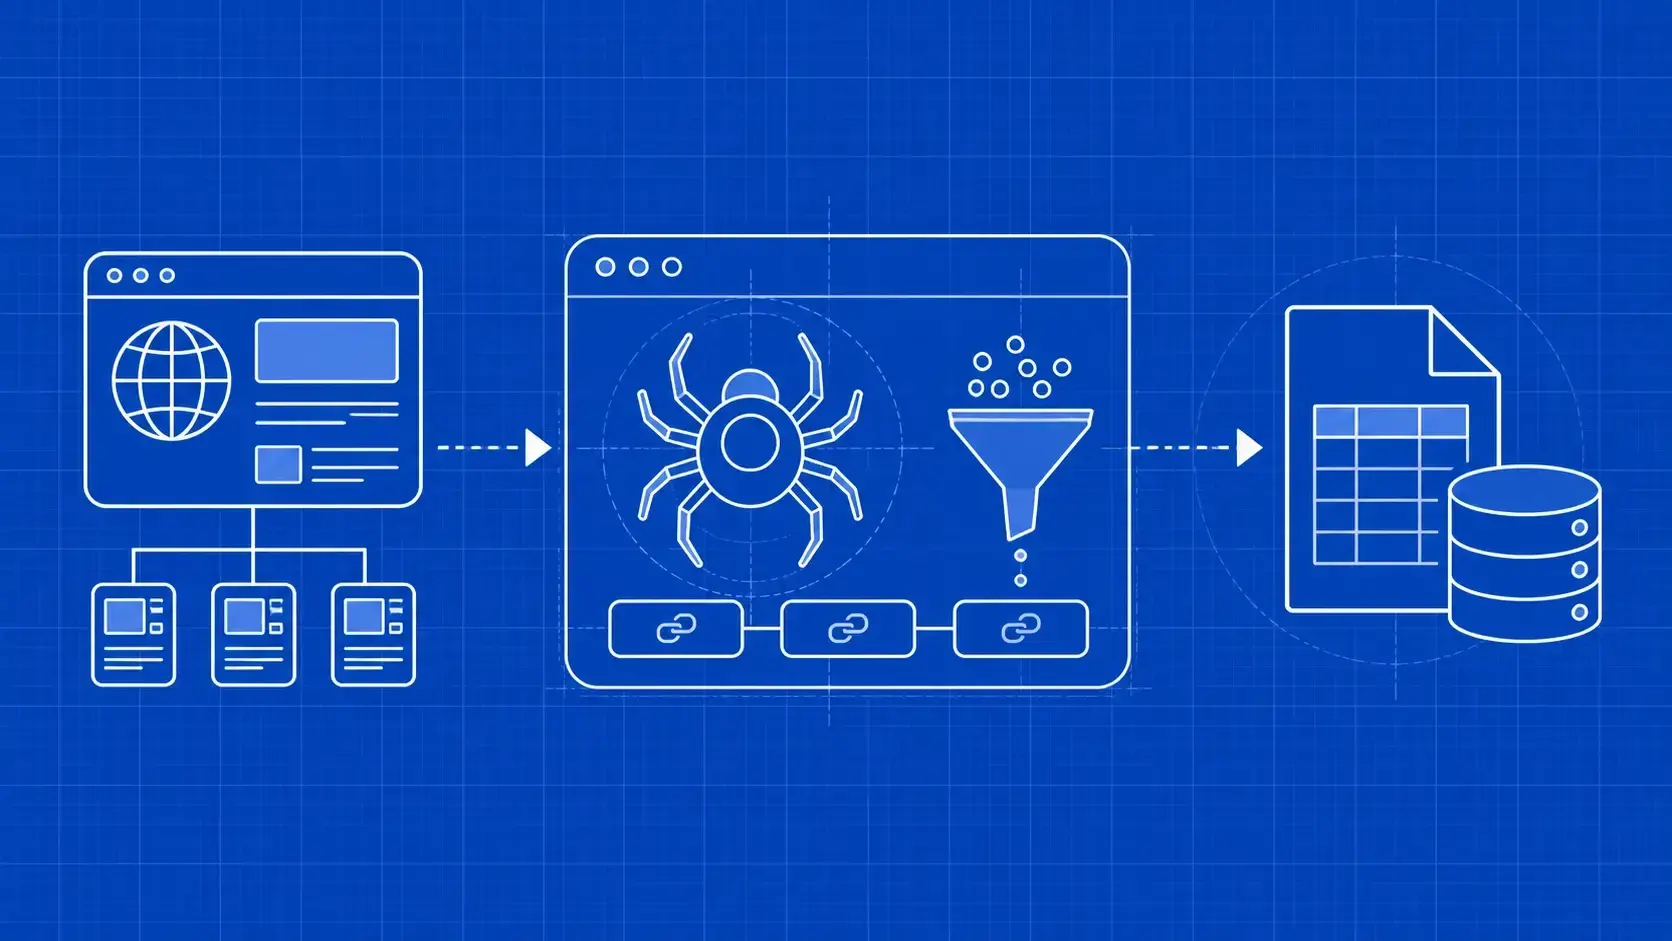
How To Use GoSpider: Crawl, Clean URLs, and Extract Data

TL;DR: GoSpider is a command-line crawler for discovering URLs, not a complete structured-data scraper. This How To Use GoSpider guide shows a bounded crawl, clean output handling, a Colly-to-CSV handoff, and a diagnostic path for 403 responses or pages that require JavaScript rendering.

Suciu Dan18 min read
Read Article
How to Scrape Redfin: Python Guide to Property Data
Guides

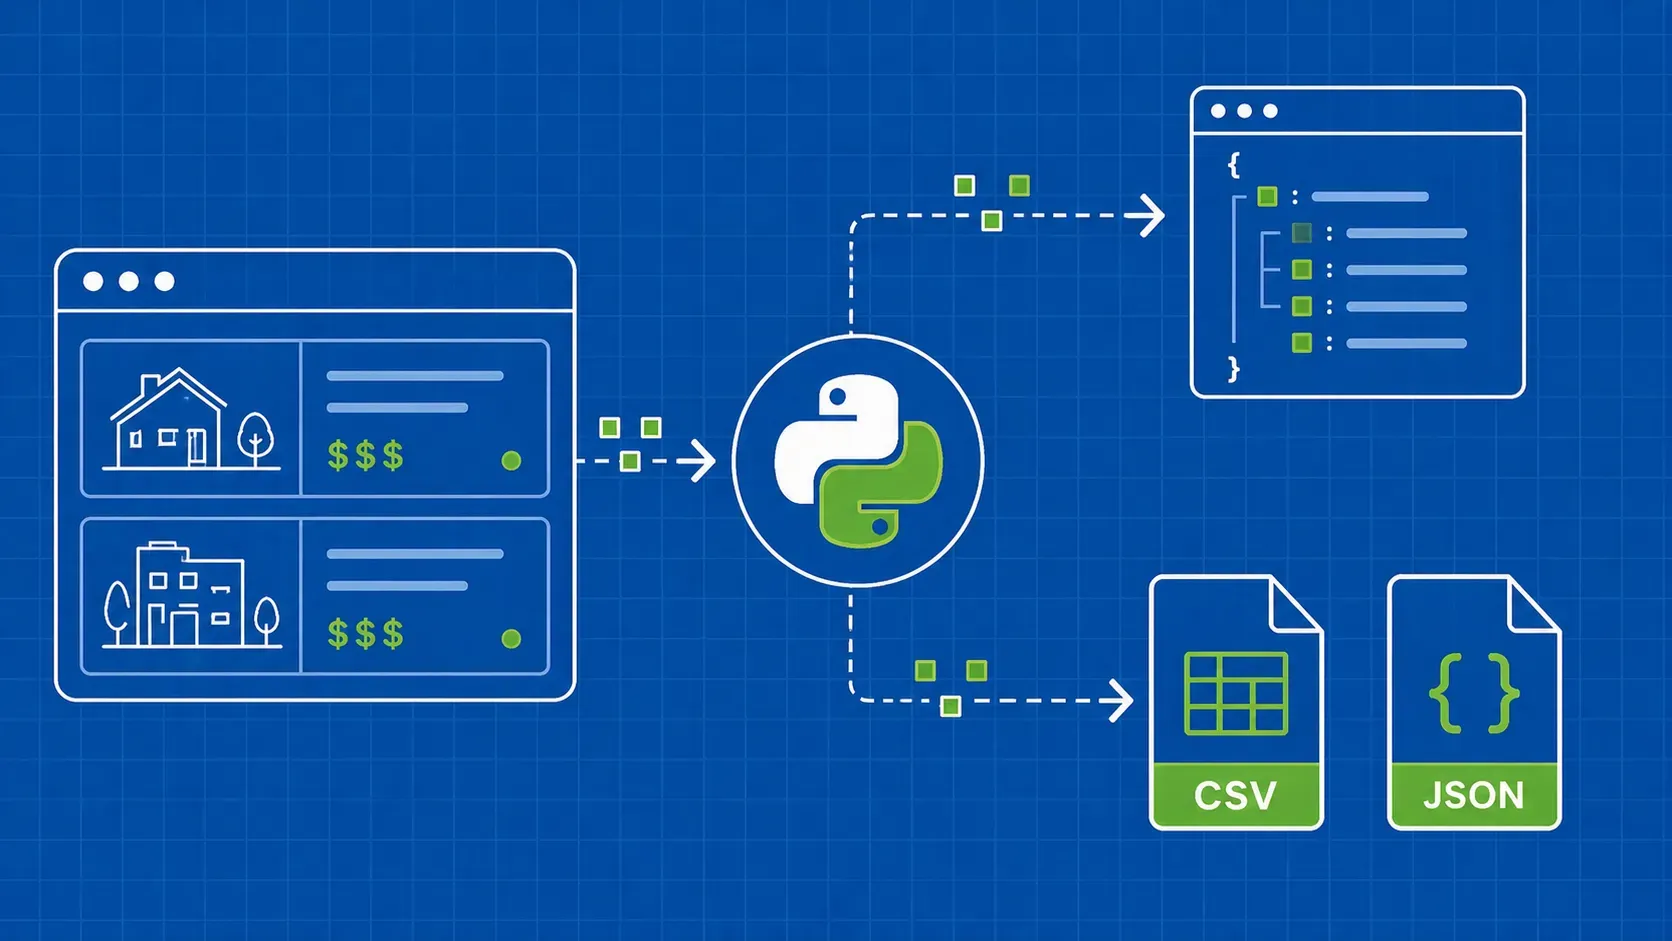
How to Scrape Redfin: Python Guide to Property Data

TL;DR: Redfin exposes hidden API endpoints that return structured JSON for property listings, making it possible to skip fragile HTML parsing entirely. This guide walks you through building a Python scraper that extracts rental and sale data, searches by location, monitors new listings via XML sitemaps, and exports clean results to CSV or JSON.

Suciu Dan11 min read
Read Article
How to Parse JSON in Python: From API Responses to JSON Hidden in Web Pages
Guides

How to Parse JSON in Python: From API Responses to JSON Hidden in Web Pages

TL;DR: To parse JSON in Python, use the built-in json module: json.loads() for a string or bytes, json.load() for a file, and Requests' response.json() for an HTTP response. Check the HTTP status and JSON validity separately, because a 200 response can still be HTML. This guide also covers decode errors, nested access, validation, large files, and JSON hidden inside web pages.

Suciu Dan11 min read
Read Article
Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production
Science of Web Scraping

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production

TL;DR: Nodriver is an async Python library that drives Chromium over the Chrome DevTools Protocol, with no Selenium or chromedriver binary. Use it when a self-hosted stealth browser closer to a real Chrome session beats a WebDriver stack, but know it doesn't remove IP, TLS, or behavioral risk on its own. This tutorial goes from a first script to containerized production and a hosted Browser API.

Suciu Dan11 min read
Read Article
How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper
Science of Web Scraping

How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper

TL;DR: Google /goto URLs with a CAES token, and older /url wrappers, are redirect layers, not destinations, so a SERP scraper that treats every href as final breaks rank tracking and link stores. Prefer a structured SERP API when it returns destination links. When you must parse HTML, classify every href, dedupe redirects, and resolve them with a plain GET. Do not decrypt CAES.

Suciu Dan11 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.