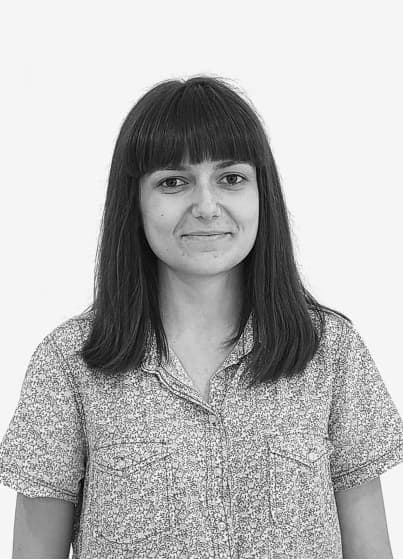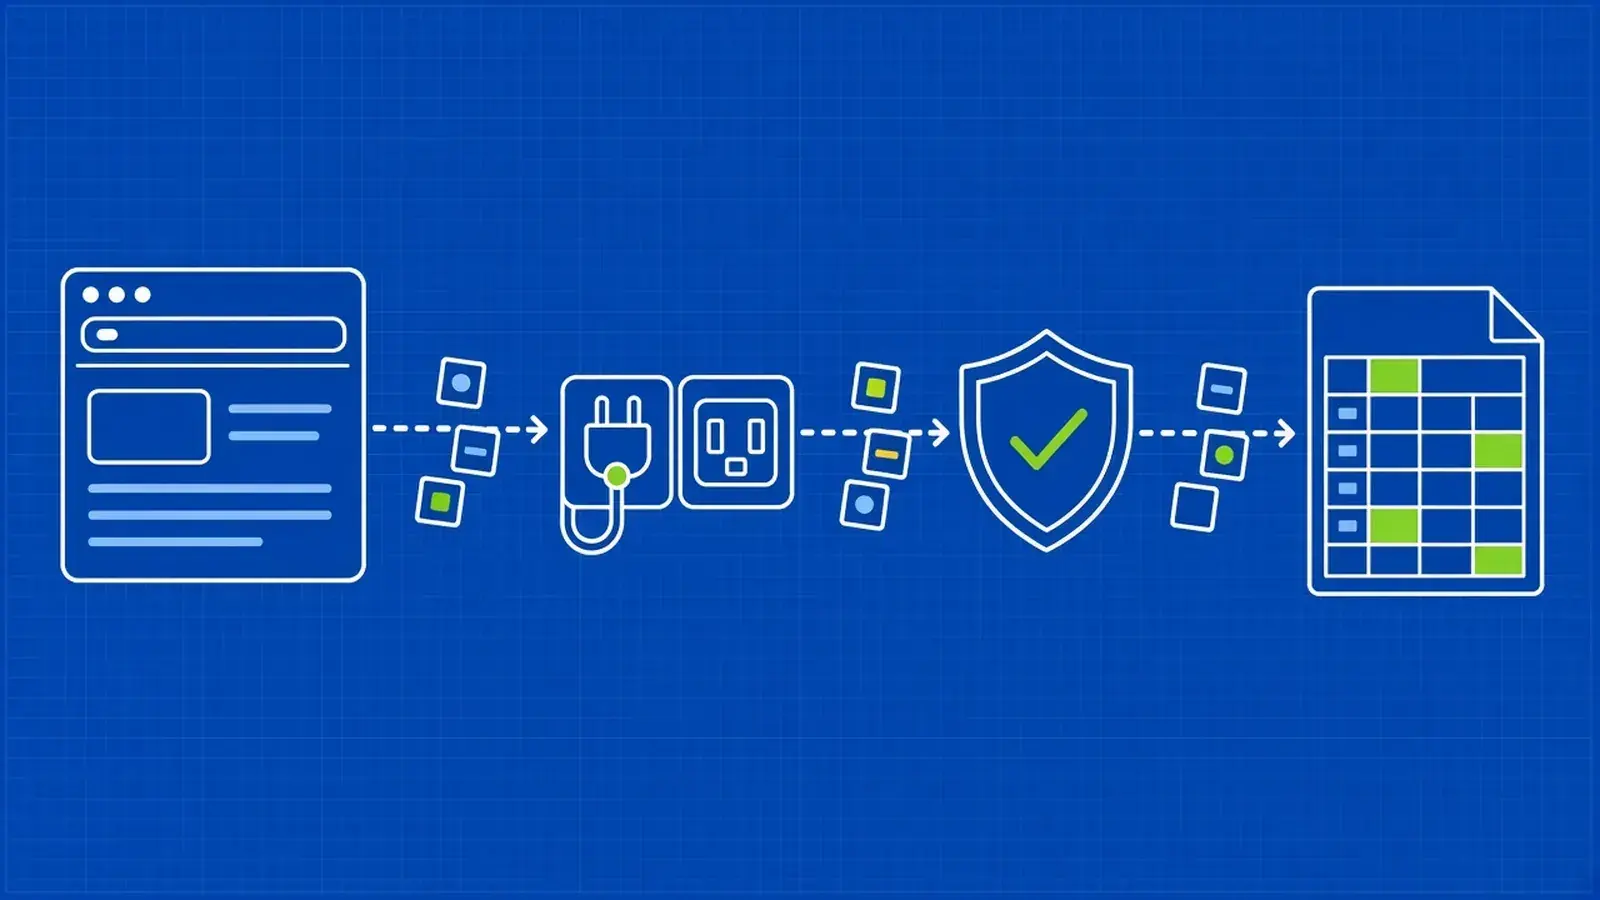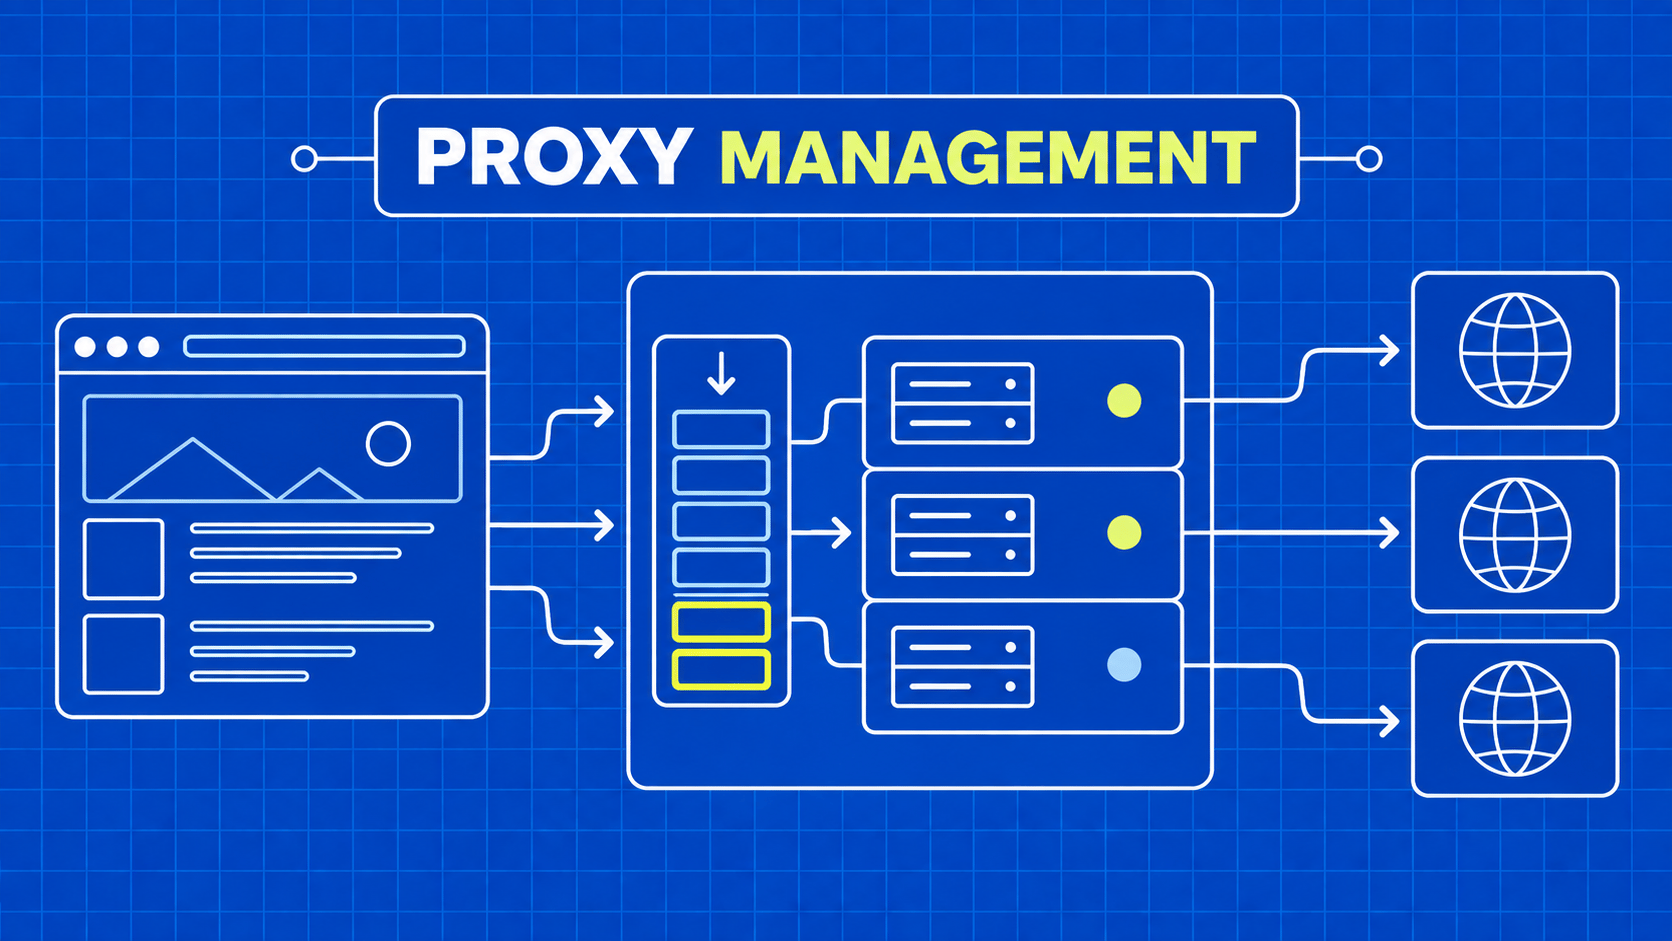
TL;DR: Proxy management for web scraping is the policy layer that assigns permitted work to suitable network routes and tracks what happens afterward. Keep session state, route health, and source request budgets separate. Rotate or retire a route for a documented operational reason, not as an automatic response to every unsuccessful page.
A worker receives an empty product page and marks its proxy dead. Another worker immediately takes a fresh route and repeats the request. After several attempts, the pool looks unhealthy, but the actual failure is a parser expecting an element the source removed.
That is a management problem before it is a networking problem. The system made a routing decision using evidence from the wrong layer. Adding more addresses would make the mistake larger, not more correct.
A useful proxy manager does more than pick the next endpoint. It knows which work requires continuity, which routes meet the approved location requirement, how much traffic the source can receive, and when an operator must review a failure. Its success is measured by valid observations delivered within the collection policy, not by how often it changes addresses.
This guide describes that design for developers operating authorized collectors. The examples are original architecture recommendations, not a provider benchmark. You can apply the same boundaries to a small configuration-backed worker or a larger shared collection service.