Skip to content
Start free

Blog

Insights & Engineering

Deep dives into web data infrastructure, extraction techniques, and the future of structured data at scale.

Latest Articles

155 articles

SERP Scraping API Guide: Google, Bing, DuckDuckGo, Yandex
Guides

SERP Scraping API Guide: Google, Bing, DuckDuckGo, Yandex

TL;DR: To use the SERP Scraping API, send a GET request to https://serpapi.webscrapingapi.com/v2 with api_key, engine, and your query (q for most engines, text for Yandex). Google and Bing return parsed JSON, while DuckDuckGo and Yandex return the results page's HTML for your code to extract, so plan parsing and tests around that split. This guide also covers localization, async jobs, errors, and pricing.

Suciu Dan20 min read
Read Article
How to Use the Amazon Scraper API: Quick Start Guide
Guides

How to Use the Amazon Scraper API: Quick Start Guide

TL;DR: To use the Amazon Scraper API, send a GET request to https://ecom.webscrapingapi.com/v1 with api_key, engine=amazon, a request type, and that type's input, such as an ASIN in product_id or a keyword in q. Use product for one ASIN, search for a keyword, bestsellers or todays-deals for a category ID, and seller_products or seller_feedback for a seller ID. This guide covers all nine request types, 20 marketplaces, errors, and plans.

Robert Sfichi19 min read
Read Article
Scrapy vs Selenium: Who Wins in 2026?
Science of Web Scraping

Scrapy vs Selenium: Who Wins in 2026?

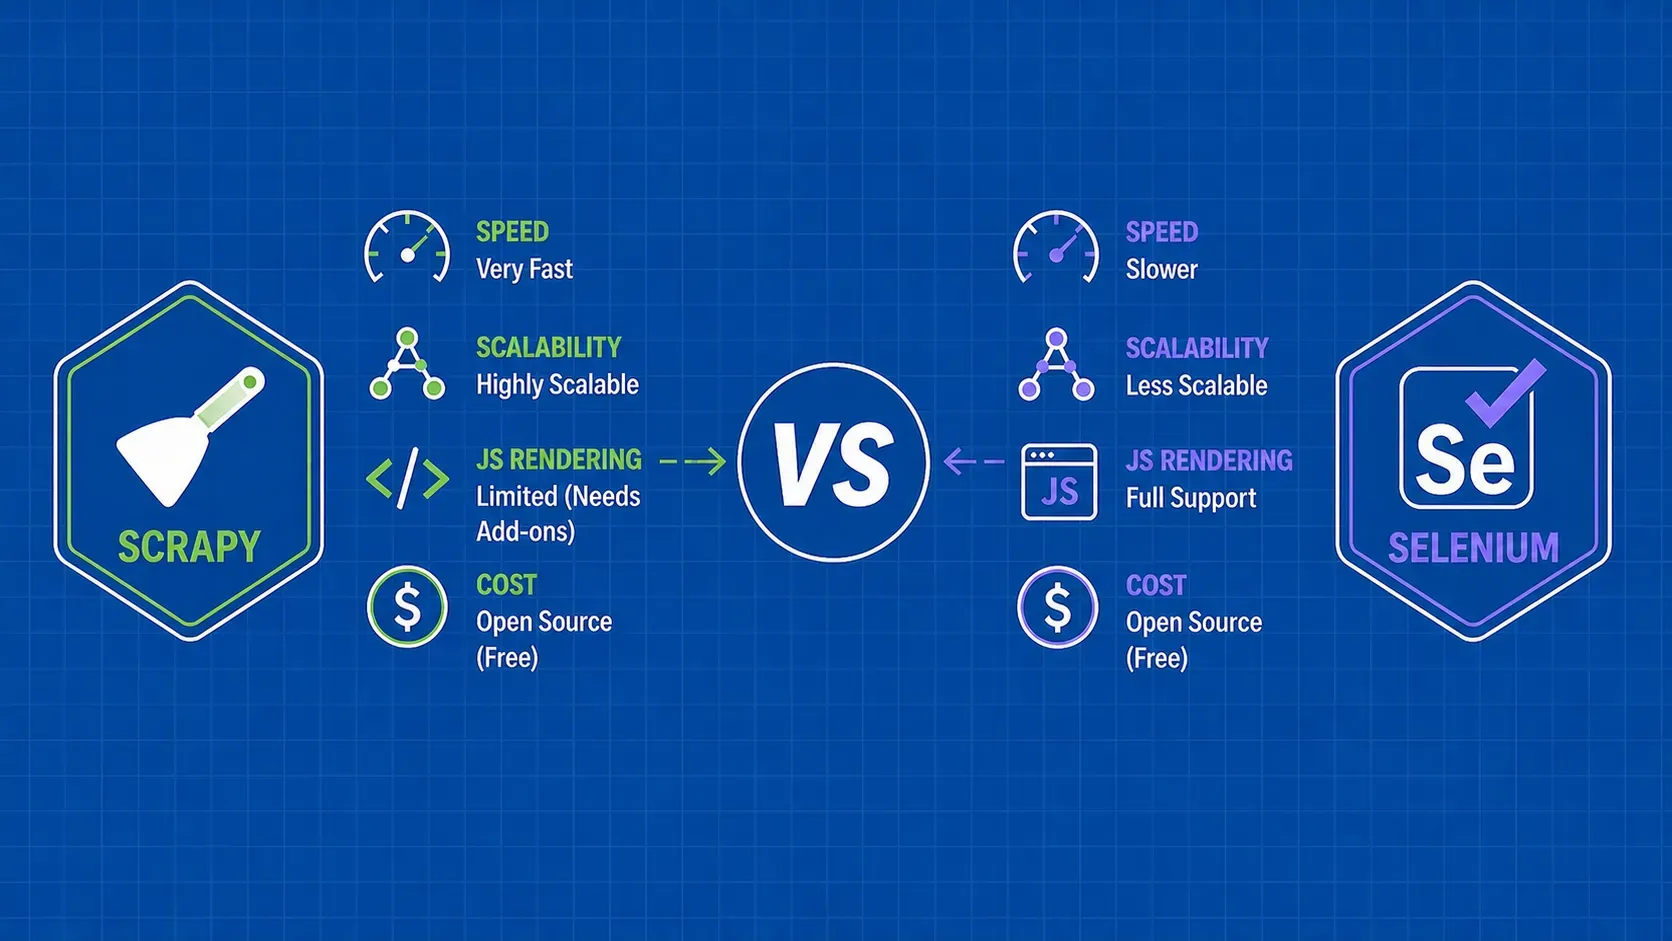
TL;DR: Scrapy is a high-speed, asynchronous crawling framework built for extracting structured data from static pages at scale. Selenium automates real browsers and handles JavaScript-heavy sites, but at a much higher resource cost. Most production scraping projects benefit from knowing when to use each, or when to combine them.

Gabriel Cioci9 min read
Read Article
Scrapy vs Beautiful Soup: Which Python Scraper to Pick
Guides

Scrapy vs Beautiful Soup: Which Python Scraper to Pick

TL;DR: Scrapy is a full crawling framework that handles requests, parsing, and data export in one package. Beautiful Soup is a lightweight parsing library you pair with an HTTP client like requests. Choose Scrapy when you need large-scale, concurrent crawling with built-in pipelines. Choose Beautiful Soup when you want a fast, minimal setup for parsing a handful of pages.

Mihnea-Octavian Manolache10 min read
Read Article
Scrapy Splash Tutorial
Guides

Scrapy Splash Tutorial

TL;DR: Scrapy Splash pairs Scrapy's fast crawling engine with the Splash headless browser to render JavaScript-heavy pages. This scrapy splash tutorial walks you through Docker setup, Scrapy project configuration, SplashRequest basics, Lua scripts for scrolling and clicking, proxy integration, and fixing the most common errors you will encounter.

Ștefan Răcilă11 min read
Read Article
Scrape Amazon Product Data with Python: Hands-On Guide
Guides

Scrape Amazon Product Data with Python: Hands-On Guide

TL;DR: Amazon product pages are packed with valuable data (prices, ratings, reviews, ASINs), but extracting it reliably requires more than a basic HTTP request. This guide walks you through building a Python scraper with Requests and BeautifulSoup, handling pagination and anti-bot defenses, exporting to CSV or JSON, and feeding the results into LLM workflows. You will also learn when to use a scraping API instead of rolling your own solution.

Raluca Penciuc15 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.