Skip to content
Start free
Back to Blog

Real Estate Web Scraping with Python: Collect Property Data

Robert MunceanuLast updated on 21 min read
Real Estate Web Scraping with Python: Collect Property Data
TL;DR: Real estate web scraping collects listings, prices, and property details from websites into structured data. Before you scrape, check for open data, an MLS feed, or a data API, because Zillow, Realtor.com, and Redfin ban automated collection in their terms. This guide covers the data model, sources, legal limits, Python code, and quality checks.

Sooner or later someone asks you to "get property data" for a market: asking prices for comps, inventory for a report, or a feed of new listings. Real estate data is all over the web, so scraping looks like the obvious answer. Two mistakes sink most of these projects. The first is scraping a portal whose terms forbid it. The second is treating an asking price as a sale price and building analysis on the wrong number.

Start with the decision: what data exists, which source fits each job, and what the major portals allow. Then build a Python scraper with requests, BeautifulSoup, and pandas on a sample page you control and pull real house prices from a free open-data file.
What is real estate web scraping?

Real estate web scraping is the automated collection of property information from websites, such as listing prices, addresses, bedrooms, square footage, photos, and days on market. A scraper fetches pages, extracts the fields, and saves them as rows in a CSV file or database, so you can compare markets or track changes over time.

Scraping is only one way to get that information. The same numbers often come as free downloads, licensed MLS feeds, or data APIs, and those routes are usually cheaper to maintain and safer to use. Compare the routes before you write a line of code.

What real estate data can you scrape?

Most listing pages show the address, asking price or rent, beds, baths, living area, lot size, property type, status, listing date, photos, and the listing agent. Those fields describe three different things: the property, the listing that advertises it, and each price you observed on a given date.

A home can sit on the market three times in five years, through two brokers, at five different prices. If you store all of that in one row, you lose the history that makes the data useful. Model it in three layers instead:

Layer

What it is

Example fields

Key you dedupe on

Property

The physical home, which rarely changes

Address, parcel number, beds, baths, living area, lot size, year built

Normalized address or parcel ID

Listing episode

One time the home was on the market

Source site, listing ID, status, list date, listing broker, URL

Source + listing ID

Observation

What you saw at one moment

Price, status, days on market, collected_at

Listing ID + timestamp

Prices need the same care. A listing page can show several numbers that look alike but mean different things:

Price type

What it means

Is it a transaction?

Asking (list) price

What the seller wants today; it can drop or rise

No

Sold price

What the buyer paid at closing

Yes

Asking rent

What a landlord wants per period (month or week)

No, and it needs a period

Automated estimate

A model's guess at value, like a Zestimate

No

Tax-assessed value

The value a local authority uses for property tax

No

Keep each type in its own column, or tag every price with its type. Our property listing data uses the same idea: a property, the listings that advertise it, and dated price observations, because an advertisement tells you what someone asked, not what anyone paid.

One more rule before you collect anything: agent names, phone numbers, and email addresses are personal data under most privacy laws. Leave them out unless you have a lawful reason to keep them.

Who uses real estate scraping, and for what?

Agents and brokers use it for comparable sales and pricing. Investors use it to find underpriced properties and track rent yields. Proptech teams build listing feeds and valuation models. Researchers and journalists track inventory and price cuts. Buyers and renters use it to watch a neighborhood. Real estate sits alongside travel, retail pricing, and finance among other web scraping use cases.

What matters is matching each job to the fields it needs and the source that delivers them with the least risk:

Use case

Fields you need

Best first source

Comps and pricing

Sold price, beds, baths, area, sale date

MLS feed through a broker, or licensed data

Market monitoring

Inventory, median list price, days on market by metro or ZIP

Open data downloads

Investment screening

Asking price, rent, taxes, price history

Data API or licensed data, plus open rent indexes

Listing aggregation

Full listing records with photos

MLS IDX or a licensed feed; scraping is the riskiest route here

Lead generation

Owner or agent contacts

Proceed with care: personal data and anti-spam rules apply

Personal home search

Alerts on a handful of listings

The portal's own saved-search alerts

If your job sits in the first three rows, you may not need a scraper at all.

Should you scrape, download, or license real estate data?

Download first if you need market-level numbers, since Zillow, Redfin, and Realtor.com publish free housing data files. License an MLS feed or a data API if you need listing-level records at scale. Scrape only pages whose terms permit it, or your own sites, partners' sites, and public sources that allow automated access.

Route

Gives you

Cost and effort

Access friction

Best for

Watch out for

Open data downloads (Zillow Research, Redfin Data Center, Realtor.com data library, FHFA HPI)

Metro, county, and ZIP aggregates

Free; a few lines of pandas

None

Trends, reports, market screening

Monthly cadence; no listing-level rows

MLS via RESO Web API

Authoritative listing records, including sold data

Licensing fees and agreements

High: membership, broker, or approved vendor

Brokerages, IDX sites, valuation

Display and usage rules

Real estate data API or dataset

Structured listing records without running scrapers

Quote-based

Low to medium

Products that need listings without a parser team

Provider terms, coverage, and freshness

Scraper API

Rendered HTML from pages you're allowed to collect; you write the parser

Pay per request

Low

Brokerage sites, partner feeds, permitted public sources

You still own the parser and the compliance check

DIY scraper (requests, BeautifulSoup, Playwright)

Whatever you build

Your time, servers, and proxies

Low to start, high to maintain

Small, permitted jobs and prototypes

Breakage, blocks, and compliance

Most teams end up mixing routes: open data for the market picture, a feed or API for listing records, and a scraper for the long tail of permitted sites.

Their terms of use prohibit it. Zillow bans "automated queries," including scraping and bypassing captchas. Realtor.com bans screen and database scraping. Redfin bans automated crawling without written permission. Breaking terms can lead to account bans, blocked IPs, or contract claims, even where scraping public pages isn't a crime. Use their data downloads or a licensed source instead.

Here's what each major portal's terms say, in their own words:

Portal

What the terms say

robots.txt

Official alternative

Zillow

Zillow's terms of use (updated October 28, 2025) bar you from conducting "automated queries (including screen and database scraping, spiders, robots, crawlers, bypassing 'captcha' or similar precautions…)." Copying is allowed only "without the aid of any automated processes." Aggregate Local-Info data may be reused with the credit "Data Provided by Zillow Group."

Long file with path-level rules

Zillow Research data downloads; Zillow Group APIs under their own terms

Realtor.com

The Realtor.com terms of service ban "screen scraping" and "database scraping," and collection "by automated means" such as a "robot, spider, script." They add that robots.txt settings don't expand your rights.

Present, but doesn't override the terms

Realtor.com residential data library (CSV)

Redfin

Redfin's terms of use include "No Scrubbing or Scraping": no automated crawling or querying "unless you have received prior express written permission." MLS notices on listing pages repeat the ban.

Present, with path-level rules

Redfin Data Center downloads

Rightmove (UK)

The Rightmove terms of use site footer states: "Rightmove prohibits the scraping of its content."

The terms ban applies whatever robots.txt says

Ask Rightmove for written permission

Other portals (Zoopla, Idealista, realestate.com.au, Domain, Homes.com)

Read each site's terms page before you collect anything

Check per site

Check per site

In the US, the Ninth Circuit held in hiQ Labs v. LinkedIn (2022) that scraping publicly accessible pages likely isn't "access without authorization" under the Computer Fraud and Abuse Act. That ruling doesn't cancel the other rules. Terms of use are contracts, listing photos and descriptions are copyrighted, and privacy laws cover the people in the data. Zillow's own terms say it doesn't claim copyright in listing images and descriptions. The owners do. Outside the US, the EU's database rights and the GDPR add their own limits.

This isn't legal advice. Ask counsel before you collect data from a site whose terms forbid it. For a wider overview, read the legal basics of web scraping.

Can you scrape MLS data?

No, not legitimately. MLS data is licensed to members, and IDX rules let brokers display listings to consumers, but they don't let others copy them. The legitimate route is a RESO Web API feed, which you get through MLS membership, a broker partner, or an approved data vendor. Portals' MLS-sourced pages carry the same restrictions.

The RESO Web API is a standard, not a data source. RESO publishes a shared data dictionary, so fields such as ListPrice, StandardStatus, and BedroomsTotal mean the same thing in every compliant MLS. The Web API delivers those fields over REST, following the OData conventions. You still need someone to grant you access. The usual paths are:

  • Broker of record. A licensed brokerage you work for or partner with requests the feed from its MLS.
  • MLS-approved vendor. Many MLSs license data to technology vendors under a vendor agreement.
  • Multi-MLS aggregators. Companies that hold agreements with many MLSs and resell normalized access.

Two more acronyms come up often. IDX (Internet Data Exchange) lets participating brokers show each other's listings on their own websites. A VOW (virtual office website) shows more detail to a broker's registered clients. Both are display programs with rules set by the MLS. Neither lets a third party copy the listings into its own database.

Once you have credentials, a request looks roughly like this. It shows the shape only. Your MLS gives you the endpoint and the fields you're licensed to read.

import os

import requests

# Shape only: your MLS or data vendor supplies the endpoint, token, and fields.
BASE_URL = os.environ["RESO_BASE_URL"]
TOKEN = os.environ["RESO_ACCESS_TOKEN"]

response = requests.get(
    f"{BASE_URL}/Property",
    headers={"Authorization": f"Bearer {TOKEN}"},
    params={
        "$select": "ListingKey,ListPrice,StandardStatus,BedroomsTotal,City",
        "$filter": "StandardStatus eq 'Active' and City eq 'Springfield'",
        "$top": 100,
    },
    timeout=30,
)
listings = response.json()["value"]

The $select, $filter, and $top parameters come from OData, so the same pattern works across RESO-certified servers with small differences in filter syntax.

How do real estate scrapers work?

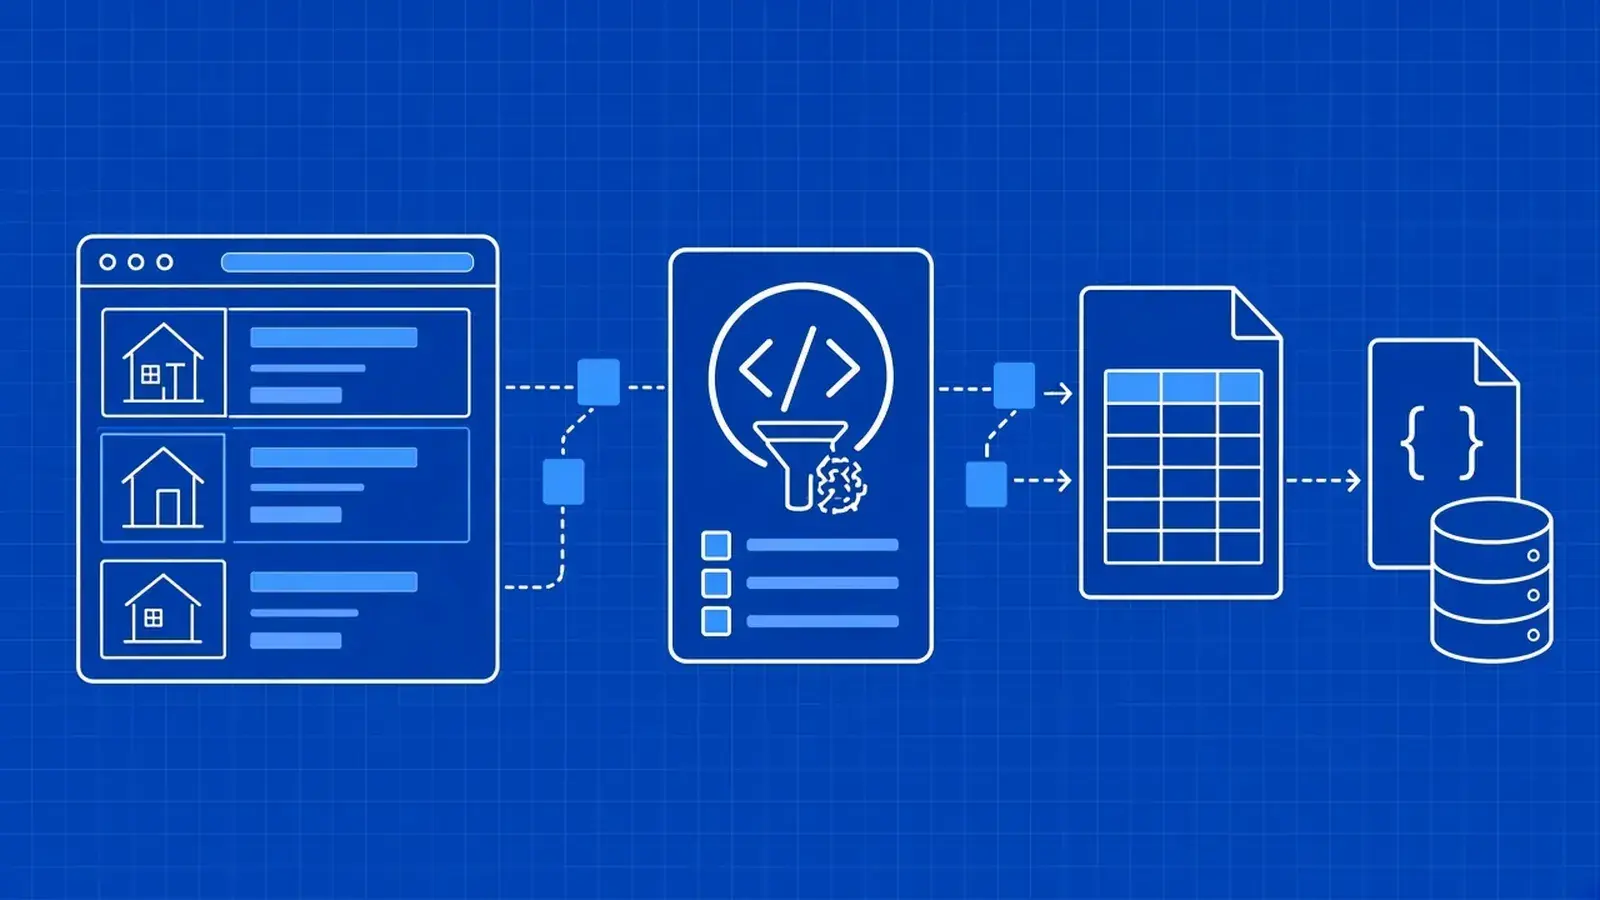
A real estate scraper works in five steps. It discovers listing URLs from search or sitemap pages, fetches each page, rendering JavaScript when needed, then extracts fields from structured data or HTML. Next it normalizes prices, areas, and addresses. Finally, it stores each observation with a timestamp, so later runs can detect price and status changes.

Discover listing URLs

Listing URLs come from sitemaps, search result pages, and pagination links. Search pages often stop after a fixed number of results, so split large areas into smaller ones by ZIP code or price band. Don't crawl every filter combination. Sort orders and filters multiply into millions of URLs that mostly repeat the same listings. When a site you're allowed to collect publishes a sitemap, start there: it lists canonical listing URLs, and the lastmod dates tell you which pages changed since your last run.

Fetch pages

Some sites send complete HTML. Others build the page in the browser with JavaScript. Fetch the static version when you can, because it's faster and cheaper. Cache responses, keep request rates low, and honor robots.txt, as described in the Robots Exclusion Protocol. Remember that robots.txt never grants permission the terms deny.

Extract fields

Check sources in this order. First, JSON-LD blocks that use schema.org types such as RealEstateListing or SingleFamilyResidence. Second, JSON embedded in script tags by the site's front-end framework. See how to parse JSON embedded in a page. Third, HTML selectors. Structured data changes less often than markup, so your scraper breaks less.

Normalize and dedupe

Turn "$1,250,000" into 1250000 plus a currency. Convert all areas to one unit. Make the rent period explicit. Normalize addresses so the same home matches across sources, and dedupe on that normalized address or a parcel ID.

Store observations and detect changes

Append a new row on every run instead of overwriting the old one. Keep collected_at, the source URL, and the raw value next to the parsed one. Comparing today's rows with last week's shows price cuts, status changes, and new listings. In pandas, that's a merge on listing ID between two runs: rows only in the new run are new listings, rows only in the old run went off market, and rows in both with a different price are price changes.

How do you scrape real estate data with Python?

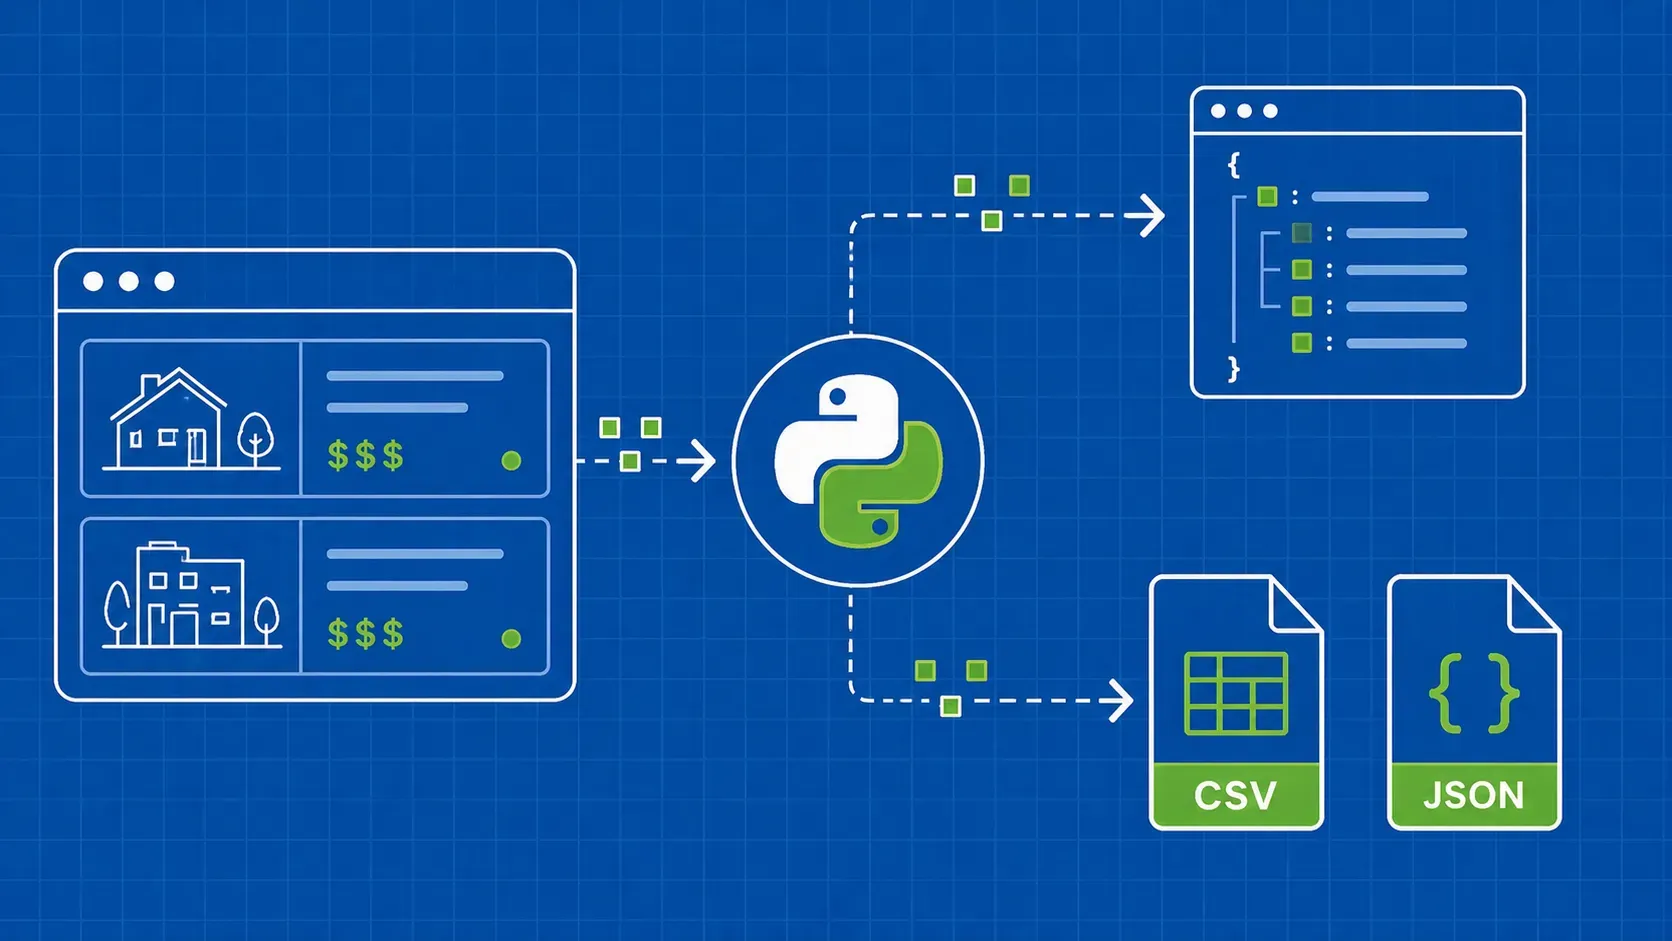
Install requests, BeautifulSoup, and pandas. Fetch a listings page you're allowed to collect, read its JSON-LD first, and fall back to HTML selectors for missing fields. Convert prices and areas to numbers, drop duplicate listings, and export to CSV. Use a scraper API when pages need JavaScript rendering or location-specific results.

The tutorial uses a small sample site with fictional listings, so you can run every step without touching anyone's servers. The same code works on your brokerage's own site or a partner's pages once you swap the selectors.

Set up the project

You need Python 3.12 or newer. Create a folder, a virtual environment, and install the four packages:

mkdir property-scraper && cd property-scraper
python -m venv .venv
source .venv/bin/activate        # Windows: .venv\Scripts\activate
pip install requests beautifulsoup4 lxml pandas

Start from a sample listings page

Save the following sample page as sample_listings.html. It has four fictional listings. Two of them also appear in a JSON-LD block, which is how many real sites expose structured data. One is a rental, and one is a studio, so the parser has to handle both.

<!DOCTYPE html>
<html lang="en">
<head>
  <meta charset="utf-8">
  <title>Homes for sale and rent in Springfield (sample page)</title>
  <script type="application/ld+json">
  {
    "@context": "https://schema.org",
    "@type": "ItemList",
    "itemListElement": [
      {
        "@type": "RealEstateListing",
        "identifier": "SPR-1001",
        "url": "https://example.com/listings/SPR-1001",
        "datePosted": "2026-10-12",
        "offers": {"@type": "Offer", "price": 425000, "priceCurrency": "USD"},
        "about": {
          "@type": "SingleFamilyResidence",
          "address": {"@type": "PostalAddress", "streetAddress": "123 Example St",
                      "addressLocality": "Springfield", "addressRegion": "ST", "postalCode": "00001"},
          "numberOfBedrooms": 3,
          "numberOfBathroomsTotal": 2,
          "floorSize": {"@type": "QuantitativeValue", "value": 1850, "unitCode": "FTK"}
        }
      },
      {
        "@type": "RealEstateListing",
        "identifier": "SPR-1002",
        "url": "https://example.com/listings/SPR-1002",
        "datePosted": "2026-10-20",
        "offers": {"@type": "Offer", "price": 1250000, "priceCurrency": "USD"},
        "about": {
          "@type": "SingleFamilyResidence",
          "address": {"@type": "PostalAddress", "streetAddress": "45 Sample Ave",
                      "addressLocality": "Springfield", "addressRegion": "ST", "postalCode": "00002"},
          "numberOfBedrooms": 5,
          "numberOfBathroomsTotal": 4.5,
          "floorSize": {"@type": "QuantitativeValue", "value": 4100, "unitCode": "FTK"}
        }
      }
    ]
  }
  </script>
</head>
<body>
  <ul class="results">
    <li class="listing-card" data-listing-id="SPR-1001" data-status="for_sale">
      <a class="listing-link" href="https://example.com/listings/SPR-1001">123 Example St, Springfield, ST 00001</a>
      <span class="price">$425,000</span>
      <span class="beds">3 bd</span> <span class="baths">2 ba</span> <span class="area">1,850 sqft</span>
    </li>
    <li class="listing-card" data-listing-id="SPR-1002" data-status="for_sale">
      <a class="listing-link" href="https://example.com/listings/SPR-1002">45 Sample Ave, Springfield, ST 00002</a>
      <span class="price">$1,250,000</span>
      <span class="beds">5 bd</span> <span class="baths">4.5 ba</span> <span class="area">4,100 sqft</span>
    </li>
    <li class="listing-card" data-listing-id="SPR-1003" data-status="for_rent">
      <a class="listing-link" href="https://example.com/listings/SPR-1003">7 Placeholder Ln, Unit 2B, Springfield, ST 00001</a>
      <span class="price">$2,400/mo</span>
      <span class="beds">2 bd</span> <span class="baths">1 ba</span> <span class="area">950 sqft</span>
    </li>
    <li class="listing-card" data-listing-id="SPR-1004" data-status="for_sale">
      <a class="listing-link" href="https://example.com/listings/SPR-1004">88 Demo Rd, Springfield, ST 00003</a>
      <span class="price">$389,900</span>
      <span class="beds">Studio</span> <span class="baths">1 ba</span> <span class="area">610 sqft</span>
    </li>
  </ul>
  <a class="next" href="sample_listings_2.html">Next</a>
</body>
</html>

The "Next" link points to a second sample page. Save this as sample_listings_2.html. It repeats one listing from page 1, which happens on real sites when new listings push older ones down:

<!DOCTYPE html>
<html lang="en">
<head><meta charset="utf-8"><title>Homes in Springfield, page 2 (sample page)</title></head>
<body>
  <ul class="results">
    <li class="listing-card" data-listing-id="SPR-1004" data-status="for_sale">
      <a class="listing-link" href="https://example.com/listings/SPR-1004">88 Demo Rd, Springfield, ST 00003</a>
      <span class="price">$389,900</span>
      <span class="beds">Studio</span> <span class="baths">1 ba</span> <span class="area">610 sqft</span>
    </li>
    <li class="listing-card" data-listing-id="SPR-1005" data-status="for_sale">
      <a class="listing-link" href="https://example.com/listings/SPR-1005">19 Fixture Ct, Springfield, ST 00002</a>
      <span class="price">$615,000</span>
      <span class="beds">4 bd</span> <span class="baths">2.5 ba</span> <span class="area">2,300 sqft</span>
    </li>
  </ul>
</body>
</html>

Serve the folder locally, so your scraper fetches the pages over HTTP like it would on a real site:

python -m http.server 8000

Leave that running and open a second terminal for the next steps. Put the code from this and the next five steps, in order, into one file called scraper.py. Start with the imports and a fetch function that sends an honest User-Agent and fails loudly on HTTP errors:

import json
import re
import time
from datetime import datetime, timezone
from urllib.parse import urljoin

import requests
from bs4 import BeautifulSoup

HEADERS = {"User-Agent": "property-research/1.0 (you@example.com)"}


def fetch(url: str) -> str:
    response = requests.get(url, headers=HEADERS, timeout=30)
    response.raise_for_status()
    return response.text

Extract JSON-LD first

JSON-LD sits in <script type="application/ld+json"> tags. A page can hold one object, a list of objects, or an ItemList that wraps the listings, so the helper unwraps all three shapes. Then it maps each RealEstateListing to flat fields:

def iter_jsonld(soup: BeautifulSoup):
    """Yield every JSON-LD object on the page, unwrapping lists and ItemLists."""
    for tag in soup.find_all("script", type="application/ld+json"):
        try:
            data = json.loads(tag.string or "")
        except json.JSONDecodeError:
            continue
        for item in data if isinstance(data, list) else [data]:
            if item.get("@type") == "ItemList":
                for element in item.get("itemListElement", []):
                    yield element.get("item", element)
            else:
                yield item


def listings_from_jsonld(soup: BeautifulSoup) -> dict:
    found = {}
    for item in iter_jsonld(soup):
        if item.get("@type") != "RealEstateListing":
            continue
        home = item.get("about", {})
        addr = home.get("address", {})
        offer = item.get("offers", {})
        found[item["identifier"]] = {
            "listing_id": item["identifier"],
            "url": item.get("url"),
            "address": f"{addr.get('streetAddress')}, {addr.get('addressLocality')}, "
                       f"{addr.get('addressRegion')} {addr.get('postalCode')}",
            "price": offer.get("price"),
            "currency": offer.get("priceCurrency"),
            "beds": home.get("numberOfBedrooms"),
            "baths": home.get("numberOfBathroomsTotal"),
            "sqft": home.get("floorSize", {}).get("value"),
            "source": "json-ld",
        }
    return found

Values from JSON-LD are already numbers, which saves you most of the cleaning work.

Fall back to HTML selectors

Two of the four cards on page 1 have no JSON-LD, and none of them carry the listing status in structured data. The HTML parser reads every card using its data-* attributes and class names and keeps the raw text for each field. If you're new to selectors, start with our BeautifulSoup tutorial.

def text_of(card, selector: str) -> str | None:
    node = card.select_one(selector)
    return node.get_text(strip=True) if node else None


def listings_from_html(soup: BeautifulSoup, base_url: str) -> dict:
    found = {}
    for card in soup.select("li.listing-card"):
        link = card.select_one("a.listing-link")
        listing_id = card["data-listing-id"]
        found[listing_id] = {
            "listing_id": listing_id,
            "status": card.get("data-status"),
            "url": urljoin(base_url, link["href"]),
            "address": link.get_text(strip=True),
            "price_raw": text_of(card, ".price"),
            "beds_raw": text_of(card, ".beds"),
            "baths_raw": text_of(card, ".baths"),
            "sqft_raw": text_of(card, ".area"),
        }
    return found

On a real site, prefer data-* attributes and stable class names over long CSS paths. They survive redesigns better.

Clean and normalize fields

Now turn raw strings into numbers. parse_price strips everything except digits, so "$1,250,000" becomes 1250000 and "$2,400/mo" becomes 2400. rent_period keeps the "/mo" information in its own column. normalize merges both sources, lets JSON-LD win where it has a value, labels each price as an asking price or an asking rent, and stamps the row with a UTC timestamp:

def parse_price(text: str | None) -> int | None:
    """'$1,250,000' -> 1250000 and '$2,400/mo' -> 2400."""
    if not text:
        return None
    digits = re.sub(r"[^\d]", "", text.split("/")[0])
    return int(digits) if digits else None


def rent_period(text: str | None) -> str | None:
    if text and re.search(r"/\s*(mo|month)", text, re.I):
        return "month"
    if text and re.search(r"/\s*(wk|week)", text, re.I):
        return "week"
    return None


def parse_number(text: str | None) -> float | None:
    if not text:
        return None
    if "studio" in text.lower():
        return 0.0
    match = re.search(r"\d[\d,]*(\.\d+)?", text)
    return float(match.group().replace(",", "")) if match else None


def normalize(html_row: dict, jsonld_row: dict | None) -> dict:
    raw_price = html_row.get("price_raw")
    row = {
        "listing_id": html_row["listing_id"],
        "status": html_row.get("status"),
        "price": parse_price(raw_price),
        "currency": "USD" if raw_price and "$" in raw_price else None,
        "rent_period": rent_period(raw_price),
        "beds": parse_number(html_row.get("beds_raw")),
        "baths": parse_number(html_row.get("baths_raw")),
        "sqft": parse_number(html_row.get("sqft_raw")),
        "address": html_row.get("address"),
        "url": html_row.get("url"),
        "source": "html",
    }
    # Structured data wins wherever it has a value.
    for key, value in (jsonld_row or {}).items():
        if value is not None:
            row[key] = value
    row["price_type"] = "asking_rent" if row["status"] == "for_rent" else "asking_price"
    row["sqft"] = int(row["sqft"]) if row["sqft"] is not None else None
    row["collected_at"] = datetime.now(timezone.utc).isoformat(timespec="seconds")
    row["price_raw"] = raw_price
    return row


def parse_page(html: str, base_url: str) -> list[dict]:
    soup = BeautifulSoup(html, "lxml")
    structured = listings_from_jsonld(soup)
    cards = listings_from_html(soup, base_url)
    return [normalize(card, structured.get(lid)) for lid, card in cards.items()]

The source column records where each row's values came from. When JSON-LD disappears from a page after a redesign, that column tells you before your numbers go wrong.

Handle pagination and duplicates

The crawler follows the "Next" link until there isn't one, waits between requests, and skips listing IDs it has already seen. It also stops on an empty page and after max_pages, so a broken link can't send it into a loop:

def crawl(start_url: str, max_pages: int = 20, delay: float = 2.0) -> list[dict]:
    rows, seen, url = [], set(), start_url
    for _ in range(max_pages):
        html = fetch(url)
        page_rows = parse_page(html, url)
        new_rows = [r for r in page_rows if r["listing_id"] not in seen]
        seen.update(r["listing_id"] for r in new_rows)
        rows.extend(new_rows)
        print(f"{url}: {len(page_rows)} cards, {len(new_rows)} new")

        next_link = BeautifulSoup(html, "lxml").select_one("a.next")
        if not page_rows or not next_link:
            break
        url = urljoin(url, next_link["href"])
        time.sleep(delay)
    return rows

On a real site, a two-second delay or longer is a sensible default. Raise it if the server slows down or returns errors.

Export to CSV

The last block runs the crawl and writes listings.csv with pandas:

if __name__ == "__main__":
    import pandas as pd

    rows = crawl("http://localhost:8000/sample_listings.html", delay=1.0)
    df = pd.DataFrame(rows)
    df.to_csv("listings.csv", index=False)
    print(df[["listing_id", "price_type", "price", "rent_period",
              "beds", "baths", "sqft", "source"]].to_string(index=False, na_rep=""))

Run python scraper.py. Output from the sample pages:

http://localhost:8000/sample_listings.html: 4 cards, 4 new
http://localhost:8000/sample_listings_2.html: 2 cards, 1 new
listing_id   price_type   price rent_period  beds  baths  sqft  source
  SPR-1001 asking_price  425000               3.0    2.0  1850 json-ld
  SPR-1002 asking_price 1250000               5.0    4.5  4100 json-ld
  SPR-1003  asking_rent    2400       month   2.0    1.0   950    html
  SPR-1004 asking_price  389900               0.0    1.0   610    html
  SPR-1005 asking_price  615000               4.0    2.5  2300    html

Five unique listings came from six cards: the repeated SPR-1004 on page 2 was skipped. The first two rows took their values from JSON-LD, the rest from HTML. The rental keeps its monthly period, and the studio has zero bedrooms instead of a missing value. The CSV also carries status, currency, address, url, collected_at, and the raw price text for every row.

Fetch JavaScript-heavy pages with a scraper API

The sample site is static. Many real listing pages load their data with JavaScript, and some show different results by visitor location. In those cases, a scraper API can fetch the page through a real browser from the country you choose and return the final HTML. Rendering and location are also the two settings that most often decide whether you see the same page a visitor sees. For more context, see how to avoid blocks and rate limits.

The request below uses WebScrapingAPI's v2 endpoint. Read the key from an environment variable and never print it. TARGET_URL is a placeholder for a page you're permitted to collect, such as your brokerage's own site or a partner's:

import os

import requests

from scraper import parse_page

TARGET_URL = "https://www.your-brokerage.example/listings?city=springfield"

response = requests.get(
    "https://api.webscrapingapi.com/v2",
    params={
        "api_key": os.environ["WSA_API_KEY"],
        "url": TARGET_URL,
        "render_js": 1,
        "country": "us",
    },
    timeout=90,
)
response.raise_for_status()
rows = parse_page(response.text, TARGET_URL)
print(f"{len(rows)} listings parsed")

Set the key in your shell first with export WSA_API_KEY=.... The response body is the rendered HTML, so parse_page from your scraper handles it unchanged. Only the selectors need to match the target site.

How do you get house prices without scraping?

Download them. Realtor.com, Zillow, and Redfin publish free housing market files with median list prices, inventory, days on market, and price cuts by metro, county, or ZIP code, updated monthly. The FHFA House Price Index tracks repeat-sale prices. They answer market-level questions without any scraping.

The main sources:

  • Realtor.com residential data library. The Realtor.com residential data library offers monthly CSV files by country, state, metro, county, and ZIP code, with current and historical versions.
  • Zillow Research. Zillow Research data includes home value and rent indexes, inventory, and sale price files, published for your own analysis.
  • Redfin Data Center. The Redfin Data Center publishes market tracker files with sale prices, inventory, and price drops.
  • FHFA. The FHFA House Price Index measures price changes from repeat sales of the same homes.

This example reads the Realtor.com metro file straight into pandas and lists the 10 metros with the highest median listing price:

import pandas as pd

CSV_URL = ("https://econdata.s3-us-west-2.amazonaws.com/"
           "Reports/Core/RDC_Inventory_Core_Metrics_Metro.csv")

metros = pd.read_csv(CSV_URL)
month = metros["month_date_yyyymm"].iloc[0]
top = (metros.dropna(subset=["median_listing_price"])
             .nlargest(10, "median_listing_price")
             [["cbsa_title", "median_listing_price",
               "active_listing_count", "median_days_on_market"]])
print(f"Data month: {month}")
print(top.to_string(index=False))

Output:

Data month: 202609
                        cbsa_title  median_listing_price  active_listing_count  median_days_on_market
                     Nantucket, MA             5873250.0                   145                   84.0
                Vineyard Haven, MA             2495000.0                   260                   99.0
                    Jackson, WY-ID             2150000.0                   418                  108.0
     Santa Maria-Santa Barbara, CA             1720750.0                   718                   58.0
                         Heber, UT             1594500.0                  1595                   90.0
                         Rifle, CO             1510750.0                   875                   93.0
                         Kapaa, HI             1507750.0                   385                  116.0
San Jose-Sunnyvale-Santa Clara, CA             1388472.0                  2112                   35.0
                       Salinas, CA             1289500.0                   551                   66.0
                          Napa, CA             1272500.0                   572                   81.0

Source: Realtor.com Residential Data Library, metro core metrics, September 2026 (month_date_yyyymm 202609).

The file also includes price_reduced_share, new_listing_count, pending_listing_count, and median_listing_price_per_square_foot, plus month-over-month and year-over-year changes for each. Print the month every time you run the script, because the file updates monthly and your report should say which month it describes. Credit the source under any chart or table you publish.

For trends over time, the same library has a _History version of each file with one row per metro per month. Swap the file name in CSV_URL, then filter by cbsa_title and plot median_listing_price against month_date_yyyymm. ZIP-level files use the same metric columns with their own geography columns, so the code barely changes.

How do you check that scraped property data is correct?

Check every run against a few rules. Each row has an address, a price, and a source URL. Prices fall in a plausible range for the market. The row count is close to the site's stated total. No listing ID appears twice. Sale, rent, and estimate values never share one price column.

A scraper that returns HTTP 200 can still return garbage. These checks catch the common failures:

Check

Rule

Fail action

Required fields

Every row has an address, a price, and a source URL

Hold the run and inspect the rows

Price sanity

Price above zero, within the market's normal range, currency set

Flag the rows; check for a missing digit or a rent in the sale column

Rent period

Every rental has a period (month or week)

Fix the parser before loading

Row count

Close to the total the site shows for the search

Look for a pagination limit or a missed page

Duplicate IDs

No listing ID appears twice in one run

Fix dedupe; check for ID changes between pages

Field drift

Share of empty values per field stays close to the last run

Compare with the previous run; a jump means a selector broke

Stale pages

Sold and off-market listings are marked, not counted as active

Update status and keep the history

Parser break

Zero rows or a sudden drop in row count

Alert, and keep yesterday's data live

A few of these checks fit in a short pandas script that runs after every crawl:

import pandas as pd

df = pd.read_csv("listings.csv")
problems = []

missing = df[df[["address", "price", "url"]].isna().any(axis=1)]
if len(missing):
    problems.append(f"{len(missing)} rows missing address, price, or URL")

sale = df[df["price_type"] == "asking_price"]
if not sale["price"].between(10_000, 50_000_000).all():
    problems.append("sale price outside the plausible range")

rent = df[df["price_type"] == "asking_rent"]
if rent["rent_period"].isna().any():
    problems.append("rental without a rent period")

if df["listing_id"].duplicated().any():
    problems.append("duplicate listing IDs")

null_share = df.isna().mean().round(2)
print(null_share[null_share > 0].to_dict())
print("OK" if not problems else problems)

Output on the sample data:

{'rent_period': 0.8}
OK

Only rent_period has empty values, and that's expected: four of the five listings are for sale. Store the null shares from each run so the field drift check has something to compare against.

Which real estate scraping tools should you use?

Choose by how much you want to run yourself. Python libraries like requests and BeautifulSoup suit static pages. Playwright handles JavaScript-heavy sites. A scraper API adds rendering, proxies, and geotargeting without infrastructure. A data API or dataset delivers structured listings with no parser. MLS feeds remain the authoritative source for licensed listing data.

Category

Examples

You maintain

Best for

Limits

HTTP + parser libraries

requests, httpx, BeautifulSoup, lxml

Everything: fetching, parsing, scheduling, proxies

Static pages, small permitted jobs

No JavaScript; you handle blocks

Browser automation

Playwright, Selenium

Browsers, parsing, servers

JavaScript-heavy pages

Slower and heavier per page

Scraper APIs

WebScrapingAPI Scraper API and similar services

Parsing and scheduling

Rendered pages from permitted sites at any volume

You still write and fix the parser

Data APIs and datasets

WebScrapingAPI Data API (Zillow, Redfin, Zoopla) and other providers

Nothing beyond your pipeline

Structured listing records without a parser team

Coverage and fields set by the provider; quote-based

No-code tools

Visual point-and-click scrapers and browser extensions

Point-and-click setups

One-off pulls by non-developers

Hard to version, test, and scale

MLS feeds and aggregators

RESO Web API through an MLS or approved vendor

Integration and display compliance

Authoritative listing and sold data

Licensing, agreements, display rules

If you need Zillow listings at scale, a maintained Zillow data feed gives you structured records from a provider that runs the collection, instead of a scraper you'd have to build and defend yourself. It doesn't change what Zillow's terms say about your own scraping. If you're weighing your own code against a service, read how to build vs buy a scraper.

Where can you find guides for specific real estate sites?

We have step-by-step guides for several property sites, each with its own legal notes:

FAQ

It depends on the site, the data, and your country. Many major portals forbid scraping in their terms, and listing photos are often copyrighted. Public, non-personal data from sites that allow automated access carries far less risk. When the terms forbid it, use open data or a licensed feed, and ask counsel.

Can I scrape Zillow?

Zillow's terms of use prohibit automated queries, including screen scraping, crawlers, and bypassing captchas. For market trends, download Zillow Research data, which Zillow publishes for your own analysis. For listing-level records, use a licensed data provider or an MLS feed. Don't build a business on data collected against the terms.

What is the best real estate scraper?

There isn't one best tool. For static pages you're allowed to collect, Python with requests and BeautifulSoup is enough. For JavaScript-heavy pages, use Playwright or a scraper API. If you'd rather not maintain parsers, a real estate data API or a licensed dataset delivers structured listings directly.

Is there a free real estate data API?

Few are free at listing level. Free options are mostly market-level: Realtor.com, Zillow, and Redfin publish downloadable housing files, and the FHFA publishes its House Price Index. Listing-level APIs and MLS feeds usually require a paid plan, a license, or a broker relationship. Check each source's terms before you reuse the data.

How often should you scrape property listings?

Match the schedule to how fast the data changes. Daily runs catch new listings, price cuts, and status changes in active markets. Weekly runs suit slower markets and research. Monthly open-data files are enough for trend analysis. Re-fetch only listings that changed to cut load on the source site.

Do you need proxies to scrape real estate sites?

Not for small, polite jobs on sites that allow collection. Large runs often need proxies, JavaScript rendering, and location-specific results, which a scraper API bundles. Proxies don't change a site's terms. If a portal forbids scraping, rotating IPs to avoid its blocks adds legal risk.

How do you collect property images at scale?

Store image URLs and metadata, not copies, unless you have rights to the photos. Listing photos usually belong to the photographer, agent, or MLS, not the portal. For licensed reuse, get images through an MLS or IDX feed or a data provider whose license covers display, and keep the attribution.

Which approach should you pick?

Start from the question you need to answer, not from the scraper:

  • Market-level numbers such as median prices, inventory, and days on market: download open data.
  • Listing-level records at scale: license an MLS feed or use a data API.
  • Your own sites, partners' sites, and permitted public sources: use a scraper API or the Python scraper from this guide.

Whichever route you take, keep the three layers apart, label every price with its type, and run the quality checks on every load.

Get property data without maintaining scrapers

Need listing records, prices, and history for your markets? Tell us the sources and fields, and we'll scope a feed. Explore real estate data

Collecting from your own or permitted sites? Start Scraper API with 5,000 free requests. No extra credits for JavaScript rendering or geotargeting, and failed requests aren't billed. See Scraper API plans

About the Author

Robert Munceanu, Full-Stack Developer @ WebScrapingAPI

Robert Munceanu

Full-Stack Developer

Robert Munceanu is a Full Stack Developer at WebScrapingAPI, contributing across the product and helping build reliable tools and features that support the platform.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.