TL;DR: A useful site scraper turns an approved set of pages into records with defined meaning, checks those records, and delivers an identifiable batch. Start with the record and collection scope, choose an execution model that reaches the data, and test navigation, missing values, and recovery before scheduling it.
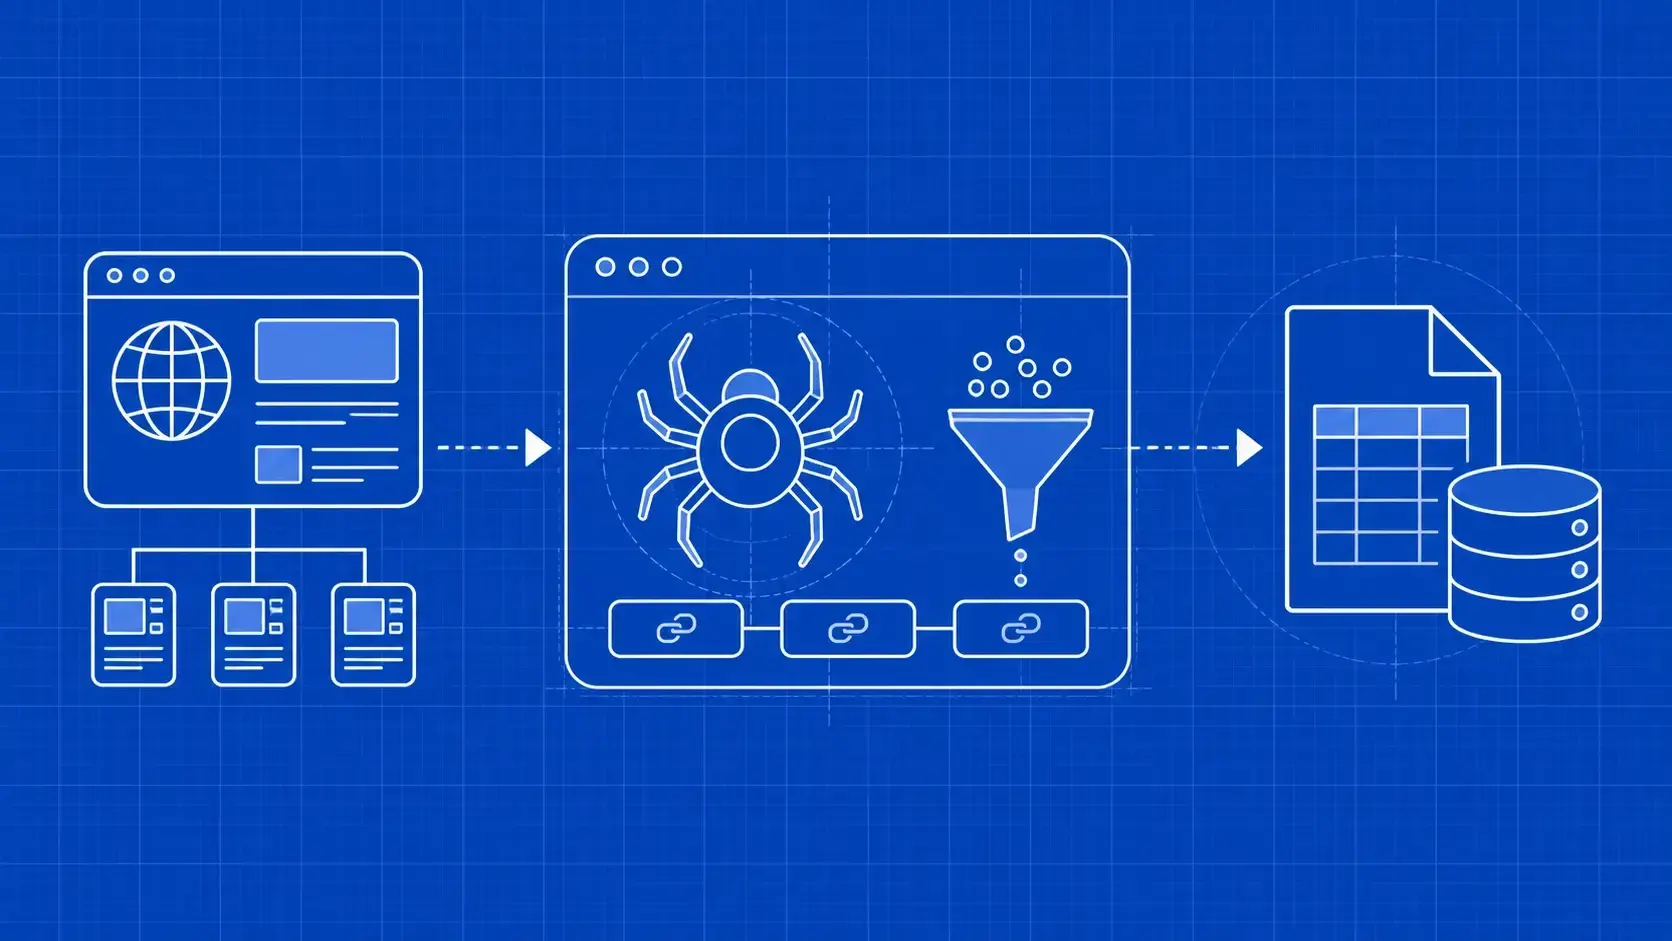
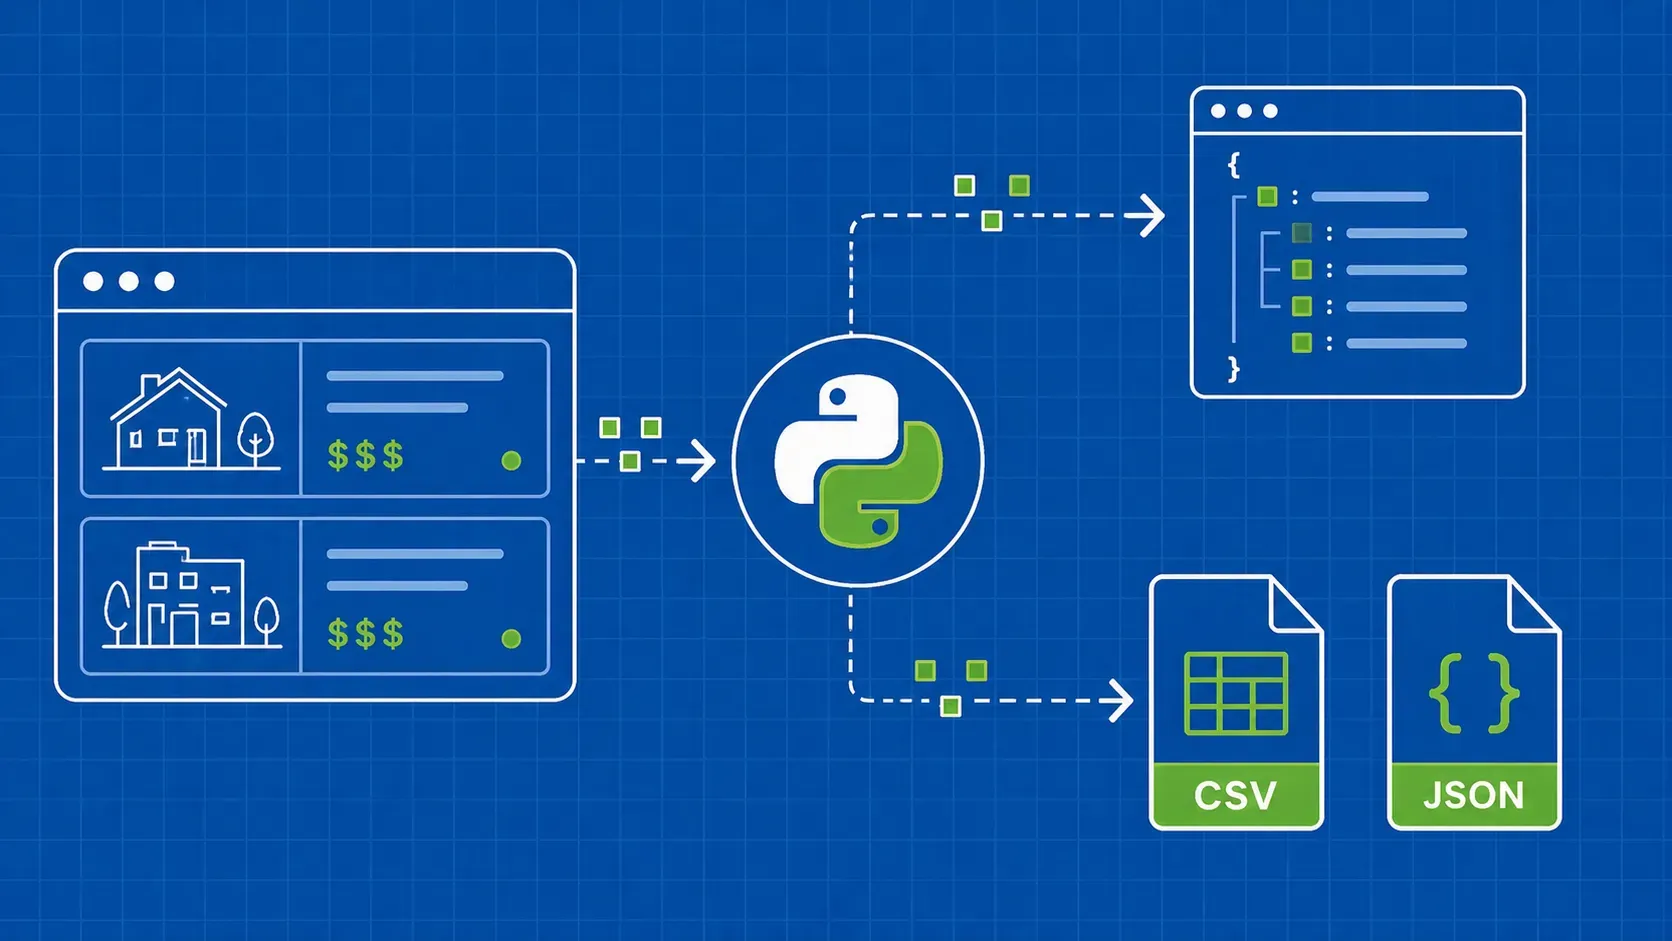
Suppose you need a weekly directory of organizations from a website you are authorized to collect. Each row should contain a name, an address, a source URL, and the time it was observed. A site scraper is the software workflow that visits the relevant pages and extracts those fields, but a dependable collector also checks whether the resulting rows are usable.
Getting text out of one page is only the first problem. You must decide which pages belong in scope, whether several listings describe the same organization, how to represent a missing address, and what the consumer should do if the next run stops halfway through. Those decisions determine whether the output can support reporting or application features.
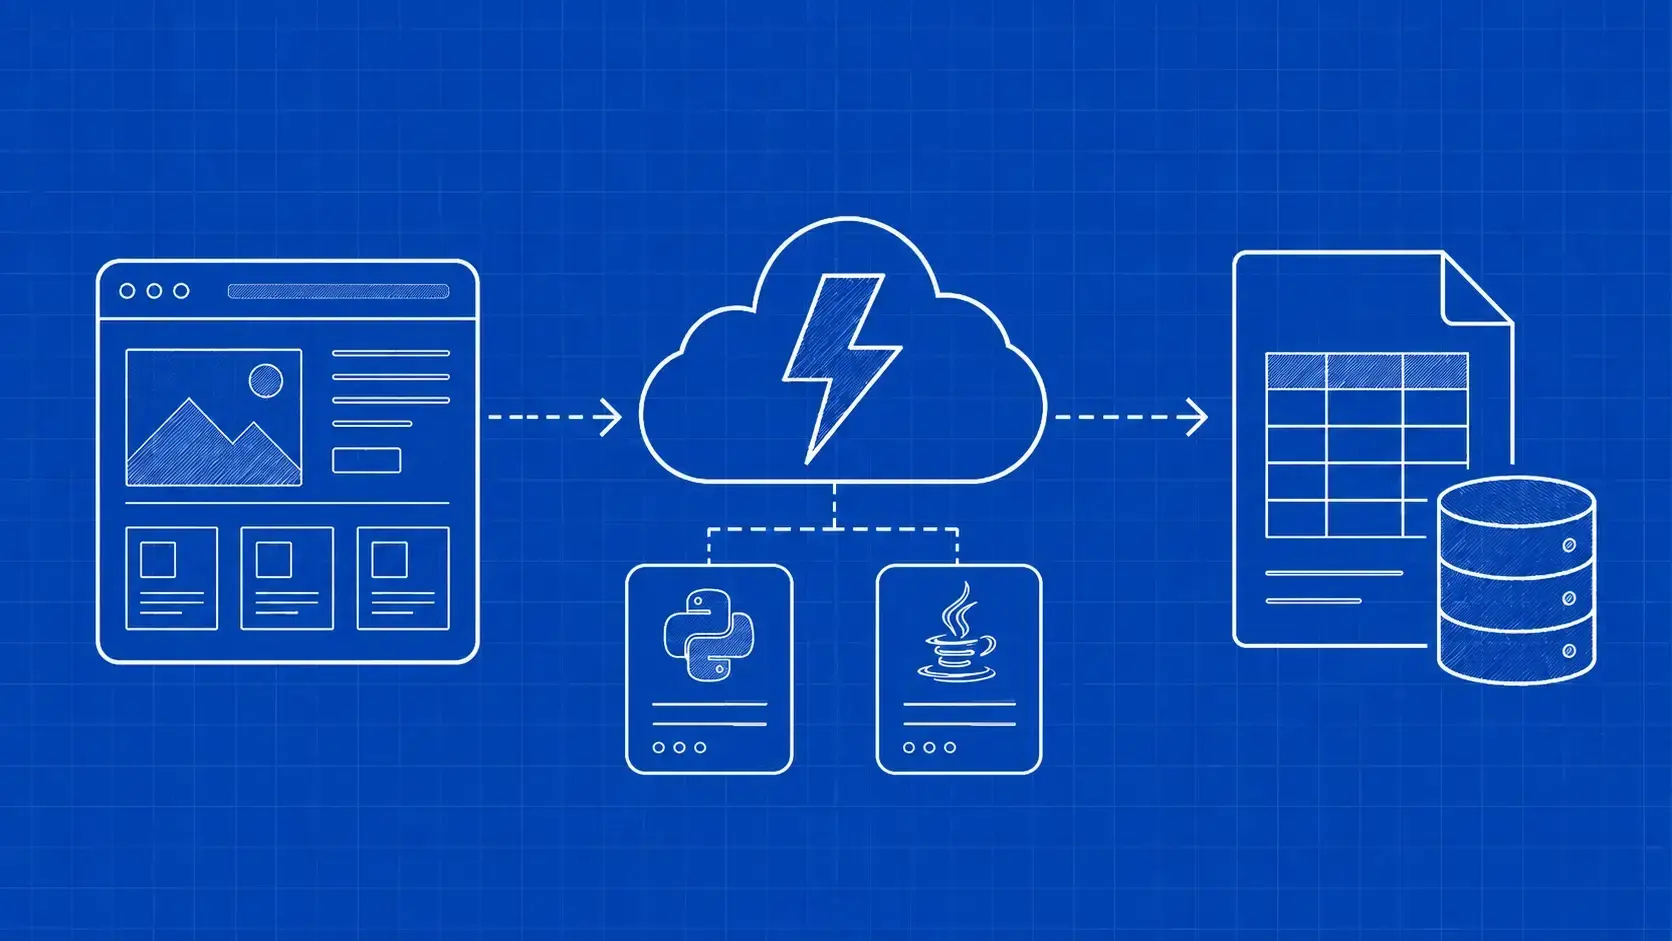
This guide follows that directory example from record design through delivery. It is a practical design and selection guide rather than a ranking of interchangeable products. You can apply the method to a visual tool, an HTTP-based collector, or browser automation, provided the chosen implementation exposes the controls and evidence your workflow needs.
Visual tools, HTTP collectors, and browser automation each have concrete products in our best web scraping tools roundup.
Begin with a small approved sample that someone can verify manually. Expand only after the collector can explain what it visited, what it accepted, and what remains uncertain.