Skip to content
Start free
Back to Blog

How to Use WebScrapingAPI: Scraper API and Web MCP Guide

Robert MunceanuLast updated on 23 min read
How to Use WebScrapingAPI: Scraper API and Web MCP Guide
TL;DR: To use WebScrapingAPI's Scraper API, send a GET request to https://api.webscrapingapi.com/v2 with your api_key and a URL-encoded url, then read the page from the response. Use it when you already know which URLs you need; pick the SERP API for search results, the Browser API for clicks and waits, and Web MCP to connect AI agents. This guide also covers rendering, errors, and costs.

You have a list of URLs, and you need the pages behind them back reliably, without running your own proxies or headless browsers. That's the job WebScrapingAPI's Scraper API does. New to the topic? Start with what web scraping is. By the end of this guide, you'll send a first request with your key in an environment variable, add rendering, location, and extraction only when a target needs them, handle every documented error, and track what each call costs. You'll also know when the Browser API, the SERP API, or Web MCP is a better fit.

Quick start

  • Endpoint: https://api.webscrapingapi.com/v2
  • Two required parameters: api_key and a URL-encoded url
  • Free trial: 5,000 requests
  • No surcharges: JavaScript rendering and geotargeting cost no extra credits
What is WebScrapingAPI's Scraper API, and when should you use it?

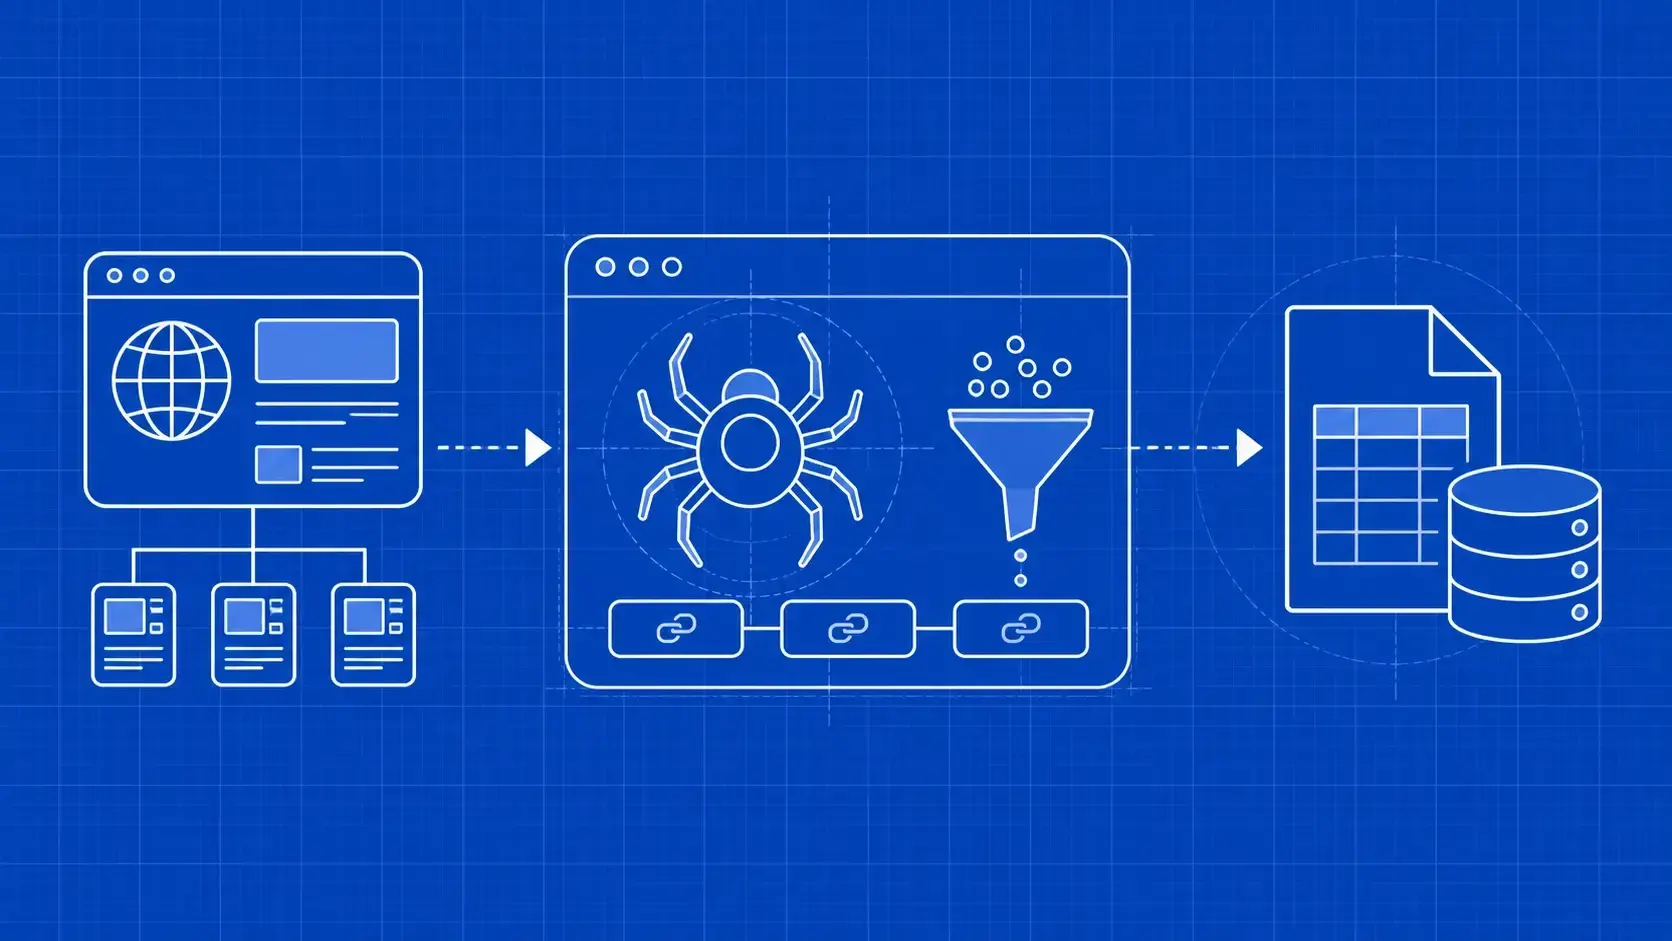
The Scraper API is a REST endpoint that takes a target URL and returns the page as HTML, JSON, or selected fields. WebScrapingAPI runs the proxies, rotation, access handling, retries, and optional JavaScript rendering. Use it when you already know which URLs you need and want page content without operating scraping infrastructure.

Your application provides the target URL and any request context, such as a country or an output format. WebScrapingAPI operates the access layer behind that request: proxy routing and rotation, access-handling strategies, internal retries against the target, and a browser when you ask for rendering. What comes back is the page body, a JSON envelope with metadata, a JSON DOM, or only the fields you selected. When a request can't be completed, you get an explicit, documented error instead of silently bad content.

Everything outside that layer stays with you: sources, purpose, parsing, validation, and storage. The API removes the proxy and browser work, not the pipeline work.

Every plan, including the trial, includes JavaScript rendering, country-level targeting in all geographies, and proxy rotation with access handling. Plans differ by request volume, concurrency, and support, not by features.

Still deciding whether a managed API is right for you? Read about the tradeoffs of using a scraping API instead of your own stack. If you need search results, clicks and waits on a page, or structured records rather than pages, skip ahead to choosing between the five Web Access APIs.

How do you send your first Scraper API request?

Create an account, copy your API key from the Web Scraping API tab in the dashboard, and store it in an environment variable. Then send a GET request to https://api.webscrapingapi.com/v2 with api_key and a URL-encoded url. Let your HTTP library encode parameters, and never call the API from browser code.

  1. Sign up. Create a WebScrapingAPI account and confirm it. The trial gives you 5,000 requests.
  2. Copy your key. In the dashboard, open the Web Scraping API tab in the left panel and copy your API key.
  3. Store it as a secret. Put the key in an environment variable on the server that will make the calls, as shown below.
  4. Send the request. Use one of the examples below.
export WSA_API_KEY=...   # paste your key here, never into code

Keys belong in server-side secrets, never in browser code, mobile apps, public repositories, logs, screenshots, or shared notebooks. Anyone with the key can spend your plan's requests.

curl

curl --get "https://api.webscrapingapi.com/v2" \
  --data-urlencode "api_key=$WSA_API_KEY" \
  --data-urlencode "url=https://example.com" \
  --data-urlencode "render_js=1" \
  --data-urlencode "country=us"

--get with --data-urlencode tells curl to put each parameter in the query string and percent-encode it for you.

Python (Python 3 with pip install requests)

This small client is the one the rest of the guide builds on. It reads the key from WSA_API_KEY, lets Requests encode the query string through params= (see the Requests quickstart), and retries only the errors worth retrying.

"""Minimal Scraper API client: env-var key, safe retries, optional JSON envelope.

Usage:
  export WSA_API_KEY=...            # never hardcode the key
  python wsa_scrape.py https://example.com
  python wsa_scrape.py https://example.com --render --country us --json
  python wsa_scrape.py https://example.com --dry-run   # print the request, no call
"""
import argparse
import json
import os
import sys
import time

import requests

ENDPOINT = "https://api.webscrapingapi.com/v2"
RETRYABLE = {429, 500, 503}          # back off and retry
FINAL = {400, 401, 403, 406}         # fix the request or the account; do not retry


def build_params(url, render=False, country=None, json_response=False, extract_rules=None):
    params = {"url": url}
    if render:
        params["render_js"] = "1"
    if country:
        params["country"] = country.lower()
    if json_response:
        params["json_response"] = "1"
    if extract_rules:
        # The API expects a JSON-stringified object; requests URL-encodes it.
        params["extract_rules"] = json.dumps(extract_rules, separators=(",", ":"))
    return params


def scrape(url, api_key, max_attempts=4, **opts):
    params = {"api_key": api_key, **build_params(url, **opts)}
    for attempt in range(1, max_attempts + 1):
        resp = requests.get(ENDPOINT, params=params, timeout=130)
        usage = {k: v for k, v in resp.headers.items() if k.lower().startswith("wsa-")}
        if resp.ok:
            return resp, usage
        if resp.status_code in FINAL:
            raise SystemExit(f"{resp.status_code}: {resp.text[:300]}")
        if resp.status_code == 422 and not opts.get("render"):
            # Scrape accepted but not completed (e.g. a challenge page). One rendered retry.
            opts["render"] = True
            params = {"api_key": api_key, **build_params(url, **opts)}
            continue
        if resp.status_code in RETRYABLE or resp.status_code == 422:
            time.sleep(min(2 ** attempt, 30))
            continue
        raise SystemExit(f"Unexpected {resp.status_code}: {resp.text[:300]}")
    raise SystemExit(f"Gave up after {max_attempts} attempts")


def main():
    ap = argparse.ArgumentParser()
    ap.add_argument("url")
    ap.add_argument("--render", action="store_true")
    ap.add_argument("--country")
    ap.add_argument("--json", dest="json_response", action="store_true")
    ap.add_argument("--dry-run", action="store_true")
    a = ap.parse_args()
    opts = dict(render=a.render, country=a.country, json_response=a.json_response)

    if a.dry_run:
        prepared = requests.Request("GET", ENDPOINT,
                                    params={"api_key": "REDACTED", **build_params(a.url, **opts)}).prepare()
        print(prepared.url)
        return

    api_key = os.environ.get("WSA_API_KEY")
    if not api_key:
        sys.exit("Set WSA_API_KEY first (dashboard -> Web Scraping API tab).")

    resp, usage = scrape(a.url, api_key, **opts)
    print("status:", resp.status_code)
    print("usage headers:", usage)
    if a.json_response:
        env = resp.json()
        print("initial-status-code:", env.get("initial-status-code"), "cost:", env.get("cost"), "type:", env.get("type"))
        print(env.get("body", "")[:300])
    else:
        print(resp.text[:300])


if __name__ == "__main__":
    main()

The --dry-run flag prints the exact request without sending it, with the key redacted. Here it is with an awkward target that contains a space, a ?, and an &:

python wsa_scrape.py 'https://example.com/a b?x=1&y=2' --render --country US --json --dry-run
https://api.webscrapingapi.com/v2?api_key=REDACTED&url=https%3A%2F%2Fexample.com%2Fa+b%3Fx%3D1%26y%3D2&render_js=1&country=us&json_response=1

Node.js (Node 18 or later, built-in fetch and URLSearchParams)

// Build a Scraper API request URL in Node 18+ without sending it.
// URLSearchParams handles encoding of the target URL and the extract_rules JSON.
const ENDPOINT = "https://api.webscrapingapi.com/v2";

export function buildScrapeUrl(apiKey, target, opts = {}) {
  const params = new URLSearchParams({ api_key: apiKey, url: target });
  if (opts.renderJs) params.set("render_js", "1");
  if (opts.country) params.set("country", opts.country);
  if (opts.extractRules) params.set("extract_rules", JSON.stringify(opts.extractRules));
  return `${ENDPOINT}?${params}`;
}

const target = "https://example.com/search?q=web scraping&page=2";
const url = buildScrapeUrl("REDACTED", target, {
  renderJs: true,
  country: "us",
  extractRules: { title: { selector: "h1", output: "text" } },
});
console.log(url);

// Round-trip check: the API sees exactly the original target and rules.
const parsed = new URL(url).searchParams;
console.log("url param decodes to original:", parsed.get("url") === target);
console.log("extract_rules parses:", JSON.parse(parsed.get("extract_rules")).title.selector);

// Live call (server-side only): uncomment with WSA_API_KEY set.
// const res = await fetch(buildScrapeUrl(process.env.WSA_API_KEY, "https://example.com"));
// console.log(res.status, res.headers.get("wsa-call-credit-usage"), (await res.text()).slice(0, 200));

Output:

https://api.webscrapingapi.com/v2?api_key=REDACTED&url=https%3A%2F%2Fexample.com%2Fsearch%3Fq%3Dweb+scraping%26page%3D2&render_js=1&country=us&extract_rules=%7B%22title%22%3A%7B%22selector%22%3A%22h1%22%2C%22output%22%3A%22text%22%7D%7D
url param decodes to original: true
extract_rules parses: h1

Why encoding matters. The target URL travels inside another URL's query string. If you paste https://example.com/search?q=web scraping&page=2 in raw, the & ends the url parameter early, and page=2 arrives at the API as a separate parameter of its own. The scrape still "works," but against the wrong page. Percent-encoding, defined in RFC 3986, turns ? into %3F and & into %26 so the whole target survives. Let a library do it: URLSearchParams in Node, params= in Requests, or --data-urlencode in curl. The round-trip check above proves the API receives exactly the string you started with.

Prefer a client library? WebScrapingAPI maintains published SDKs for Node.js, Python, Java, PHP, and Rust, plus a Scrapy integration. For parsing and crawling beyond the API call, see these Python scraping patterns beyond the API call.

Docs: Send a Request.

Which Scraper API parameters do you actually need?

Only api_key and url are required. Add render_js for client-rendered pages, country, city, state, or asn for location, extract_rules or json_response for structured output, async for slow pages, and method with body for POST, PUT, or PATCH. timeout defaults to and caps at 120,000 milliseconds.

Table 1: Scraper API parameters

Parameter

Type

What it does

Use it when

api_key (required)

string

Authenticates the request

Always; read it from an environment variable

url (required)

string

Target page; URL-encode it

Always (except when using snapshot_id)

render_js

boolean

Renders the page in a browser

Data is missing from the plain HTML

country

string

Two-letter proxy country

Content varies by country

city / state

string

Narrower location; state for us/au cities

City-level content; needs country

asn

string

Network (Autonomous System Number)

Network-specific content

extract_rules

JSON string

Returns selected fields as JSON

You need fields, not pages

json_response

boolean

Wraps output with headers, status, cost, metadata

Pipelines that store metadata

json_dom

boolean

Returns a DOM-like JSON tree

Rarely; prefer extraction rules

method / body

string

GET, POST, PUT, PATCH and payload (beta)

The target expects a form or JSON post

timeout

int (ms)

Aborts after N ms; default and max 120000

You'd rather fail fast

async

boolean

Queues the scrape and returns a response_id

Slow targets, big batches

snapshot_id

string

Fetches a queued result (instead of url)

Second step of an async job

Boolean parameters accept 1 or true to switch a feature on and 0 or false to switch it off, so render_js=1 and render_js=true mean the same thing. snapshot_id replaces url rather than joining it: you send it only when collecting the result of an async job.

POST, PUT, and PATCH go to the same /v2 endpoint with a body payload, and the docs mark them as beta. Test them against a harmless echo target such as https://httpbin.org/post before you point them at a real form. If you'd rather fail fast than wait up to two minutes for a slow target, set timeout to a lower number of milliseconds.

Start every new target with the two required parameters, look at what comes back, and add options one at a time. Each option should earn its place by fixing something you saw in the plain response.

Docs: API Parameters.

When should you turn on JavaScript rendering?

Turn on render_js=1 only when the data you need is missing from the plain HTML because the page builds it with JavaScript. Fetch without rendering first and check for your target fields. Rendering costs no extra credits on the Scraper API, but it's slower than a plain HTTP fetch, so use it per target.

The test takes one request. Pick a value you can see in a normal browser, such as a price, fetch the page without rendering, and search the response body for it. If it's there, skip rendering. If it's missing, the page builds it with JavaScript after load, so retry with render_js=1.

Decide per target, not per project, and store the setting next to each target in your configuration. A site's listing pages might ship complete HTML while its product pages load prices from a script.

Rendering also interacts with errors. The docs list a challenge page returned after render_js was disabled as one cause of a 422 response. That's why the retry policy in this guide makes exactly one rendered retry after a 422 before it gives up. You can also combine rendering with json_dom=1 if you want the rendered page as a JSON tree.

Rendering has a ceiling, though. If the data appears only after you wait for a specific element, click a button, scroll, type into a field, or take a screenshot, you've moved past what a single Scraper API request does. That's the Browser API's job.

How do you scrape location-specific content with geotargeting?

Add a two-letter country code such as us, de, or gb. Narrow further with city (lowercase, no spaces), state for US or Australian cities, or asn to choose a network. Geotargeting costs no extra credits. Availability of city and ASN targets can vary by plan and geography, so fall back to country-level when needed.

Prices, stock, language, and search results often change with the visitor's location. The country parameter routes your request through a proxy in that country, and city, state, and asn narrow it further. city always needs country, and state is for disambiguating cities in us or au.

To confirm the route before you trust it, scrape an IP echo service. This request asks for a Berlin exit and returns the IP address the target saw:

curl --get "https://api.webscrapingapi.com/v2" \
  --data-urlencode "api_key=$WSA_API_KEY" \
  --data-urlencode "url=https://httpbin.org/ip" \
  --data-urlencode "country=de" \
  --data-urlencode "city=berlin"

Country-level targeting is listed for all geographies on every plan. Finer targeting is less certain: exact availability can depend on the current plan, geography, and route. So treat city and ASN as requests, not guarantees. If one isn't available, retry at the country level, and confirm the locations your workload needs during the trial.

Google is the one place where you shouldn't reach for country. The docs say not to combine Google's own gl parameter with the Scraper API's country on the same request. For search results, use the SERP API, which takes location and language as part of the search itself.

How do you return only the fields you need with extraction rules?

Pass extract_rules as a JSON-stringified object that maps output names to CSS or XPath selectors. Each rule can return text, HTML, an attribute, a table, or nested fields, with all for every match and clean to trim whitespace. The API then returns JSON with one property per rule instead of the full page.

The shortest form maps a name to a CSS selector and returns the text of the first match:

{"title": "h1"}

The rule-object form adds options. Use it when you need an attribute, HTML, every match, or table parsing:

{
  "title": {"selector": "h1", "output": "text"},
  "links": {"selector": "a", "output": "@href", "all": 1}
}

The options are:

  • selector: a CSS selector or an XPath expression. Selectors that start with / are treated as XPath unless you set selector_type to css or xpath.
  • output: text (the default), html, @attr for an attribute such as @href, table_json, table_array, or a nested rule object.
  • all: 1 returns every match, 0 only the first.
  • clean: 1 trims leading and trailing whitespace and line breaks from text.

Nested rules handle repeated cards, rows, or search result blocks. You select the outer element with all: 1, then define the fields to pull from inside each match. The response wraps each value in a list, so expect "title": ["..."] rather than a bare string.

Preview your selectors on a saved copy of the page before you spend credits. Save the target's HTML once, then iterate on your rules locally until they return what you expect. The script below is a local approximation for checking CSS selectors with Beautiful Soup, not the API's own engine, but it supports the rule options shown here. Install it with pip install beautifulsoup4.

The fixture (fixture.html):

<html><body>
  <h1>  Example Store  </h1>
  <div class="result"><h2>Blue Mug</h2><a href="/p/blue-mug">view</a><span class="price">$12.00</span></div>
  <div class="result"><h2>Red Mug</h2><a href="/p/red-mug">view</a><span class="price">$14.50</span></div>
  <table id="specs"><tr><th>Size</th><th>Material</th></tr><tr><td>350 ml</td><td>Ceramic</td></tr></table>
</body></html>

The preview script (preview_rules.py):

"""Preview extract_rules selectors locally on saved HTML before spending credits.

This is a local approximation for checking CSS selectors, not the API's own engine.
It supports the rule options used here: selector, output (text, html, @attr, nested), all, clean.
"""
import json
import sys
from bs4 import BeautifulSoup

RULES = {
    "title": {"selector": "h1", "output": "text", "clean": 1},
    "products": {
        "selector": ".result",
        "all": 1,
        "output": {
            "name": {"selector": "h2", "output": "text"},
            "url": {"selector": "a", "output": "@href"},
            "price": {"selector": ".price", "output": "text"},
        },
    },
}


def apply_rule(node, rule):
    if isinstance(rule, str):
        rule = {"selector": rule}
    matches = node.select(rule["selector"])
    if not rule.get("all"):
        matches = matches[:1]
    out = rule.get("output", "text")
    values = []
    for m in matches:
        if isinstance(out, dict):
            values.append({k: first(apply_rule(m, r)) for k, r in out.items()})
        elif out == "html":
            values.append(str(m))
        elif out.startswith("@"):
            values.append(m.get(out[1:]))
        else:
            text = m.get_text()
            values.append(text.strip() if rule.get("clean") else text)
    return values


def first(v):
    return v[0] if v else None


html = open(sys.argv[1] if len(sys.argv) > 1 else "fixture.html").read()
soup = BeautifulSoup(html, "html.parser")
print(json.dumps({k: apply_rule(soup, r) for k, r in RULES.items()}, indent=2))
print("extract_rules param:", json.dumps(RULES, separators=(",", ":"))[:80], "...")

Output:

{
  "title": [
    "Example Store"
  ],
  "products": [
    {
      "name": "Blue Mug",
      "url": "/p/blue-mug",
      "price": "$12.00"
    },
    {
      "name": "Red Mug",
      "url": "/p/red-mug",
      "price": "$14.50"
    }
  ]
}
extract_rules param: {"title":{"selector":"h1","output":"text","clean":1},"products":{"selector":".re ...

Once the preview looks right, pass the same RULES dictionary to build_params(..., extract_rules=RULES) in the Python client, which serializes and encodes it for you. Building the query string by hand is where most mistakes happen. If the value isn't a stringified object, the API rejects the request with a validation error:

{"status": "Failure", "status_code": 400, "error": "Key `extract_rules` must be a stringified object."}

The rules, the schema, and keeping selectors current when a site changes all stay on your side.

Docs: Extraction Rules.

What does the full JSON response include, and when should you use it?

Add json_response=1 to wrap the result in JSON with the target's headers, the initial status code, the body, a type of html, json, or b64, the credit cost, and extracted microdata and JSON-LD metadata. Use it when your pipeline stores metadata or needs the target's real status code. Otherwise parse the raw body.

By default, the Scraper API returns the page body directly, which is what most HTML parsers want. The JSON envelope is for pipelines that need to know more about each fetch: what status the target actually answered with, what it cost, and what structured data the page carried.

The envelope has six fields: headers (the target's response headers), cost (credits for the request), initial-status-code (the target's first status code), body (the page content), type (html, json, or b64), and metadata (extracted microdata and JSON-LD).

This parser checks the target's status before storing anything, decodes binary bodies, and reads the cost. The input is a sample file that mirrors the documented field set, not live output:

"""Parse a json_response=1 envelope. sample_envelope.json mirrors the documented field set;
it is a SAMPLE, not live output."""
import base64
import json
import sys
from bs4 import BeautifulSoup

env = json.load(open(sys.argv[1] if len(sys.argv) > 1 else "sample_envelope.json"))

status = env["initial-status-code"]
if status >= 400:
    raise SystemExit(f"Target answered {status}; inspect before storing")

body = env["body"]
if env.get("type") == "b64":               # binary targets arrive base64-encoded
    body = base64.b64decode(body)

print("cost (credits):", env["cost"])
print("content-type:", env["headers"].get("content-type"))
print("json-ld blocks:", len(env["metadata"]["json-ld"]))
if env.get("type") == "html":
    print("title:", BeautifulSoup(body, "html.parser").title.get_text())

Output on the sample:

cost (credits): 1
content-type: text/html; charset=UTF-8
json-ld blocks: 0
title: Example Domain

There's also json_dom=1, which returns the page as a DOM-like JSON tree. If you want specific fields, extraction rules are usually simpler than walking a whole tree.

You don't need the envelope to track cost. Every response carries custom headers with a WSA- prefix:

  • WSA-Scraped-Resolved-Url: the final URL after redirects
  • WSA-Scraped-Headers: the target's response headers
  • WSA-Client-Cookies: cookies set by JavaScript after the page loaded
  • WSA-Call-Credit-Usage: credits this request used
  • WSA-Current-Credit-Usage: total credits used after this request

Log the two credit headers with every call. The Python client above already collects all WSA- headers into its usage dictionary. Over a week of runs, those logs tell you which targets cost the most and which plan you need. For the storage and validation side of the same job, see building your first reliable data pipeline.

How do you run long or slow scrapes asynchronously?

Send the request with async=true. The API queues the scrape and immediately returns a response_id. Later, call the same /v2 endpoint with api_key and snapshot_id set to that ID to fetch the finished page. Poll with increasing delays rather than holding connections open, and store the ID with the job.

A synchronous request holds a connection open until the page comes back, for up to 120 seconds. That's fine for a handful of URLs, but awkward for slow targets, large batches, or workers that can't wait two minutes per request. Async splits the call into submit and collect:

"""Queue a long scrape with async=true, then poll by snapshot_id.

Needs WSA_API_KEY. Without it, prints the two request shapes (key redacted)."""
import os
import time
import requests

ENDPOINT = "https://api.webscrapingapi.com/v2"
key = os.environ.get("WSA_API_KEY")
target = "https://example.com/"

if not key:
    for p in ({"api_key": "REDACTED", "url": target, "async": "true"},
              {"api_key": "REDACTED", "snapshot_id": "<response_id>"}):
        print(requests.Request("GET", ENDPOINT, params=p).prepare().url)
    raise SystemExit("dry run: set WSA_API_KEY to run live")

job = requests.get(ENDPOINT, params={"api_key": key, "url": target, "async": "true"}, timeout=30).json()
snapshot_id = job["response_id"]
for delay in (2, 4, 8, 16, 30, 30):
    time.sleep(delay)
    r = requests.get(ENDPOINT, params={"api_key": key, "snapshot_id": snapshot_id}, timeout=60)
    if r.ok and r.text.lstrip().startswith("<"):
        print(r.text[:200])
        break
    print("not ready:", r.status_code, r.text[:120])

Without a key, the script prints the two request shapes it would send:

https://api.webscrapingapi.com/v2?api_key=REDACTED&url=https%3A%2F%2Fexample.com%2F&async=true
https://api.webscrapingapi.com/v2?api_key=REDACTED&snapshot_id=%3Cresponse_id%3E
dry run: set WSA_API_KEY to run live

The polling loop is deliberately defensive. It backs off between attempts and treats anything that isn't a finished HTML page as "not ready yet." In production, save the response_id with the job record as soon as you get it, so a worker restart doesn't lose finished results. Collect snapshots promptly rather than assuming they'll wait indefinitely.

How should your code handle Scraper API errors and rate limits?

Treat 400, 401, 403, and 406 as fixes to your request or account, not retries. Back off and retry 429, 500, and 503. A 422 means the API accepted the request but couldn't complete the scrape, for example a challenge page served as HTTP 200, so retry once with rendering before giving up.

Table 2: Status codes and what your code should do

Code

Meaning

Action

400

Invalid request or parameters, or the URL couldn't be scraped

Fix the request; don't retry blindly

401

Missing or invalid key, or no remaining credit quota

Check the environment variable and plan usage

403

The plan lacks the requested feature

Check plan features

406

Unsupported response format

Fix the output options

422

Accepted but not completed (for example, a challenge page served as HTTP 200)

Retry once with render_js=1, then log

429

Too many requests, or too many in parallel

Back off; cap concurrency to your plan

500 / 503

Server error or maintenance

Back off and retry

The scrape() function in the Python client implements this table. Final errors (400, 401, 403, 406) stop immediately with the response text, because sending the same request again will fail the same way. Retryable errors (429, 500, 503) wait with exponential backoff, capped at 30 seconds, for up to four attempts. A 422 on an unrendered request triggers one retry with rendering. A 422 that persists is then backed off like any other retryable error until the attempts run out.

A 401 deserves a second look, because it covers two different problems. A missing key returns this:

{"error":"Access denied. No key `api_key` provided."}

The same code also means your account has run out of credit quota, so check plan usage before you rotate keys.

For 429, the fix is usually concurrency, not speed. Plans allow from 5 to 500 concurrent requests, so size your worker pool to your plan rather than letting it grow until the API pushes back. MDN's 429 reference covers the status itself. If a target keeps failing after retries, work through these fixes for blocks before you change tools.

Docs: Responses and errors.

How much does a Scraper API request cost?

Plans are sized by monthly requests: Starter is $19 for 7,000, Basic $49 for 20,000, Standard $99 for 45,000, Advanced $149 for 100,000, Premium $249 for 180,000, and Pro $599 for 450,000. The trial includes 5,000 requests. JavaScript rendering and geotargeting cost no extra credits on any plan.
Table 3: Scraper API plans (prices as of October 2026)

Plan

Price per month

Requests

Concurrent requests

≈ per 1,000 requests

Trial

$0

5,000

5

—

Starter

$19

7,000

20

$2.71

Basic

$49

20,000

20

$2.45

Standard

$99

45,000

50

$2.20

Advanced

$149

100,000

100

$1.49

Premium

$249

180,000

200

$1.38

Pro

$599

450,000

500

$1.33

The effective price per 1,000 requests falls by about half from Starter to Pro, so volume matters more than features when you pick a plan. Concurrency matters too: if your pipeline needs 100 requests in flight at once, that sets a floor regardless of monthly volume.

To see what you're actually spending, use the per-call cost the API reports: the cost field in the JSON envelope or the WSA-Call-Credit-Usage header. Run your real target mix through the trial, log those values, and multiply out to a month. That tells you which plan fits better than any estimate.

Should you use Scraper API, Browser API, SERP API, Crawl API, or Data API?

Use the Scraper API when you have URLs and need the page back. Use the Browser API when the page needs waits, clicks, typing, or screenshots. Use the SERP API for search results, the Crawl API for a bounded set of related pages, and the Data API for structured records from supported sources.

WebScrapingAPI sells five Web Access APIs. They overlap less than their names suggest, because each one starts from a different input.

Table 4: Which Web Access API fits the job

API

You send

You get back

Pick it when

Pricing model

Scraper API

URL + options

Page body, JSON, or fields

You know the URLs

Monthly request plans

Browser API

URL + waits and actions

Rendered HTML, JSON, fields, screenshot

The page needs interaction or a specific state

Quote

SERP API

Query + engine and market context

Structured search results

You start from a search

Monthly plans (Google from $28)

Crawl API

Source scope

A bounded page collection

One answer spans related pages

Quote

Data API

Target request for a supported source

Structured records

One of 116 supported sources fits

Amazon plans from $59; other sources by quote

Walk through these questions in order and stop at the first yes:

  1. Are you starting from a search query? Use the SERP API. It returns structured results by engine, location, and language, so you don't parse result pages yourself.
  2. Is your source one of the Data API's supported sources, and do you want records rather than pages? Use the Data API. It covers 116 supported public sources, and WebScrapingAPI maintains the parsers.
  3. Do you need a defined set of related pages rather than one URL at a time? Use the Crawl API for bounded multi-page collection.
  4. Does the page need waits, clicks, typing, navigation steps, or a screenshot? Use the Browser API, which runs a hosted browser behind a REST request.
  5. Otherwise, use the Scraper API, with render_js=1 only if the plain HTML is missing your data.

The APIs also combine well. A common workflow uses the SERP API to discover result URLs, has your application pick the relevant ones, and then fetches those pages with the Scraper API or the Browser API. Browser API and Crawl API pricing is by quote. The Scraper API, SERP API, and Data API's Amazon source have published monthly plans, as of October 2026.

For the full side-by-side, including what each API operates and what stays in your application, compare all five Web Access APIs.

How does Web MCP connect AI agents to the Scraper API?

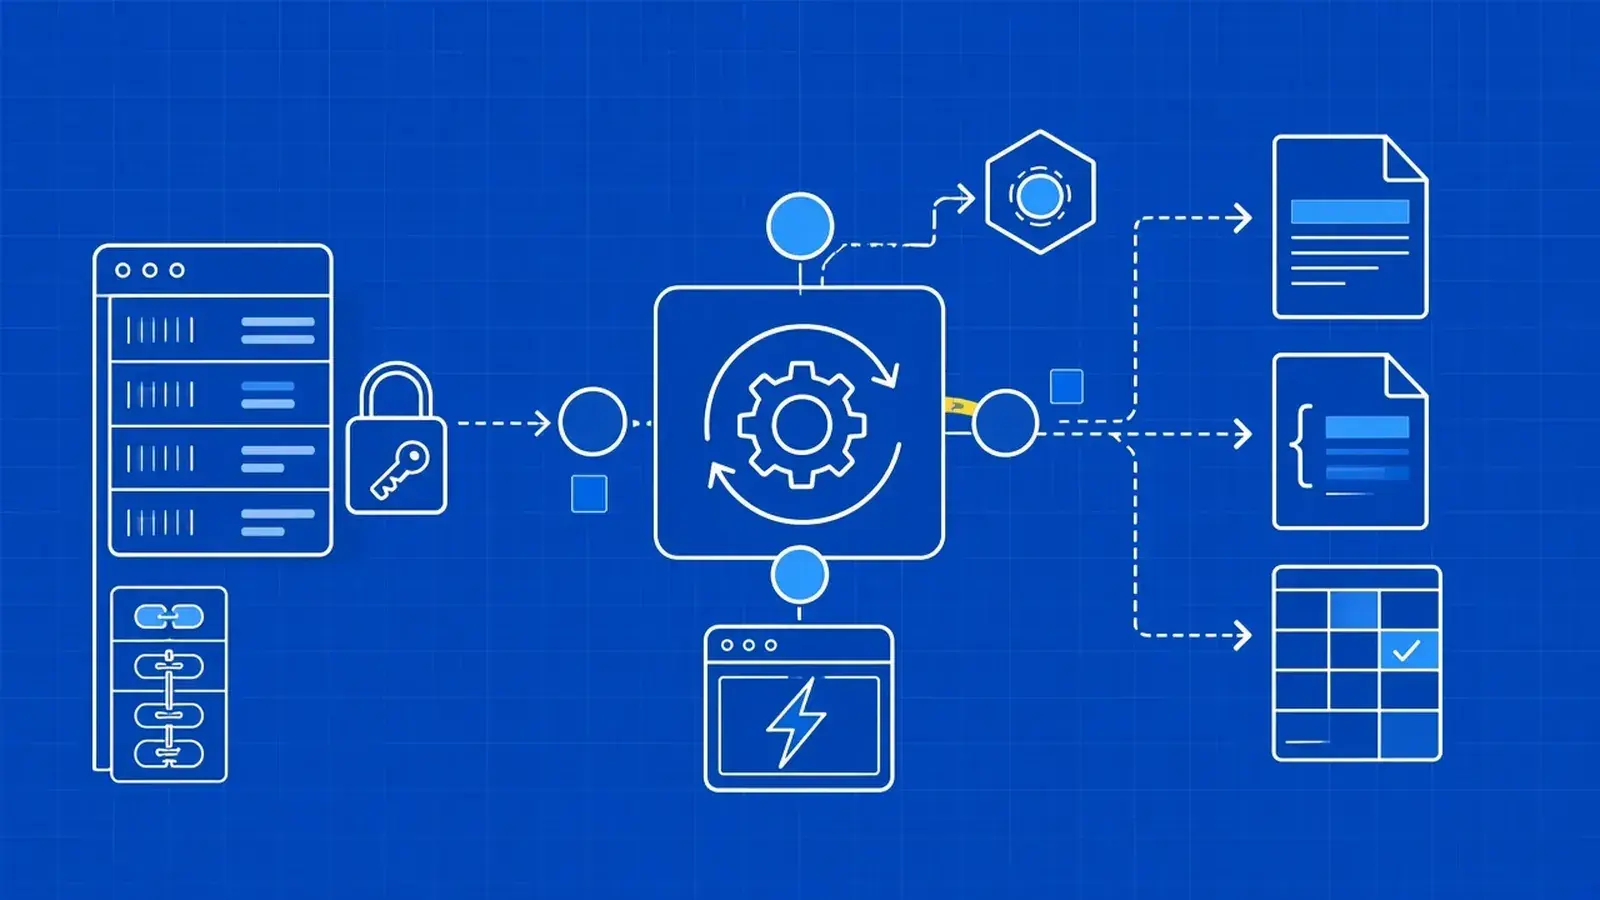
Web MCP is a hosted Model Context Protocol server at https://mcp.webscrapingapi.com/mcp. Your agent connects with a dedicated MCP token and gets web_read and web_read_more through the Scraper API or Browser API, plus web_search through the SERP API. It uses your existing plans and allowances, and a token adds no quota.

Web MCP isn't a separate product to buy. It's a connection layer over the API access your account already has, with no package to install and no server to run.

What you need. You need a WebScrapingAPI account with SERP API, Web Scraping API, or Browser API access. You also need an MCP client that supports the Streamable HTTP transport with a custom Authorization: Bearer header, the token scheme defined in RFC 6750. Clients that only support OAuth sign-in can't connect.

Setup. As the account owner, open MCP in the dashboard, copy the server URL, and select Create token. The token is shown only once, so save it in your client's secret store or a password manager straight away. Each account can have up to ten active tokens, and a lost token should be revoked and replaced. Your product API key isn't an MCP token and doesn't belong in the connection settings. Clients that accept an mcpServers object take a configuration like this:

{
  "mcpServers": {
    "webscrapingapi": {
      "url": "https://mcp.webscrapingapi.com/mcp",
      "headers": { "Authorization": "Bearer ${WSA_MCP_TOKEN}" }
    }
  }
}

Replace the placeholder with your MCP token from Dashboard → MCP. Some clients read it from an environment variable, while others have a token field, and the interpolation syntax differs by client. Set the client's tool timeout above 60 seconds.

Table 5: Web MCP tools

Tool

Does

Needs

Usage

web_search

Google organic results (1–10, default 5)

SERP API

SERP API allowance

web_read

One public page as Markdown

Scraper API or Browser API

Scraper API credits (default) or Browser API bandwidth

web_read_more

Next chunk of the same capture

Same as web_read

No new request, no extra charge

Your client discovers only the tools your account supports. Without SERP API access, the agent can still read URLs you give it, but it can't search.

Routing and billing. Reads use the Scraper API when your account has it, otherwise the Browser API, and an advanced caller can choose one with the backend argument. Scraper API reads use credits and are static by default. When the agent sets render_js: true, that's a new metered request. Browser API reads always render and use bandwidth. A failed request or an exhausted quota never switches to another product.

Limits. Each tool result is capped at 16 KiB, so long pages arrive in chunks you collect with web_read_more. Pages over 10 MiB of HTML return an error, and captures last up to one hour. The upstream timeout is 55 seconds. Each token allows four concurrent tool calls and four active sessions, and a session ends after 15 minutes idle, one hour, or 1,000 requests.

For the bigger picture of how agents use live web data, see these agentic web access patterns.

Docs: Web MCP getting started and Usage and errors.

What are the Scraper API's limits, and when is it the wrong tool?

The Scraper API fetches one page per request, so it won't click, type, scroll, or log in for you. Requests time out at 120 seconds, concurrency is capped by plan, and city or ASN coverage varies. It can't make a page legal to collect. Pick another API or tool when those limits bite.

  • No interaction. One request returns one page. Waits for a selector, clicks, typing, scrolling, and screenshots belong to the Browser API.
  • No search. For search engine results, use the SERP API rather than scraping result pages.
  • One URL at a time. If the job spans a defined set of related pages, the Crawl API manages that scope for you.
  • 120-second timeout. Slow targets and large batches should go through async requests.
  • Concurrency by plan. From 5 parallel requests on the trial to 500 on Pro. Size your workers to match.
  • Location coverage varies. Country-level targeting is broad, but city and ASN availability depends on plan, geography, and route.
  • Challenge pages can still fail. The API handles access for you, but some targets end in a 422. It doesn't promise CAPTCHA solving, so plan for occasional failures on the hardest targets.

There's also a responsibility line no API removes. You define which sources are eligible and what the data is for. Use the service only for public pages you're allowed to collect, review each site's terms, follow personal-data rules, and respect robots policies.

For the habits that keep a scraper healthy over months, see these lifecycle best practices with working code. Weighing options outside WebScrapingAPI? Our guide to comparing scraping APIs from other vendors covers the wider field.

Frequently asked questions

How do you use a scraper API?

Send an HTTP request to the API endpoint with your API key and the URL you want, then read the page from the response. With WebScrapingAPI, that's a GET to https://api.webscrapingapi.com/v2 with api_key and a URL-encoded url. Add rendering, location, or extraction parameters only when a target needs them.

How do you use a web scraping API with Python?

Install Requests, put your key in an environment variable, and pass api_key and url in the params argument so Requests encodes them. Check the status code, retry 429 and 5xx responses with backoff, and parse the body with your HTML parser or ask the API for JSON with extract_rules.

Is there a free trial for the WebScrapingAPI Scraper API?

Yes. The Scraper API trial includes 5,000 requests and costs nothing to start, with five concurrent requests. JavaScript rendering and country-level targeting are included, so you can test the targets that matter before choosing a paid plan. Paid plans start at $19 a month for 7,000 requests.

Does JavaScript rendering cost extra credits?

No. On the Scraper API, render_js=1 and geotargeting don't use extra credits on any plan. Rendering is slower than a plain fetch, though, so turn it on only for pages whose data is missing from the initial HTML. Check the WSA-Call-Credit-Usage header to confirm what each call used.

What is a web data extraction API?

It's a service that fetches web pages for you and returns their content or selected fields in a usable format. The provider runs proxies, retries, and browsers, and you send a URL and options. WebScrapingAPI's Scraper API returns HTML, a JSON envelope, or fields chosen with CSS or XPath extraction rules.

Can you scrape data from any website?

Technically, many public pages can be fetched, but not every page should be. Some content sits behind logins, some pages need browser interaction, and site terms or personal-data laws can restrict collection. Use the Scraper API for public pages you're allowed to collect, and the Browser API when pages need interaction.

How do you get data from a website that has no API?

Fetch its pages and extract the fields yourself, or let a scraping API do the fetching. With the Scraper API, send the page URL with extract_rules that map field names to CSS selectors, and you get JSON back. Preview selectors on a saved copy of the page first to avoid wasted requests.

Does WebScrapingAPI solve CAPTCHAs?

The Scraper API handles proxy routing, rotation, and access strategies, but it doesn't promise CAPTCHA solving. If a target returns a challenge page with HTTP 200, the API can classify the scrape as a 422 failure instead of passing you bad content. Retry once with rendering, then review the target.

What do I need to connect an AI agent with Web MCP?

You need a WebScrapingAPI account with Scraper API, Browser API, or SERP API access, a dedicated MCP token from the dashboard, and an MCP client that supports Streamable HTTP with a bearer header. Point the client at https://mcp.webscrapingapi.com/mcp. Clients that only support OAuth sign-in can't connect.

Does Web MCP use my Scraper API credits?

Yes, when it reads pages through the Scraper API. Each web_read is a normal metered request, and retrying with rendering is another request. web_read_more continues the same capture without a new charge. Searches use your SERP API allowance, and creating an MCP token adds no quota.

Start scraping with 5,000 free requests

The Scraper API handles proxies, rotation, retries, and JavaScript rendering behind one request. Rendering and geotargeting cost no extra credits, and failed requests aren't billed. Pick a plan when your trial shows what you need.

Wiring up an AI agent? Add the SERP API so Web MCP can search as well as read. Its trial includes 100 Google searches.

About the Author

Robert Munceanu, Full-Stack Developer @ WebScrapingAPI

Robert Munceanu

Full-Stack Developer

Robert Munceanu is a Full Stack Developer at WebScrapingAPI, contributing across the product and helping build reliable tools and features that support the platform.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.