Skip to content
Start free
Back to Blog

Web Scraping for SEO Audits

Gabriel CiociLast updated on 13 min read
Web Scraping for SEO Audits
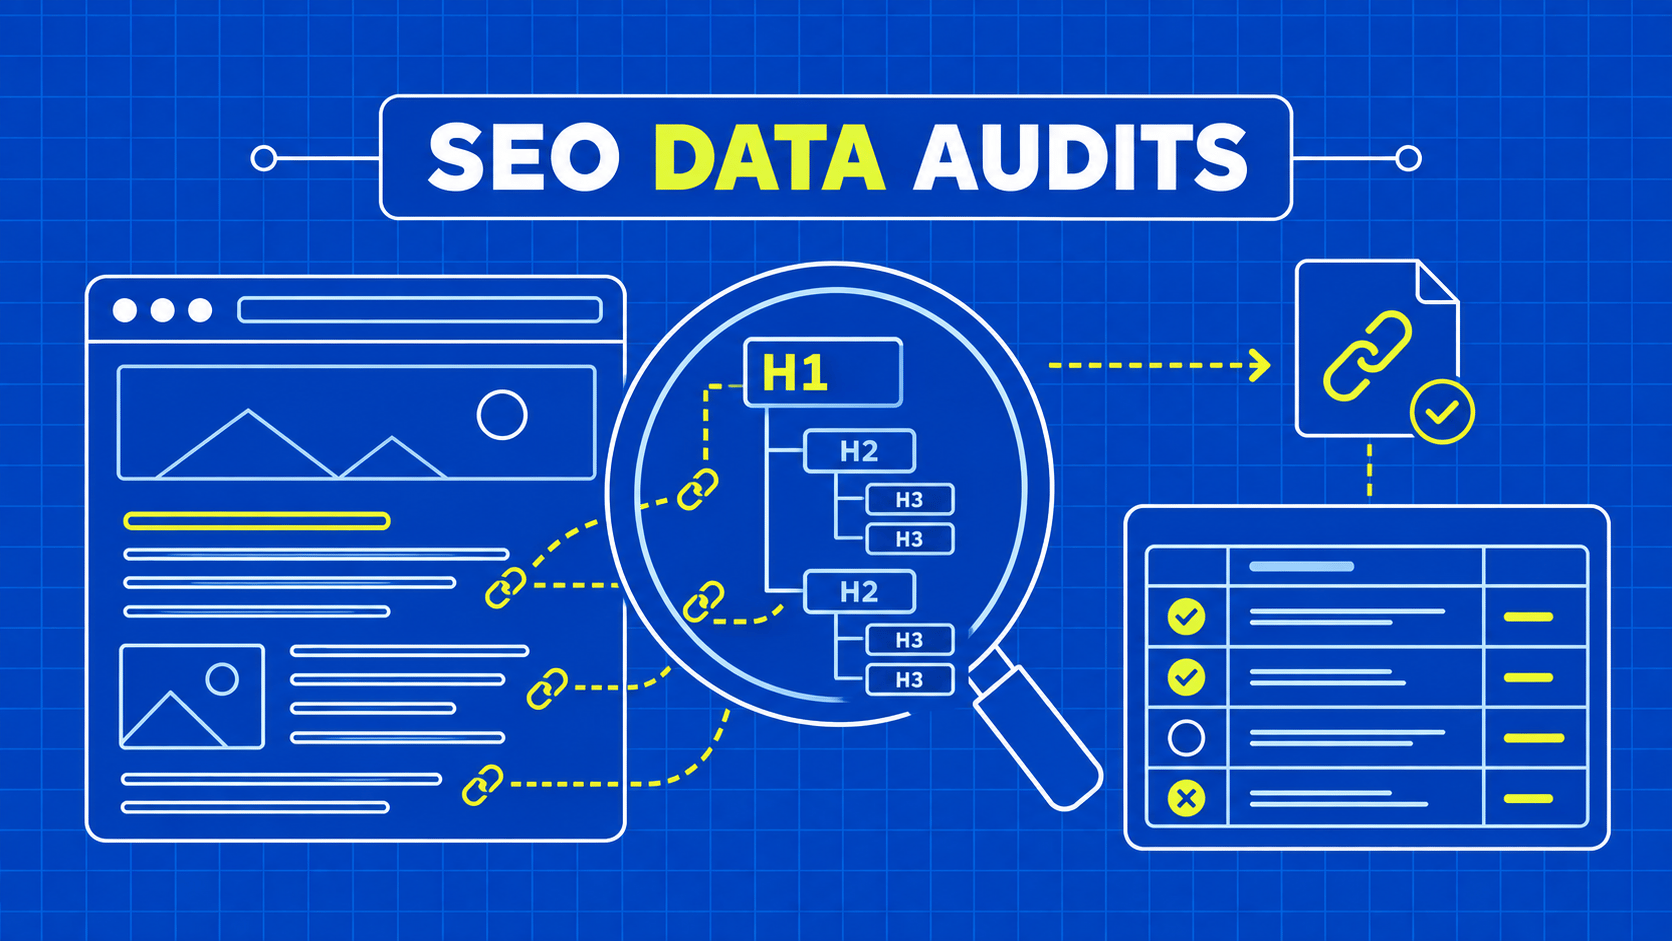
TL;DR: Web scraping for SEO turns an authorized set of pages into evidence about templates, links, and technical directives. Compare what your server sends with what your browser renders, then verify suspected problems against search-engine documentation and your site's intended behavior.

An audit reports that hundreds of pages have no description, but the browser shows a description on every page. Web scraping for SEO is the collection of webpage evidence for search-related analysis, and the first question in this situation is which representation the audit actually read. A response parser and a rendered browser can observe different documents without either tool being broken.

The useful outcome is a reproducible finding: a defined group of URLs, the evidence observed, the intended behavior, and a verified correction. A long spreadsheet of flags is not automatically a useful audit, and a technically cleaner site is not a promise of better rankings.

Lead generation, brand monitoring, and market research show the wider business use cases for web scraping that SEO audits sit inside.

This guide focuses on sites you own or are authorized to audit. It explains how to scope collection, design an evidence schema, compare response HTML with rendered output, and interpret canonical and indexing signals without turning heuristics into unsupported conclusions. It also shows how to prioritize template defects and prove that a fix changed the relevant behavior.

Desktop SEO suites can be replaced by task in our guide to Scrapebox alternatives.

Use search performance and indexing tools as separate evidence sources when available. Your crawler can observe a response and a DOM; it cannot directly observe every decision a search engine makes about indexing or ranking that page. Rank tracking by keyword, market, and device is a separate job, and SEO and SERP rank monitoring data covers it alongside your crawl.
Scope web scraping for SEO around a decision

Start with a question that can change an engineering decision. For example: do newly published product pages expose the intended title and canonical in their response HTML? Do internal navigation links reach the preferred URL directly? Did a release accidentally add an indexing directive to a public template?

An authorized audit needs a URL boundary, a request budget, and an owner for unexpected findings. Specify included hosts, path groups, environments, and query parameters. Keep production, staging, preview, and authenticated account pages separate. A broad crawl that follows every discovered link can quickly leave the intended scope.

Web scraping for SEO should also define its observation context. Language, device layout, geographic settings, and account state can alter the page. Choose the context relevant to the audit and record it. Do not combine observations from different contexts as if they were the same representation.

Use your own source systems to build the first inventory where possible. A CMS export, route manifest, or approved URL list can identify expected pages before any crawl begins. Sitemaps add another source of URLs, but they are not proof that every submitted page is crawled or indexed. Google's sitemap overview describes their role in discovery.

Set a sample strategy before collecting everything. Include one or more examples from each important template, recently changed pages, known edge cases, and pages with different publication states. A sample can reveal a shared template defect early, allowing you to refine the audit schema before generating a large dataset.

Finally, define what completion means. The run might cover all URLs in an approved inventory or a documented sample from each template. It should not claim site-wide coverage merely because its queue emptied; discovery rules may have excluded substantial parts of the site.

Build an evidence schema before a crawler

Each row should describe one observation of one URL under a stated context. Include requested URL, final URL, redirect chain, HTTP status, capture time, content type, template group, and extraction version. Then add the signals relevant to the audit, such as title, description, canonical candidates, robots directives, and internal links.

Keep observed values separate from interpreted findings. A row can record two canonical elements without immediately deciding which team should change them. Another field can hold the rule that flagged the condition, and a review field can hold the confirmed interpretation. This separation makes it possible to revise a rule without recrawling the source.

Evidence

Preserve directly

Avoid inferring automatically

HTTP response

Status, headers, redirect destinations

That a successful response is indexable

Canonical

All declared targets and their locations

That the search engine selected that target

Index directives

Raw header and meta values

That a blocked page's directive was seen

Links

Source URL, destination, anchor

That link count alone determines importance

Rendered content

Relevant extracted DOM values

That a local browser exactly matches a crawler

Web scraping for SEO becomes easier to review when evidence is small but sufficient. Preserve a bounded HTML excerpt for an unusual directive or link, rather than only a boolean flag. Include the selector or header source that produced the value. A reviewer can then confirm whether the parser matched the intended element.

Normalize URLs deliberately. Remove fragments when they do not identify distinct server resources for your audit, but do not erase meaningful query parameters without a documented rule. Keep the original observed URL alongside the normalized key. Aggressive normalization can merge distinct states and hide the very problem you are investigating.

Classify failures explicitly: fetch failure, non-HTML response, rendering timeout, unexpected login page, and extraction failure are different outcomes. None should quietly become “missing title.” If an audit substitutes empty fields for failed pages, its content report will be dominated by errors in collection rather than defects in the site.

Keep personal data out of the inventory unless it is essential and authorized. Most public technical audits do not need account details, contact form contents, or session values. Store the minimum evidence that supports the intended decision.

Compare response HTML with rendered output

Capture the response representation first, then render a selected subset whose behavior needs investigation. This creates a useful comparison: what the server sent, what changed after execution, and whether the change affects the signal under review. Do not render every page by default if the audit question can be answered from the response.

Google documents separate crawling, rendering, and indexing stages in its JavaScript SEO guidance. That distinction explains why a browser observation is useful evidence without being a complete simulation of the indexing system. Record what your tool observed and avoid claiming direct knowledge of the search engine's final interpretation.

For web scraping for SEO, use a readiness condition tied to the page. A navigation event alone may precede data loading, while a permanent network connection can outlast useful rendering. Define a reasonable timeout and capture the reason a page did not reach its expected state.

Compare named fields, not just whole-document hashes. A script may change unrelated markup on every visit, producing a different hash while the title and canonical remain stable. Conversely, one changed directive can be important even when most of the page is identical. Field-level comparisons make the report easier to act on.

For example, a template might send a generic title in response HTML and replace it with a product title after loading. Record both values and the loading outcome. That evidence supports a discussion about server rendering and resilience; it does not by itself prove the page is absent from search results.

Use our Playwright scraping guide when implementing the browser portion. Keep browser setup, rendering conditions, and extraction versions recorded so another developer can reproduce a disputed observation.

Do not confuse rendered DOM inspection with reading pixels. The distinction matters when a chart, canvas, or image contains text that a DOM parser does not expose. Our guide to screen scraping websites explains why DOM extraction and OCR require different validation. For most technical SEO fields, inspect the relevant markup or headers directly.

Reconcile canonical and indexing signals carefully

Canonical findings need more context than a target URL. Record every declaration you observe, resolve relative references where relevant, and fetch the target within the approved scope. Check whether the target redirects, returns an error, or belongs to an unexpected environment. Those are concrete observations a developer can investigate.

Google's canonicalization documentation distinguishes ways of signaling a preferred URL and explains that canonical selection is a search-engine process. Your audit should therefore say “declared canonical” when describing page markup, not “Google's canonical” unless another authorized evidence source establishes that choice.

Web scraping for SEO can identify inconsistent signals across a template. For instance, a page might declare one preferred URL while its internal links and sitemap consistently use another. Flag the inconsistency with examples and the site's intended policy. Do not assume every alternate URL is a mistake; language versions, filters, and publication workflows can have legitimate distinctions.

Indexing directives require similar precision. Capture relevant robots meta tags and HTTP header directives separately. Google's robots meta and X-Robots-Tag documentation describes those mechanisms and supported rules. Preserve raw values so a reviewer can evaluate combinations rather than relying on a parser that keeps only the first match.

Treat robots.txt as a different control. Google's robots.txt introduction explains that crawl blocking is not a dependable way to keep a URL out of search results. A blocked crawler also may not retrieve the page content containing a directive you expect it to process. Do not report “blocked” and “noindex” as interchangeable states.

An audit should compare intended policy with observed policy. Public product pages, internal search results, and staging routes may require different treatment. Ask the site owner to define those groups, then test representative URLs from each. A blanket recommendation to remove all restrictive directives can expose pages that were intentionally excluded.

Make the resulting issue concrete: the affected template, example URLs, response evidence, intended behavior, and a proposed verification check. That turns a broad warning about indexability into a scoped engineering task without claiming an indexing outcome you have not observed.

A shared template defect can affect many URLs, so group findings by likely source rather than presenting one ticket per page. Combine affected count with business importance, confidence, and repair scope. Count alone is not enough: an isolated failure on a critical landing page can deserve attention before thousands of harmless variations.

Web scraping for SEO should distinguish mechanical checks from editorial judgments. An empty title is an observation. A title being too generic for the page's purpose requires context. A repeated description across pagination may be intentional or may indicate a template limitation. Label these different confidence levels so the report does not present every heuristic as a confirmed defect.

For internal links, preserve both source and destination. A broken destination is easier to fix when the report identifies the template or content field that creates it. Group redirecting links separately from failed links, and include the final destination. This helps teams decide whether to update the source link or repair routing.

Google's crawlable links guidance describes link markup and anchor text considerations. Use it to ground specific checks, such as whether a navigational element exposes an appropriate link target. Avoid reducing a site's linking strategy to a raw count or a universal quota.

Include deliberate counterexamples in review. A duplicate title across two pages might reflect a valid content relationship; a canonical to another URL might be exactly the intended consolidation. Sampling only the flagged rows can make a flawed rule look more convincing than it is. Review passing and failing examples from the same template.

When a finding depends on a comparison with an expected inventory, document the inventory's date and owner. “Missing from crawl” can mean undiscovered, deliberately excluded, newly published, or unavailable. It is not automatically evidence that a search engine cannot find the page.

The strongest prioritization output is a short set of issues with reproducible evidence and clear ownership. Keep the complete observation dataset available for analysis, but make the engineering queue reflect causes and decisions rather than every cell that differs from a default.

Verify fixes and report the limits of the audit

Re-run the affected checks after a fix using the same observation context. Compare the relevant fields and preserve before-and-after evidence. If a template changed, include several representative pages and at least one edge case rather than checking only the URL used during development.

Web scraping for SEO is particularly useful for regression monitoring. A scheduled sample can detect a staging canonical appearing on public pages or a missing field after a release. Define who receives the finding and what evidence is needed to treat it as confirmed. Repeated alerts without ownership quickly become background noise.

Separate technical verification from search outcomes. You can verify that a response now contains the intended directive or link. You cannot promise when a search engine will revisit a URL, whether it will index it, or how its ranking will change. If the project tracks those outcomes, report them through the relevant search tools and time windows as additional evidence.

Keep run metadata with the report: inventory version, collection window, successful observations, failed observations, rendered subset, and exclusions. If only a sample was rendered, state that clearly. A reader should not need to inspect the script to discover that most pages were evaluated through response HTML alone.

Document collection limitations that can affect interpretation. Authentication, region, blocked resources, source changes during the run, and timeouts may all shape the evidence. A limitation is useful when it names the affected observations and explains what remains unverified; a generic disclaimer attached to every row adds little.

Use a completion status that reflects the scope. “Audit complete for the approved inventory, with rendering unresolved for twelve URLs” is more informative than “all checks passed” when some URLs never reached extraction. The exact counts must come from the run, not an estimate in the template.

Finally, retain the rule version and expected behavior beside the report. When site policy changes, you can distinguish a new defect from an outdated check. That makes the audit a maintainable engineering asset rather than a one-time spreadsheet.

Key Takeaways

  • Scope web scraping for SEO around an authorized inventory and a decision the team can act on. Record the observation context and completion boundary.
  • Preserve evidence before interpreting it. Fetch failures, missing fields, and restrictive directives are different states.
  • Compare response and rendered values where the audit question requires it, without claiming that a local browser reproduces search-engine indexing.
  • Group issues by template and cause, verify the intended policy, and confirm corrections with reproducible before-and-after checks.

FAQ

Does this audit replace keyword research?

No. A technical evidence audit examines what pages expose and how their signals and links behave. Keyword research addresses audience language, topics, and demand. The two can inform the same content program, but a clean crawl does not establish that the site answers the questions its audience is searching for.

Can an audit score be compared across tools?

Only when you understand the checks, weights, scope, and collection methods behind each score. Different tools may treat the same observation differently or inspect different URL sets. Compare concrete findings and evidence first. A score can summarize one tool's model, but it is not a universal measure of search quality.

Should an audit include accessibility checks?

Accessibility can be a useful adjacent workstream, but define it separately and use appropriate testing methods. A crawl can collect certain markup observations while missing keyboard behavior, focus handling, and other interactive issues. Give accessibility findings their own evidence and review criteria rather than treating a technical SEO pass as an accessibility assessment.

Conclusion

Begin with one template and a small approved URL inventory. Capture the response, render the cases that need it, and write one finding that includes evidence, intended behavior, and a verification step. That is enough to establish whether the workflow produces useful engineering decisions.

Expand only after the record schema and issue classifications are stable. A larger crawl should increase coverage, not multiply ambiguity. Keep source observations, interpretation rules, and search outcomes distinct so the report remains honest about what it proves.

If collection infrastructure becomes the part that slows your authorized audit, evaluate WebScrapingAPI's Scraper API for retrieving page HTML. Keep scope, rendering comparisons, directive interpretation, and fix verification in your audit logic. The value of the dataset comes from the decisions it supports and the evidence you can reproduce.

About the Author

Gabriel Cioci, Full-Stack Developer @ WebScrapingAPI

Gabriel Cioci

Full-Stack Developer

Gabriel Cioci is a Full Stack Developer at WebScrapingAPI, building and maintaining the websites, user panel, and the core user-facing parts of the platform.

Alternative Data Scraping for Finance: Sources & Pipelines
Use Cases

Alternative Data Scraping for Finance: Sources & Pipelines

TL;DR: Alternative data scraping uses web collection techniques to gather non-traditional datasets (product pricing, sentiment, job postings, regulatory filings) that reveal market signals before they appear in earnings reports. This guide walks you through the highest-value data sources, how to build financial-grade pipelines, data quality validation, and the compliance guardrails you need to stay on the right side of the law.

Mihnea-Octavian Manolache15 min read
Read Article
What Is Financial Data? Types, Sources, and Analysis Tools
Use Cases

What Is Financial Data? Types, Sources, and Analysis Tools

TL;DR: Financial data is the collection of quantitative records (income, expenses, assets, liabilities, cash flow) that organizations and individuals use to make informed economic decisions. This guide breaks down the four core financial statements, compares traditional and alternative data sources, walks through modern collection methods, and covers the tools professionals rely on for analysis.

Suciu Dan13 min read
Read Article
XPath vs CSS Selectors: Choosing the Right One
Use Cases

XPath vs CSS Selectors: Choosing the Right One

TL;DR: XPath and CSS selectors both locate DOM elements, but they solve different problems. CSS selectors are faster and more readable for straightforward selections. XPath wins when you need to traverse the DOM in any direction, match text content, or handle complex conditional logic. Most production projects benefit from using both strategically.

Mihai Maxim12 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.