Skip to content
Start free
Back to Blog

JavaScript With Scrapy: Data First, Render Only When Needed

Mihai MaximLast updated on 10 min read
JavaScript With Scrapy: Data First, Render Only When Needed
TL;DR: Using JavaScript with Scrapy does not always require a browser. First inspect the raw response, network requests, and embedded page state; add scrapy-playwright only when the target data truly depends on browser execution, then control waits, interactions, cleanup, and concurrency deliberately.

Using JavaScript with Scrapy means adding browser execution for pages whose required data appears only after client-side code runs. The practical goal is not to render every page, but to identify the cheapest reliable path to the data: raw HTML, a JSON request, an embedded JavaScript object, or, only when necessary, a browser-built DOM.

That distinction matters because Scrapy's downloader receives the server's response, while Chrome or Firefox may make additional requests and mutate the document afterward. A React, Vue, or Angular page can therefore look complete in DevTools even though response.text contains little more than an application shell.

This guide starts with a browser-last diagnosis, then builds a focused scrapy-playwright workflow for the requests that genuinely need execution. You will also see how to use condition-based waits, handle clicks and session state, compare rendering options, and keep dynamic spiders stable in production. The result is a workflow that preserves Scrapy's efficient HTTP pipeline wherever possible without pretending that every modern site can be scraped from static markup alone.

Static-page basics come first, and our Python web scraping guide is the place that workflow builds on.
Find the data source before rendering

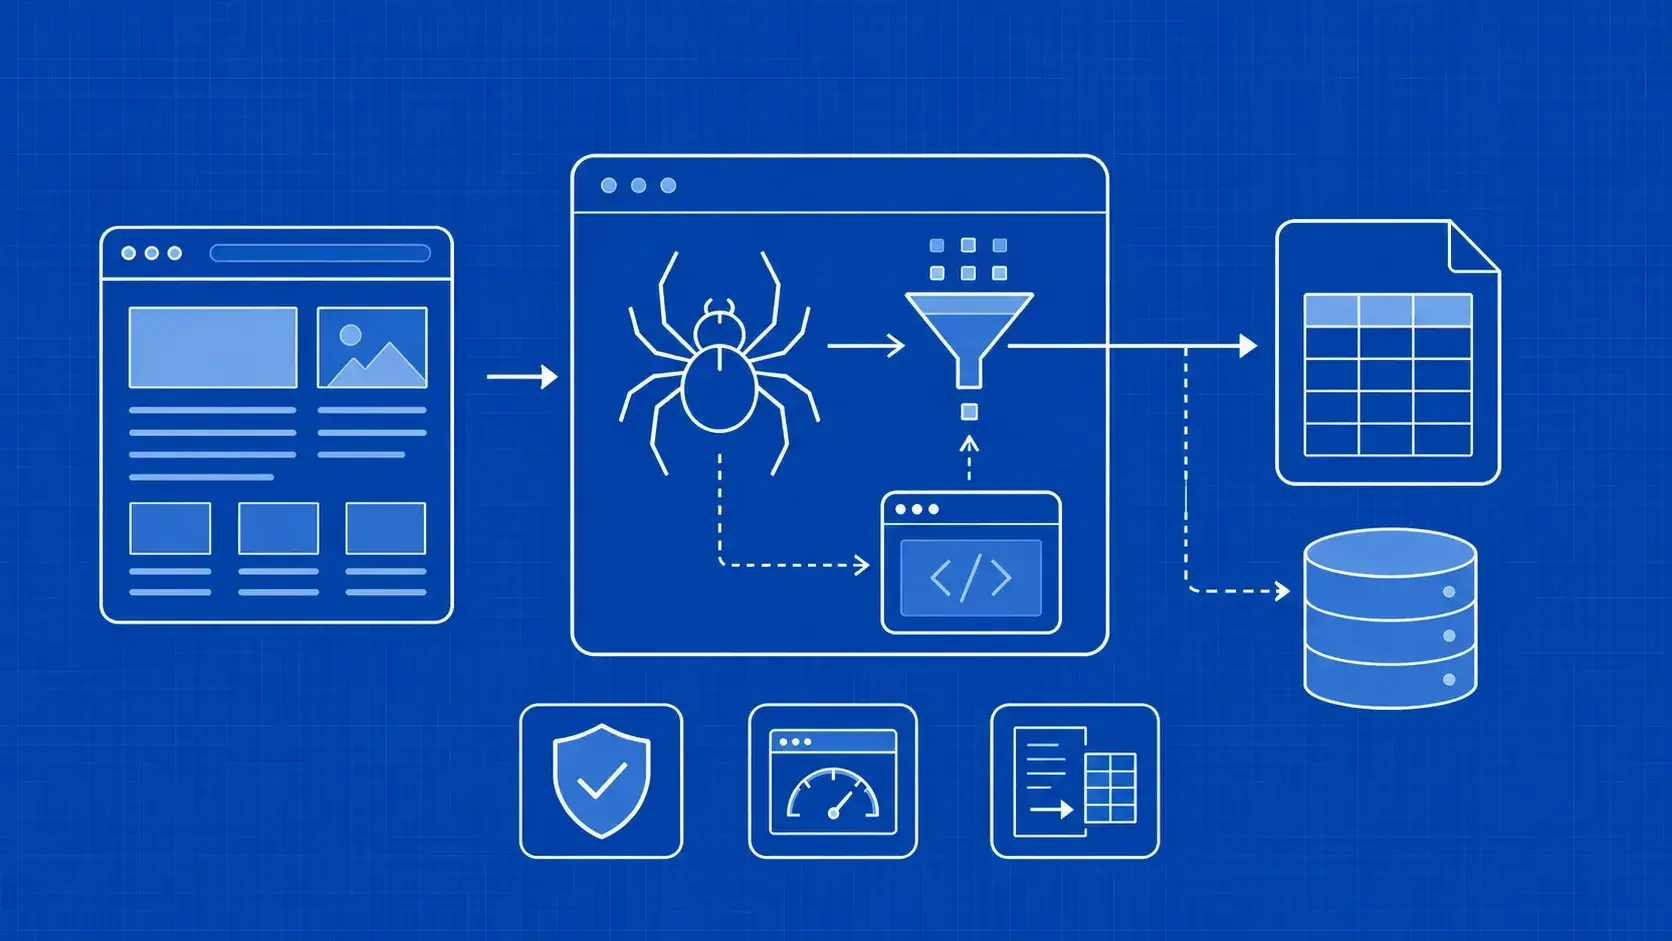
Before you try to execute JavaScript with Scrapy, inspect what the server already returned. The official Scrapy guidance on dynamic content recommends locating the underlying source first. Use this order: raw response, network request, embedded state, then a headless browser.

Compare Scrapy's response with the rendered DOM

Save or search response.text for a distinctive value you can see in the browser, such as a product ID rather than a formatted price. Then compare it with DevTools' Elements panel. If the value exists only in the rendered DOM, JavaScript probably inserted it, but that still does not prove rendering is required. The application may have fetched the same value from an accessible endpoint.

A broader web scraping with Scrapy playbook is a useful internal reference here, especially for response inspection, selectors, and request debugging.

Replay the XHR or fetch request

Open DevTools, select Network, reload the page, and filter by Fetch/XHR. Inspect candidate responses until you find the fields you need. Record the URL, HTTP method, query string or request body, relevant headers, and any cookies or tokens tied to the session.

Reproduce the smallest valid request in Scrapy instead of copying every browser header:

def parse(self, response):
    yield scrapy.Request(
        "https://example.com/api/products?page=1",
        headers={"Accept": "application/json"},
        callback=self.parse_products,
    )

def parse_products(self, response):
    payload = response.json()
    for row in payload["results"]:
        yield {"id": row["id"], "name": row["name"]}

This route avoids DOM timing, browser memory, and visual selector changes. If the endpoint uses pagination, cursor values, or POST data, follow those parameters directly. When authentication is involved, preserve the required cookies or token flow rather than hard-coding a short-lived credential.

Parse JSON and data embedded in scripts

Sometimes the initial HTML already contains application state inside a <script> element. Extract that script with a CSS or XPath selector. Use json.loads() when the content is valid JSON; use chompjs when it is JavaScript object syntax with unquoted keys, trailing commas, or similar differences.

import chompjs

script = response.css("script[data-page-state]::text").get()
state = chompjs.parse_js_object(script) if script else {}
items = state.get("products", [])

Prefer a structured parser to a broad regular expression. Regex can isolate a clearly bounded assignment, but it becomes brittle around nested objects and escaped strings. Pairing direct JSON requests with script-tag parsing often solves Scrapy dynamic content without launching a browser.

Add JavaScript rendering with scrapy-playwright

When the data depends on browser-only behavior, such as application code, Web APIs, or interaction-driven state, add rendering selectively. This JavaScript with Scrapy example uses scrapy-playwright as the main integration path, while keeping ordinary requests on Scrapy's standard downloader.

Install and configure the integration

A commonly documented setup pattern installs the plugin and a Playwright browser binary in the same project environment:

python -m pip install scrapy-playwright
python -m playwright install chromium

Add the asyncio reactor and Playwright download handlers to settings.py:

TWISTED_REACTOR = "twisted.internet.asyncioreactor.AsyncioSelectorReactor"

DOWNLOAD_HANDLERS = {
    "http": "scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler",
    "https": "scrapy_playwright.handler.ScrapyPlaywrightDownloadHandler",
}

PLAYWRIGHT_BROWSER_TYPE = "chromium"

Pin compatible dependency versions in deployable projects, and test the same lock file in development and production. The supplied evidence does not validate the plugin's current configuration surface, so check the project's current documentation before treating this template as release-ready.

Render one request and parse it with Scrapy selectors

Mark only the request that needs a browser. A meaningful selector wait ensures the callback receives HTML after the target component appears:

import scrapy
from scrapy_playwright.page import PageMethod

class ProductsSpider(scrapy.Spider):
    name = "products"

    def start_requests(self):
        yield scrapy.Request(
            "https://example.com/products",
            meta={
                "playwright": True,
                "playwright_page_methods": [
                    PageMethod(
                        "wait_for_selector",
                        "[data-product-card]",
                    )
                ],
            },
        )

    def parse(self, response):
        for card in response.css("[data-product-card]"):
            yield {
                "name": card.css("[data-name]::text").get(),
                "price": card.css("[data-price]::text").get(),
            }

The callback still receives a Scrapy response, so existing CSS and XPath extraction patterns remain useful. Keep static category pages, API calls, and assets on normal requests. A dedicated Scrapy-Playwright tutorial for JavaScript-heavy sites is a natural next internal reference when you need multiple contexts, page events, or deeper project configuration.

Wait for and interact with dynamic content

A completed navigation event does not mean application data is ready. Scrapy JavaScript rendering becomes reliable only when the spider waits for a state connected to the fields it plans to extract.

Prefer state-based waits to fixed delays

Wait for a stable selector, a known API response, a URL transition, or an application flag. A selector such as [data-results-loaded="true"] expresses intent better than sleeping for three seconds. Fixed delays can be too short on a slow run and waste time on a fast one.

Use bounded timeouts and log which condition failed. If no stable signal exists, a short fixed wait can be a fallback, but place an upper bound around the entire browser request. That makes a Scrapy wait for JavaScript failure observable instead of leaving pages open indefinitely.

Click, scroll, paginate, and retain session state

Page methods can perform a controlled interaction before the response returns:

bplaywright_page_methods": [
    PageMethod("click", "button.load-more"),
    PageMethod("wait_for_selector", "[data-page='2']"),
]

For infinite scroll, repeat a scroll action only while the item count increases, and stop after a defined number of unchanged passes. For pagination, prefer the site's data request if one exists; otherwise click the next control and wait for a page marker or first-row ID to change.

Keep related authenticated requests in the same named browser context so cookies and local storage can persist. With playwright_include_page=True, close the live page in a finally block. Close a dedicated context after its last session request, not while other requests still depend on it:

async def parse_last_session_page(self, response):
    page = response.meta["playwright_page"]
    context = page.context
    try:
        return {"title": await page.title()}
    finally:
        await page.close()
        await context.close()

Because inclusion and cleanup APIs can change, confirm the current request metadata and lifecycle rules before deploying. Leaked pages eventually consume the browser's page limit and make an otherwise correct JavaScript with Scrapy spider appear to hang.

Compare Scrapy JavaScript options

The best integration depends on whether you need a real browser, how much interaction the flow requires, and who will operate the rendering infrastructure. Do not choose solely by how short the first demo looks.

Playwright, Selenium, Splash, and hosted rendering APIs

Option

Best fit

Main tradeoffs

scrapy-playwright

Selective browser rendering inside a Scrapy project, including modern interactions

Browser CPU and memory cost, asynchronous lifecycle management, and version-sensitive integration details

Selenium-based integration

Teams with established WebDriver automation or test code

Driver and browser management, more glue around Scrapy, and compatibility that must be checked for the chosen package

Splash-based integration

An HTTP rendering service or existing Lua-based workflows

A separate service to operate, plus JavaScript behavior that may differ from a full current browser

Hosted rendering API

Offloading browser, proxy, and retry infrastructure

Vendor-specific limits, timeout semantics, concurrency, pricing, and less local control

A focused Scrapy versus Selenium comparison can help when you already maintain WebDriver code. A Scrapy Splash tutorial is more useful when your architecture favors a standalone rendering service. For JavaScript with Scrapy, use the option that satisfies the minimum required interaction while leaving straightforward requests browser-free.

Rendering is not an anti-bot guarantee. A full browser can still receive a 403 response, CAPPCHA, rate limit, or account challenge, so evaluate access controls separately from DOM execution.

Run rendered spiders reliably in production

A headless browser with Scrapy is slower and heavier than a normal HTTP request. Production reliability comes from limiting browser work, bounding failures, and measuring resources.

Control cost, concurrency, and browser resources

Render only URLs proven to require it. Cache representative pages during parser development, block unnecessary media cautiously, and set conservative limits for browser contexts and pages. Raise concurrency gradually while watching memory, CPU, timeouts, and open pages.

Use separate timeout budgets for navigation and post-load waits. Retry transient network or browser-process failures, but cap attempts and avoid retrying deterministic failures such as a removed selector forever. Close pages on success and exceptions, and recycle unhealthy browser workers. These controls keep JavaScript with Scrapy from turning one slow target into crawler-wide backpressure.

A web scraping without getting blocked guide is a useful internal follow-up for headers, request rates, proxies, and access diagnostics, which are separate from rendering correctness.

Troubleshoot missing, slow, or blocked content

Symptom

Check next

Field exists in the browser but not response.text

Find the Fetch/XHR request or embedded script before adding rendering

Rendered response is still missing data

Wait for a field-specific selector or network condition, then verify the selector against the final DOM

First page works, later pages are empty

Preserve cookies, tokens, context state, and pagination parameters

Spider slows down over time

Count open pages and contexts, confirm cleanup, and lower rendered concurrency

Repeated timeouts

Separate navigation from application waits, capture diagnostics, and cap retries

403 or CAPTCHA

Treat it as an access-control problem, not proof that JavaScript failed

When a selector breaks, save the rendered HTML and compare it with the browser session used for manual testing. If responses are blocked, inspect status codes and challenge pages before changing wait logic. This symptom-to-action loop keeps debugging grounded in evidence rather than adding longer sleeps to every request.

Key Takeaways

  • Look for raw HTML, JSON endpoints, and embedded application state before adding a browser.
  • Enable scrapy-playwright only on requests that require execution, then keep using Scrapy selectors on the rendered response.
  • Wait for observable page state, cap timeouts, and close every included page or dedicated context.
  • Treat rendering, scaling, and anti-bot access as separate engineering problems with different diagnostics.

FAQ

Can one Scrapy spider mix standard requests with JavaScript-rendered requests?

Yes. Keep normal scrapy.Request objects on the default downloader and add the rendering metadata only to URLs that need a browser. Both request types can feed the same item pipeline. This selective model preserves Scrapy's throughput for static pages while letting a smaller subset use browser execution.

How can I run custom JavaScript or click an element with scrapy-playwright?

Use a page-method entry for operations that can run before the callback, such as a click or an evaluate call. For conditional logic or values returned by custom JavaScript, include the live page object in response metadata and use an asynchronous callback. Always close that page in finally, including when extraction raises an exception.

How do I capture a screenshot or inspect the rendered HTML while debugging?

Include the Playwright page in the response, then call page.screenshot(path="debug.png", full_page=True) inside an asynchronous callback. Save await page.content() alongside the screenshot when selector behavior is unclear. Use unique filenames containing a request ID, and avoid leaving these diagnostics enabled at scale because screenshots add I/O and storage overhead.

Does a headless browser prevent 403 responses, CAPTCHAs, or bans?

No. A headless browser executes JavaScript, but sites can still evaluate IP reputation, request rate, cookies, account behavior, browser fingerprints, and navigation patterns. Diagnose the returned status and challenge content separately. Rendering can make the page functional without making the traffic trusted or authorized.

Can scrapy-playwright run in Docker or a CI environment?

Yes. The container must include the selected browser binary and its operating-system dependencies, and its Playwright version should match the Python package you install. Pin dependencies, test the image without a display server, provide enough shared memory, and run a small rendered smoke test before starting the full spider.

Conclusion: JavaScript with Scrapy in Practice

The reliable way to handle dynamic pages is to move from cheapest to most complex. Compare the raw Scrapy response with the rendered DOM, locate the request or embedded state that supplies the missing fields, and parse structured data directly whenever possible. Only then should you add browser execution.

When rendering is necessary, keep it selective. Wait for a state tied to the data, not an arbitrary delay; preserve session context only where the workflow requires it; and close pages and contexts predictably. In production, browser concurrency, timeout boundaries, retries, and resource metrics matter as much as selectors. A browser that renders correctly on a laptop can still become the crawler's bottleneck or encounter access controls at scale.

If blocking at the request layer becomes the constraint, rather than interaction logic, WebScrapingAPI offers a Scraper API that returns raw HTML while handling proxy rotation and CAPTCHAs behind the scenes. That can let you keep Scrapy's parsing and item pipeline while offloading the unstable retrieval layer. Start with the simplest path you can verify, instrument it, and add browser complexity only when the evidence says you need it.

About the Author

Mihai Maxim, Full Stack Developer @ WebScrapingAPI

Mihai Maxim

Full Stack Developer

Mihai Maxim is a Full Stack Developer at WebScrapingAPI, contributing across the product and helping build reliable tools and features for the platform.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.