Skip to content
Start free
Back to Blog

Best Amazon Scraping API: 5 Options and How to Choose

Robert SfichiLast updated on 13 min read
Best Amazon Scraping API: 5 Options and How to Choose
TL;DR: The best Amazon scraping API depends on the output you need. Choose a dedicated Amazon endpoint for predefined product, search, or offer fields; consider general page retrieval when you already own the parser. Compare candidates using the same products, locations, required fields, and cost per accepted record. The shortlist below is based on current documentation, with a practical trial plan to verify the fit.

Imagine two services returning the same product. One provides a page your team must parse. Another returns JSON, but its price belongs to a different variant or delivery location. Both requests can appear successful while only one, or neither, meets your requirements.

Choosing the best Amazon scraping API starts with defining the observation you want to collect. A price tracker needs consistent product and offer context. A discovery tool needs search results and page coverage. A scheduled research project needs completed batches that arrive within its collection window.

This guide compares five options by their documented capabilities and explains how to evaluate them without treating advertised request counts as finished datasets. You do not need to be a developer to use the selection process: start with a sample of products, write down the fields you need, and inspect what each service returns.

The provider descriptions are based on documentation checked in September 2026. We have not run a comparative paid-service benchmark, so the article does not award a fastest or most reliable provider. Instead, it gives you a shortlist, a cost calculation, and an acceptance checklist you can apply to your own workload.
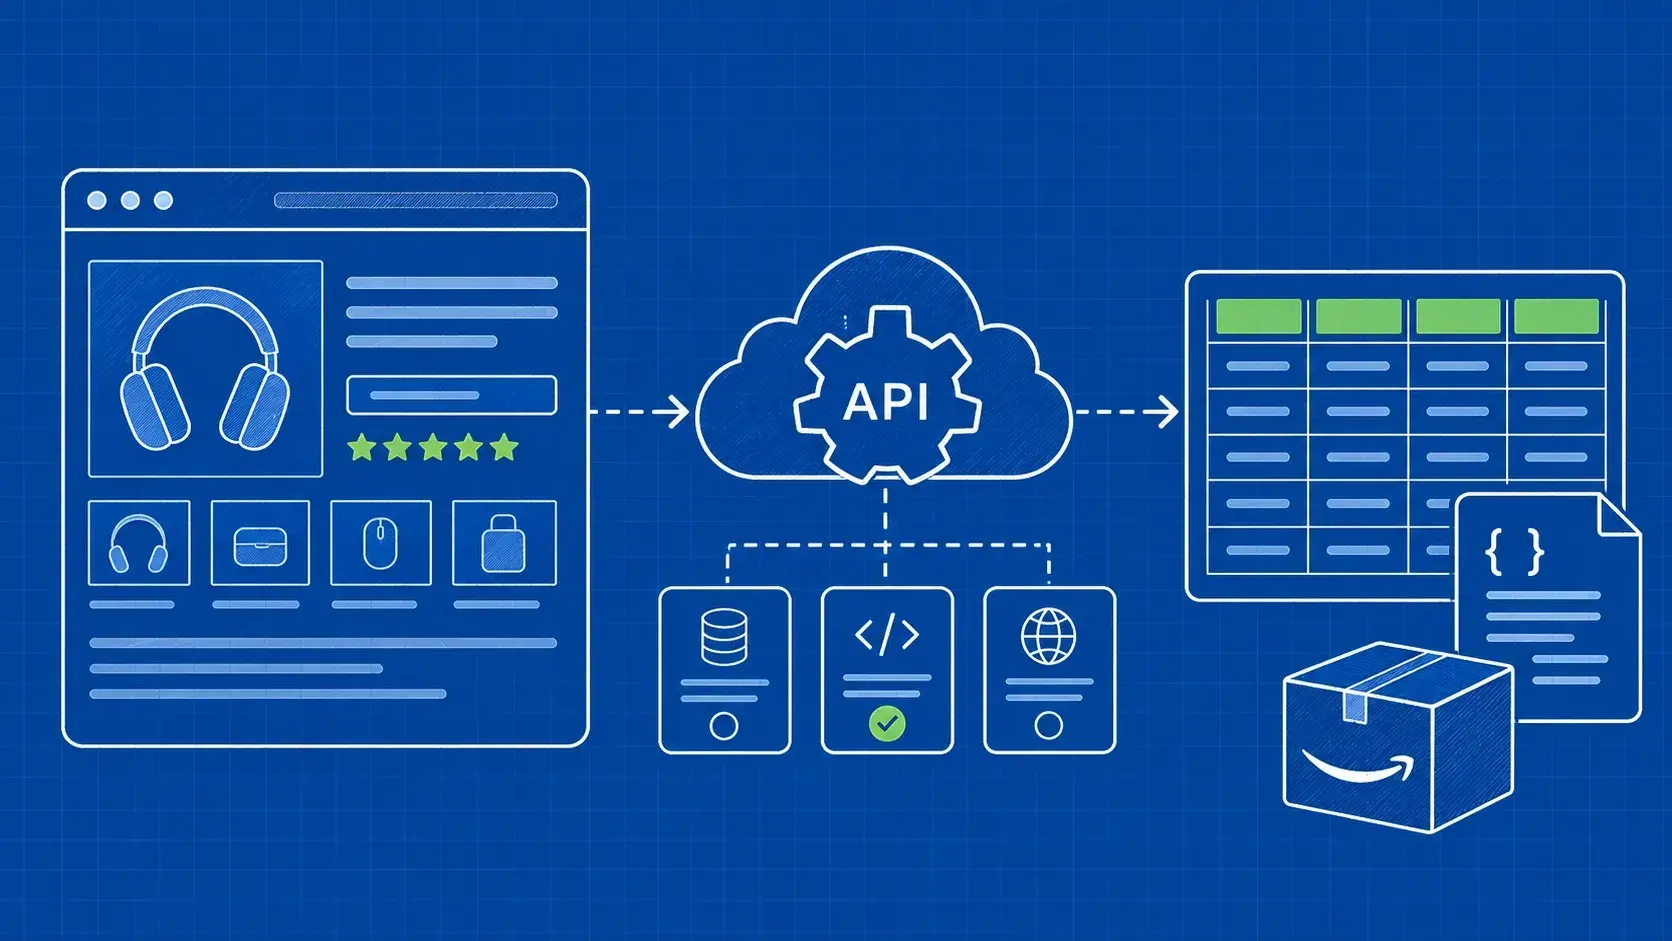
Best Amazon Scraping API: Start with the Output

Suppose you want a daily spreadsheet of product prices. A downloaded Amazon page still leaves you with extraction work. A parsed response can give you named fields, but you must check what each price represents and whether the product matches your request.

There are three useful starting points:

Approach

What you receive

What your team owns

General page retrieval API

Page content for a supplied URL

Parsing, field definitions, validation, storage

Dedicated Amazon endpoint

A documented product, search, or offer schema

Mapping that schema to your application and checking records

Managed collection workflow

Jobs, schedules, and delivery around extraction

Defining the workload and accepting the delivered dataset

These categories can overlap within one provider. Select the endpoint and workflow, not just the company name. A service that supports browser rendering may also have an Amazon parser, but those capabilities are not interchangeable.

For a first price-monitoring project, start with a dedicated product endpoint if its fields cover your needs. For an existing parser that handles multiple retailers, managed page retrieval may fit better. For overnight collections, inspect job tracking and result delivery before optimizing response time. Our guides to scraping Walmart product data and eBay price intelligence cover two other retail targets.

The best Amazon scraping API is therefore the one that produces your required output with manageable integration work. Our web access API comparison explains these operating responsibilities in more detail.

Five API Options to Evaluate

This shortlist reflects public product documentation checked in September 2026. It is a comparison of documented capabilities, not a hands-on speed or success-rate ranking. The fit recommendations below are editorial judgments; confirm them with your own sample workload.

WebScrapingAPI: managed retrieval for your own parser

Scraper API accepts a target URL and manages page retrieval, including proxy routing and optional JavaScript rendering. It is a candidate when you already extract Amazon product data yourself or want one retrieval interface across several websites.

Treat the response as input to your extraction pipeline. Do not assume the general retrieval endpoint returns a standardized Amazon product record. Your application still needs to identify the product, interpret prices, and validate missing fields.

The main selection question is ownership: do you want to maintain parsing rules while outsourcing access operations? If yes, test representative Amazon URLs with your existing parser and measure the proportion that becomes useful records. If you want predefined Amazon fields immediately, include a dedicated endpoint such as our Amazon Data API in the same trial.

ScrapingBee: product, search, and pricing endpoints

The current Amazon API documentation lists separate product, search, and pricing endpoints. Product lookup uses an ASIN, while location and marketplace parameters let you specify the context of the request. The documentation also distinguishes light requests from requests that force JavaScript rendering.

This is a candidate for an application that wants parsed Amazon responses without starting from HTML selectors. During evaluation, check the exact fields returned by each endpoint rather than assuming that a product lookup includes every offer or search detail.

Pay attention to the requested mode. A more expensive request can be worthwhile when it supplies required content, but rendering should have a measurable purpose. Test the least costly suitable configuration against your acceptance rules before increasing it.

Scrape.do: distinct product and seller-offer collection

The Amazon plugin documentation describes dedicated product-detail, offer-listing, and search routes, alongside a raw HTML route. That separation is useful when you need to distinguish the displayed product information from the seller offers attached to it.

Consider this option when your workload includes offer comparison as well as product tracking. The All Offers documentation provides the relevant response contract; review seller, shipping, and availability fields against your intended use.

A named endpoint does not remove the need to check coverage. Include products with different offer patterns in the trial and confirm how empty or unavailable results appear. Also verify the supported delivery-location settings for each marketplace you actually need.

Scrapingdog: product and search workflows

The current product documentation describes ASIN-based requests with marketplace and localization parameters. Its search documentation covers a separate search endpoint. Product response examples include formatted price text and a price symbol, which is a useful reminder that parsed output may still require normalization.

This is a candidate when your first workflow is product lookup or keyword-based discovery and you want to evaluate a documented Amazon response directly. Check the current parameter names; older examples may point to different documentation paths.

Use your trial to examine variant identifiers, missing prices, and the requested location. A schema with many fields is helpful only when the fields your application needs are present and correctly interpreted. Record those requirements before comparing response sizes.

ScraperAPI: asynchronous structured product jobs

The asynchronous product documentation describes submitting an ASIN or multiple ASINs, receiving job information, and retrieving the result after completion. It also documents webhook callbacks, which can notify your application about a job rather than keeping one request open throughout collection.

Consider this option when your workflow naturally runs in batches. Evaluate both the data and the job lifecycle: submission, completion, failure, result retrieval, and duplicate delivery handling.

An accepted job is not a completed dataset. Your application should retain the job identifier and check whether the final response meets its record rules. For a scheduled catalog refresh, compare total completion time and accepted records, not just how quickly the submission endpoint responds.

Check Marketplace, Offers, and Field Meaning

A useful price observation needs context. Record the Amazon marketplace, requested delivery location, product identity, and collection time alongside the extracted value. Otherwise, a change in request settings can look like a price change.

Delivery localization deserves a separate check from proxy geography. A country parameter may select where a request originates; a postal-code parameter may control the delivery context displayed by the page. Read the endpoint documentation to learn which behavior each setting controls. Do not assume two providers use identical parameter names or meanings.

Define your record before choosing the best Amazon scraping API. For a simple monitoring job, the following is an illustrative internal format, not an actual response from any provider:

{
  "marketplace": "amazon.com",
  "requested_asin": "EXAMPL1234",
  "resolved_asin": "EXAMPL1234",
  "delivery_postcode": "10001",
  "observed_at": "2026-09-10T10:00:00Z",
  "price_text": "$24.99",
  "currency": "USD",
  "availability": "in_stock",
  "seller_id": null
}

The ASIN and values above are invented to show the structure. Preserve the requested identifier separately from the resolved identifier so a redirected or selected variant does not silently become the same record. Keep the original displayed price when converting to a numeric amount.

For offer comparisons, add seller identity, shipping charges, item condition, and the offer context you require. For Amazon search results, keep the query, page, and position context. A product detail response and a search result row describe different observations.

Decide what a missing value means. A null price can represent unavailable data; it should not become a zero-dollar offer. Similarly, a rating count is not the same field as the number of written reviews returned.

These definitions make the best Amazon scraping API easier to evaluate because every candidate must satisfy the same record contract.

Compare Cost per Usable Record

A plan's headline credit allowance is not a count of finished product records. Endpoint choice, rendering settings, extra offer requests, and your own rejected outputs can change the useful quantity you obtain.

For example, the documented light product request in the shortlist costs five credits, while forcing full rendering costs fifteen. That is a configuration difference within one service. Credits from different providers are not interchangeable units of value.

Use two calculations in your comparison:

API cost per accepted record = API spend / accepted records
Effective cost per accepted record =
  (API spend + storage + allocated operating work) / accepted records

Here is a hypothetical example, not provider pricing. Option A costs $30 for a trial that produces 8,000 accepted records. Its API cost is $3.75 per 1,000 accepted records. Option B costs $40 and produces 12,000 accepted records, or about $3.33 per 1,000. The larger bill buys a lower unit cost in this example.

Keep the denominator consistent. Comparing product pages from one provider with every search-result row from another creates a misleading number. Define whether you are buying a product observation, an offer, or a search result, and count only records that pass the same rules.

Before committing, review endpoint billing, failed-request treatment, concurrency, unused credits, and overage terms. Ask how a successfully retrieved but incomplete page is charged. Check the current plan details rather than reusing prices from an older roundup.

The best Amazon scraping API for your budget minimizes the cost of usable output at the freshness you need. It does not necessarily have the smallest monthly subscription or the largest advertised allowance.

To try one hands-on, our Amazon Scraping API start guide shows how to request Amazon product and search pages through the API and read the parsed results.

Run a Small Trial Before Choosing

Give each candidate the same workload. A trial built around one popular product cannot tell you whether a service handles your categories, marketplaces, and edge cases.

Create a sample that reflects the project: ordinary products, products with variants, unavailable items, and the search or offer pages you need. Include each required marketplace and delivery context. Choose a manageable sample size for manual inspection and your available trial allowance; there is no universal number that proves reliability.

Use this acceptance scorecard when selecting the best Amazon scraping API:

Check

Accept when

Investigate when

Identity

Requested and returned products match your rule

A variant or redirect changes the item

Location

Marketplace and delivery context match

Output reflects a default location

Required fields

Values are present and meaningful

A price is empty or an offer lacks context

Freshness

Observation fits the required collection window

Cached or delayed results are unsuitable

Completion

Expected jobs reach a recorded final state

Submissions or partial batches remain unresolved

Cost

Billing can be tied to accepted observations

Request counts hide rejected data

Run the same validation against every response. Separate transport failures, unexpected page content, parser failures, and business-rule failures. A response that arrives successfully but contains the wrong product should fail the identity check even if it is valid JSON.

Inspect a subset against the displayed page using equivalent location settings and a close collection time. Save enough context to explain differences later. For fast-changing values, a page viewed much later is weak evidence that the earlier record was wrong.

Measure completion time from the start of collection until usable records are available. For asynchronous systems, include queueing and result retrieval. If you report latency, include the workload, observation window, and slow-tail behavior rather than only an average.

Repeat the sample at another relevant time before treating the result as stable. Keep trial results as observations about that workload, not guarantees for every Amazon page. This is the practical way to identify the best Amazon scraping API for a specific project without relying on a vendor's broad ranking claim.

Plan the Collection Workflow

Once the trial produces trustworthy records, define how the recurring job will run. Separate discovery from refresh: finding new product URLs or ASINs is a different task from revisiting a known list.

For price monitoring, assign a refresh interval that matches the decision the data supports. Group work by marketplace and request context so configuration stays explicit. Avoid increasing frequency merely because additional concurrency is available. Price monitoring is one of the uses of web scraping, and other jobs such as review tracking or market research may need a different refresh schedule.

Keep one record of each scheduled observation and its final outcome. A retry should update the job's state without silently creating duplicate business observations. Limit retries, retain useful error context, and make exhausted jobs visible to the person operating the collection.

If a provider delivers results through callbacks, plan for repeated notifications and delayed completion. Store the provider job identifier beside your internal job identifier. That connection helps support teams investigate a failed batch without guessing which request produced it.

Version your normalization rules. A change to a field mapping should be distinguishable from a change in the source data. Preserve the context you need for debugging while setting a deliberate retention policy for stored responses.

Finally, assign ownership of parser changes, billing review, and incomplete jobs. The best Amazon scraping API reduces the work of obtaining data, but someone still needs to decide whether the resulting observations are suitable for the application. Make that decision part of the workflow before scaling the collection.

Key Takeaways

  • Choose the output contract first. Page content, parsed product fields, seller offers, and completed collection jobs solve different parts of the task. Compare endpoints that address the same requirement.
  • Keep product and location context with every observation. A usable price record needs more than a value; the requested item, selected variant, marketplace, and collection time make it interpretable.
  • Calculate cost using accepted records. Include configuration changes and rejected output in the evaluation, then account for the work your team will still operate.
  • Treat a trial as evidence about a defined workload. Use the same inputs and checks for each candidate, inspect failures, and repeat the sample before relying on the results.

FAQ

Can I recover historical prices with a new scrape?

A new observation cannot establish what a page showed last month. If you need a historical series, collect and timestamp observations over time or evaluate a separate historical dataset with documented coverage. Distinguish the time a provider collected a value from the time you downloaded it. Do not backfill missing dates by presenting today's price as an earlier observation.

How should I protect my API credentials?

Keep credentials in a server-side secret store or environment configuration. Avoid embedding them in browser code, shared spreadsheets, screenshots, or public repositories. Redact credentials from request logs, especially when an API uses query-string authentication. Limit access to the people and services running the collection, and replace a key if it has been exposed.

Can scraped rating counts tell me exact sales?

No. Rating counts and sales totals are different measurements. A relationship you infer between them is an estimation model, not an extracted sales record. If you use such a model, label the result as an estimate and explain its assumptions. Keep observed source fields separate from calculated metrics so readers can tell which values came directly from collection.

How can I make switching providers easier?

Keep provider-specific request parameters and response mappings behind a small integration boundary. Store a stable internal record format and test each mapping against representative saved responses. When replacing a provider, compare the meaning of fields as well as their names. Document differences explicitly instead of forcing a new response into an old field that means something else.

Conclusion

The best Amazon scraping API is the one that delivers the observations your project needs with a cost and operating model you can sustain. Begin with the output: a product record, a seller offer, a search result, or page content for an existing parser. Then make the request context and acceptance rules explicit.

Use the shortlist to choose a small number of candidates that fit those requirements. Run the same sample through each, inspect the returned records, and calculate the cost of accepted output. Keep documented capabilities separate from what the trial demonstrates. That distinction will help you make a defensible choice as your workload grows.

If managed page retrieval fits your architecture, evaluate Scraper API from WebScrapingAPI with representative Amazon URLs and your own extraction rules. Use the same acceptance checklist you apply to dedicated Amazon endpoints so the decision reflects the work your application actually needs.

Before expanding the job, save the sample, its settings, and the validation rules. Those artifacts become your reference when an endpoint changes, a field disappears, or a future provider enters the comparison.

About the Author

Robert Sfichi, Full-Stack Developer @ WebScrapingAPI

Robert Sfichi

Full-Stack Developer

Robert Sfichi is a team member at WebScrapingAPI, contributing to the product and helping build reliable solutions that support the platform and its users.

Alternative Data Scraping for Finance: Sources & Pipelines
Use Cases

Alternative Data Scraping for Finance: Sources & Pipelines

TL;DR: Alternative data scraping uses web collection techniques to gather non-traditional datasets (product pricing, sentiment, job postings, regulatory filings) that reveal market signals before they appear in earnings reports. This guide walks you through the highest-value data sources, how to build financial-grade pipelines, data quality validation, and the compliance guardrails you need to stay on the right side of the law.

Mihnea-Octavian Manolache15 min read
Read Article
What Is Financial Data? Types, Sources, and Analysis Tools
Use Cases

What Is Financial Data? Types, Sources, and Analysis Tools

TL;DR: Financial data is the collection of quantitative records (income, expenses, assets, liabilities, cash flow) that organizations and individuals use to make informed economic decisions. This guide breaks down the four core financial statements, compares traditional and alternative data sources, walks through modern collection methods, and covers the tools professionals rely on for analysis.

Suciu Dan13 min read
Read Article
XPath vs CSS Selectors: Choosing the Right One
Use Cases

XPath vs CSS Selectors: Choosing the Right One

TL;DR: XPath and CSS selectors both locate DOM elements, but they solve different problems. CSS selectors are faster and more readable for straightforward selections. XPath wins when you need to traverse the DOM in any direction, match text content, or handle complex conditional logic. Most production projects benefit from using both strategically.

Mihai Maxim12 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.