Skip to content
Start free

Author Profile

Suciu Dan

Co-founder25 articles

Suciu Dan is the co-founder of WebScrapingAPI and writes practical, developer-focused guides on Python web scraping, Ruby web scraping, and proxy infrastructure.

Suciu Dan, Co-founder @ WebScrapingAPI

Published Articles

25 articles

Python web scrapingRuby web scrapingproxy infrastructureanti-bot resilienceGuidesScience of Web ScrapingUse Cases

Published Articles

Web Scraping With AWS Lambda: Guide for Python, Java 2026
Guides

Web Scraping With AWS Lambda: Guide for Python, Java 2026

TL;DR: Web Scraping With AWS Lambda works best when each invocation is short, bounded, and independently retryable. Start with direct HTTP, AWS SAM, and S3, then add SQS, containers, browser rendering, proxies, or a managed fetch layer only when the workload proves it needs them.

Suciu Dan24 min read
Read Article
How To Use GoSpider: Crawl, Clean URLs, and Extract Data
Guides

How To Use GoSpider: Crawl, Clean URLs, and Extract Data

TL;DR: GoSpider is a command-line crawler for discovering URLs, not a complete structured-data scraper. This How To Use GoSpider guide shows a bounded crawl, clean output handling, a Colly-to-CSV handoff, and a diagnostic path for 403 responses or pages that require JavaScript rendering.

Suciu Dan18 min read
Read Article
How to Scrape Redfin: Python Guide to Property Data
Guides

How to Scrape Redfin: Python Guide to Property Data

TL;DR: Redfin exposes hidden API endpoints that return structured JSON for property listings, making it possible to skip fragile HTML parsing entirely. This guide walks you through building a Python scraper that extracts rental and sale data, searches by location, monitors new listings via XML sitemaps, and exports clean results to CSV or JSON.

Suciu Dan11 min read
Read Article
How to Parse JSON in Python: From API Responses to JSON Hidden in Web Pages
Guides

How to Parse JSON in Python: From API Responses to JSON Hidden in Web Pages

TL;DR: To parse JSON in Python, use the built-in json module: json.loads() for a string or bytes, json.load() for a file, and Requests' response.json() for an HTTP response. Check the HTTP status and JSON validity separately, because a 200 response can still be HTML. This guide also covers decode errors, nested access, validation, large files, and JSON hidden inside web pages.

Suciu Dan11 min read
Read Article
Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production
Science of Web Scraping

Nodriver Python Tutorial: Stealth Browser Scraping From First Script to Production

TL;DR: Nodriver is an async Python library that drives Chromium over the Chrome DevTools Protocol, with no Selenium or chromedriver binary. Use it when a self-hosted stealth browser closer to a real Chrome session beats a WebDriver stack, but know it doesn't remove IP, TLS, or behavioral risk on its own. This tutorial goes from a first script to containerized production and a hosted Browser API.

Suciu Dan11 min read
Read Article
How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper
Science of Web Scraping

How to Handle Google /goto Redirect URLs and CAES Tokens in a SERP Scraper

TL;DR: Google /goto URLs with a CAES token, and older /url wrappers, are redirect layers, not destinations, so a SERP scraper that treats every href as final breaks rank tracking and link stores. Prefer a structured SERP API when it returns destination links. When you must parse HTML, classify every href, dedupe redirects, and resolve them with a plain GET. Do not decrypt CAES.

Suciu Dan11 min read
Read Article
10 Best AI Web Scraping Tools for 2026
Guides

10 Best AI Web Scraping Tools for 2026

TL;DR: No single AI scraper wins every workload. Compare 10 tools by extraction method, user type, operations, and cost, then use a practical test plan to choose the right fit.

Suciu Dan19 min read
Read Article
XPath Web Scraping: A Hands-On Guide with Python Examples
Guides

XPath Web Scraping: A Hands-On Guide with Python Examples

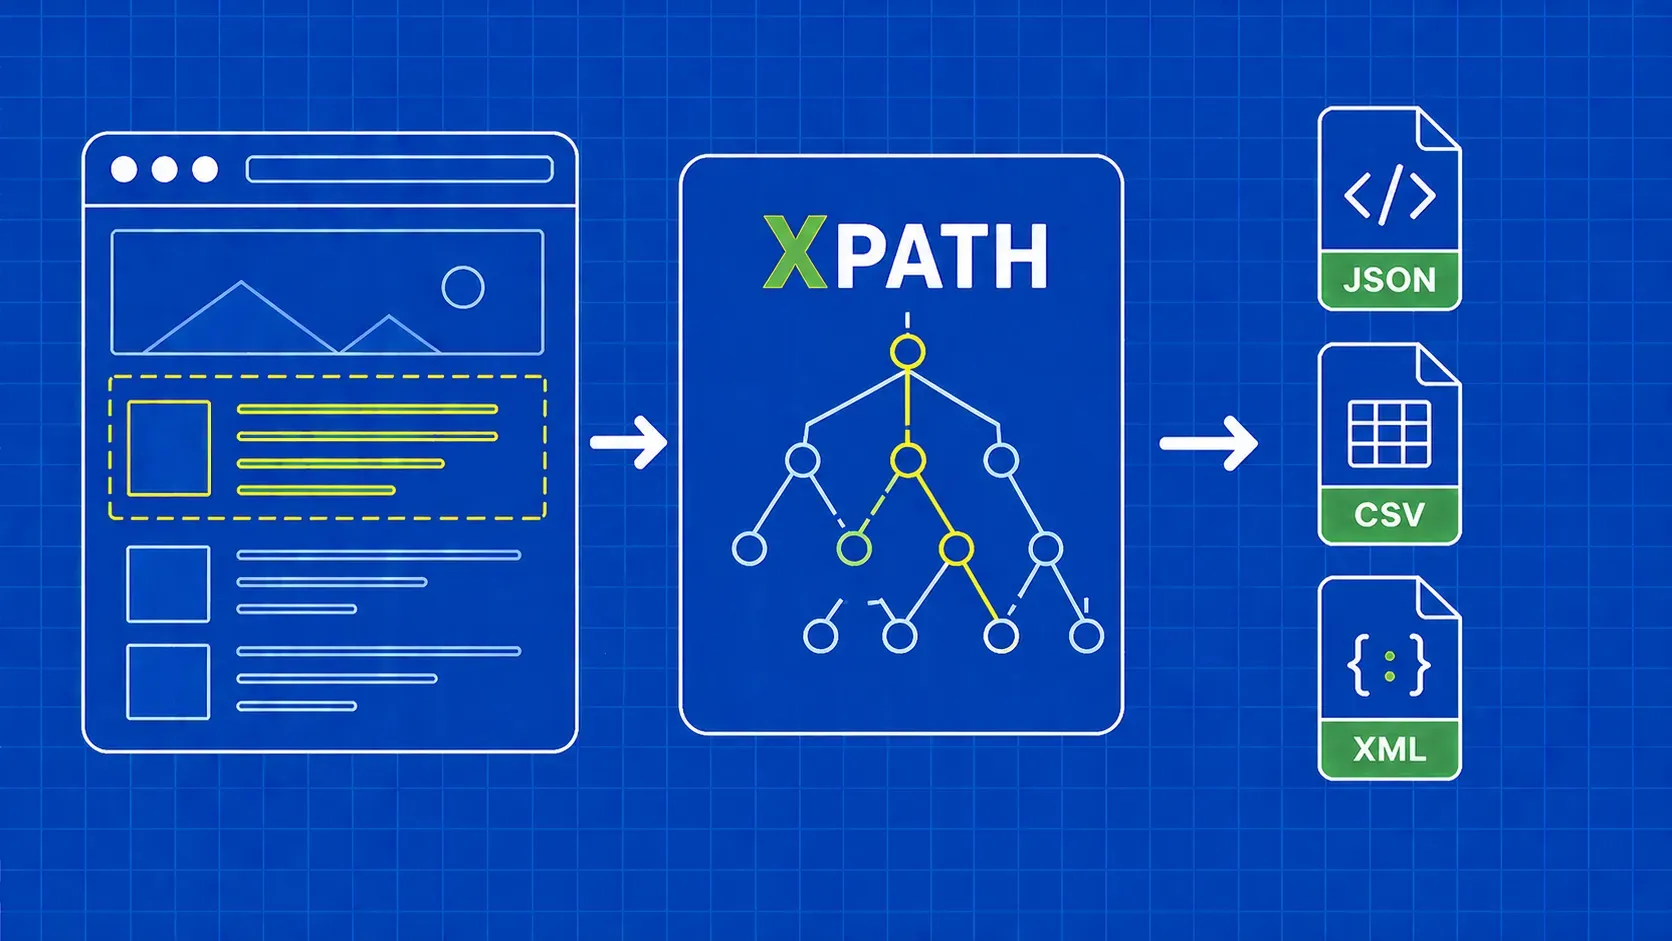
TL;DR: XPath is a query language for navigating HTML/XML trees by path, attribute, or text content. This guide covers XPath syntax, axes, and functions, then shows working Python scrapers with lxml and Selenium. You will also get a consolidated cheat sheet and a troubleshooting section for the most common XPath mistakes.

Suciu Dan9 min read
Read Article
HTTP Response Headers in cURL: Every Flag and Recipe
Science of Web Scraping

HTTP Response Headers in cURL: Every Flag and Recipe

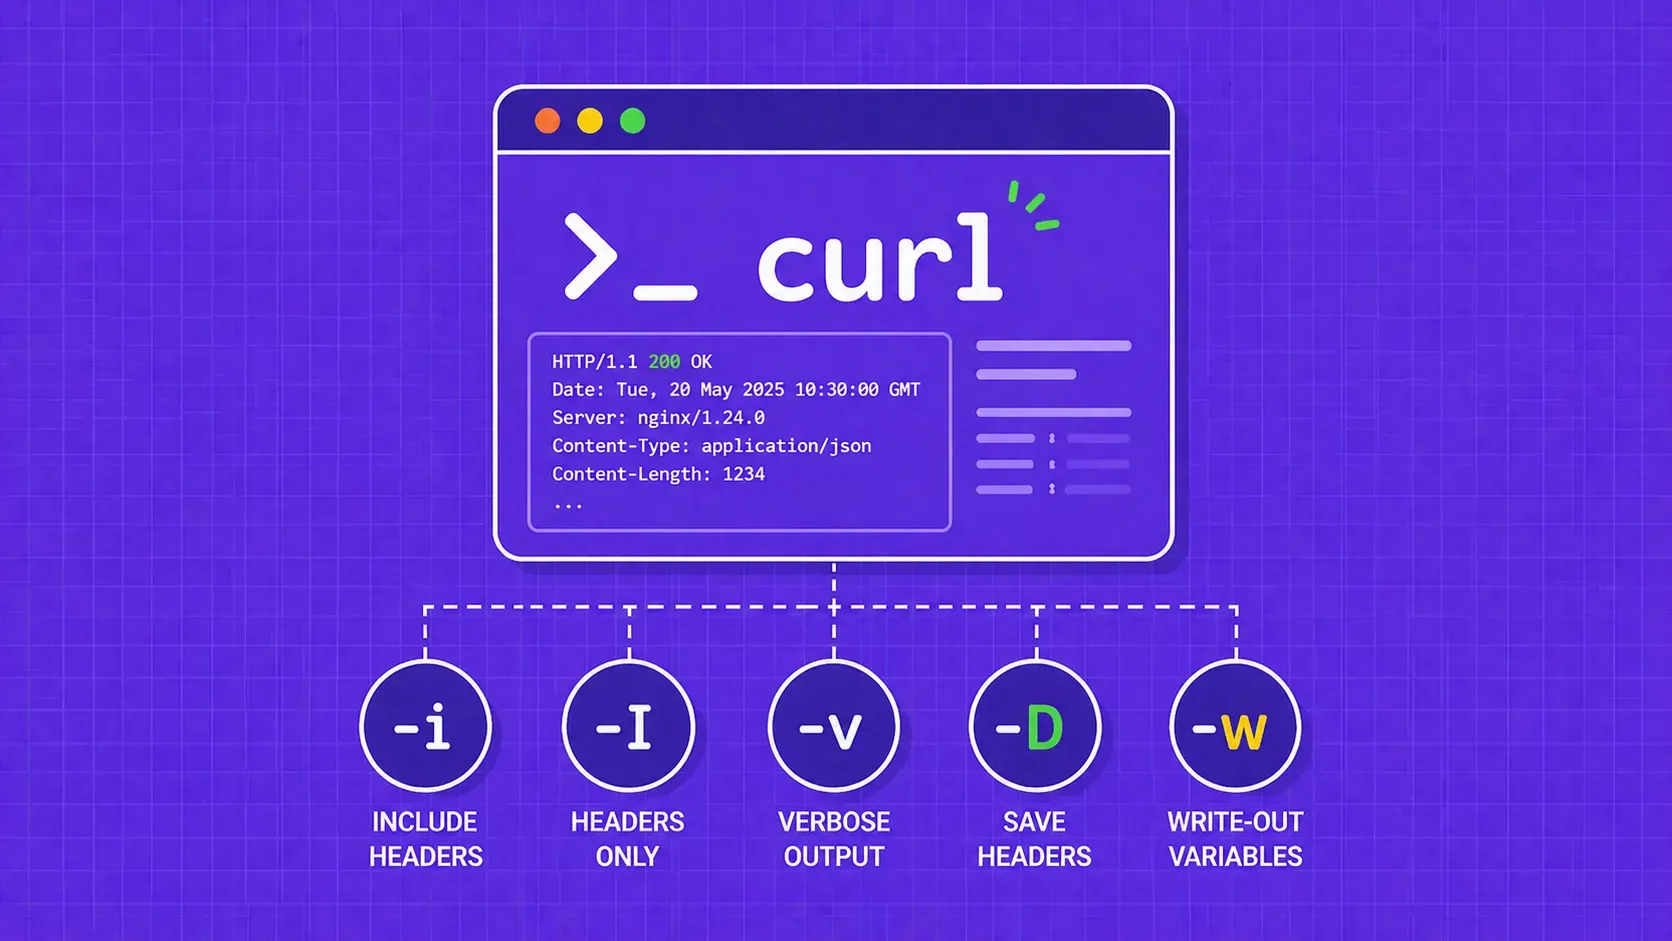
TL;DR: cURL hides response headers by default. Use -i to see headers alongside the body, -I for a HEAD request that returns headers only, -v for full request/response debugging, and -D to save headers to a file. For modern scripting, cURL 7.83+ lets you extract individual headers or dump all of them as JSON with the -w write-out option.

Suciu Dan11 min read
Read Article
What Is a Headless Browser? Uses, Tools, and Setup
Science of Web Scraping

What Is a Headless Browser? Uses, Tools, and Setup

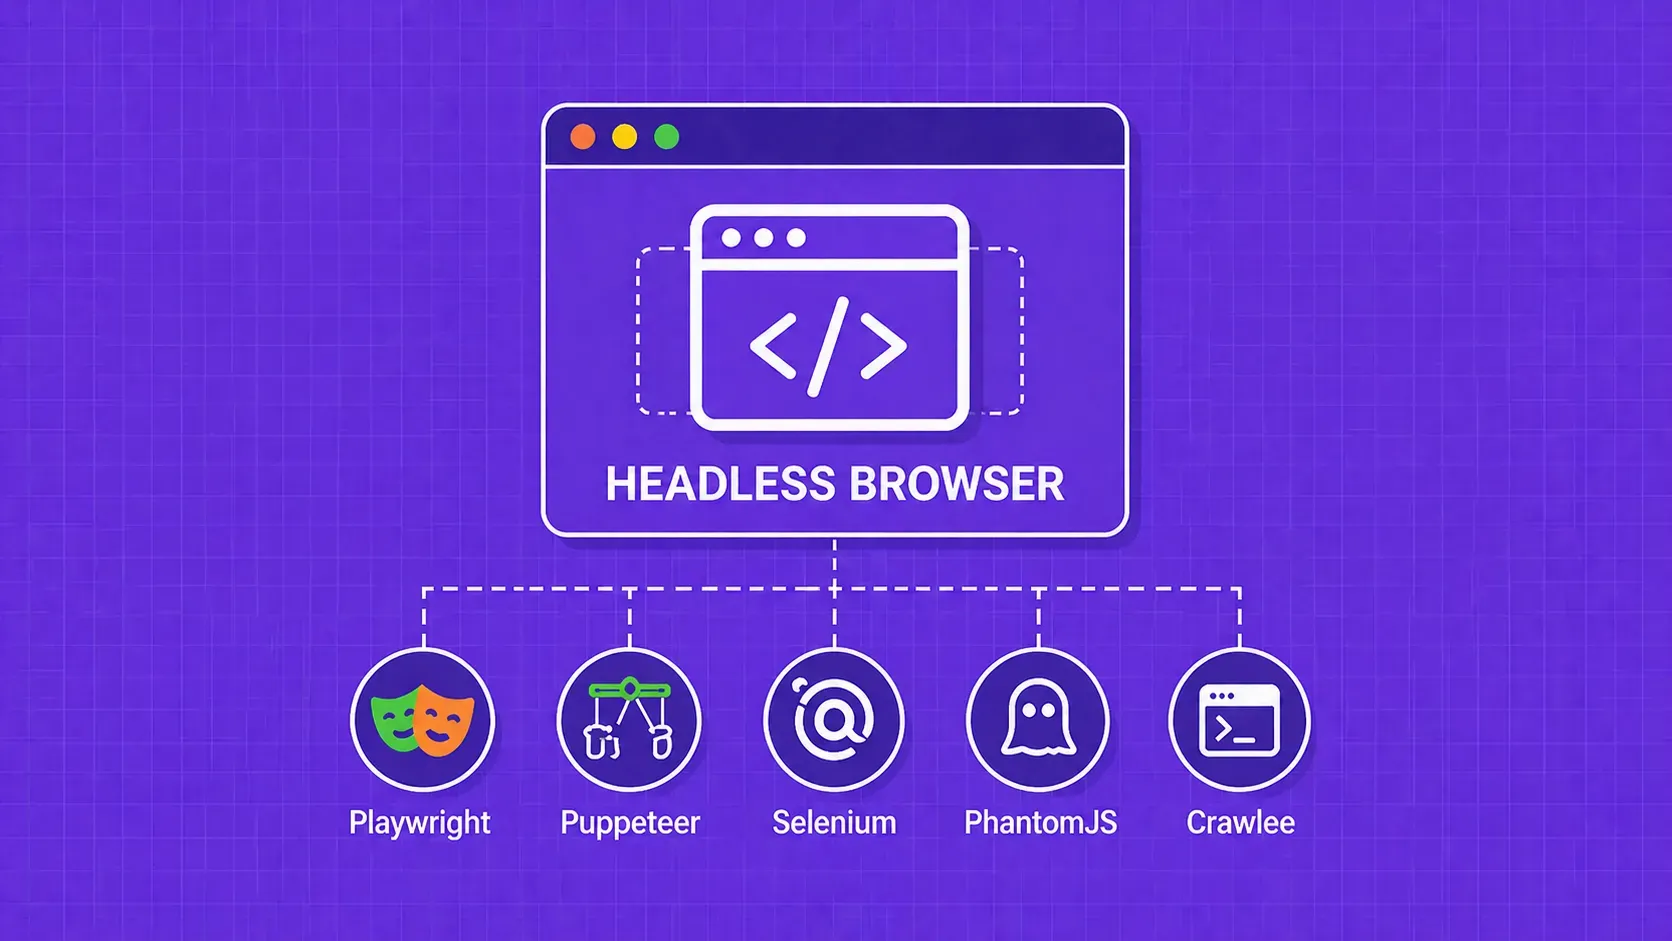
TL;DR: A headless browser is a web browser that runs without a visible graphical interface, controlled entirely through code or command-line instructions. Developers use headless browsers for automated testing, web scraping, performance monitoring, and increasingly to power AI agents. This guide covers how they work internally, when to choose one over a regular browser, and which frameworks are worth your time.

Suciu Dan13 min read
Read Article
SERP Scraping API Guide: Google, Bing, DuckDuckGo, Yandex
Guides

SERP Scraping API Guide: Google, Bing, DuckDuckGo, Yandex

TL;DR: To use the SERP Scraping API, send a GET request to https://serpapi.webscrapingapi.com/v2 with api_key, engine, and your query (q for most engines, text for Yandex). Google and Bing return parsed JSON, while DuckDuckGo and Yandex return the results page's HTML for your code to extract, so plan parsing and tests around that split. This guide also covers localization, async jobs, errors, and pricing.

Suciu Dan20 min read
Read Article
What Is Financial Data? Types, Sources, and Analysis Tools
Use Cases

What Is Financial Data? Types, Sources, and Analysis Tools

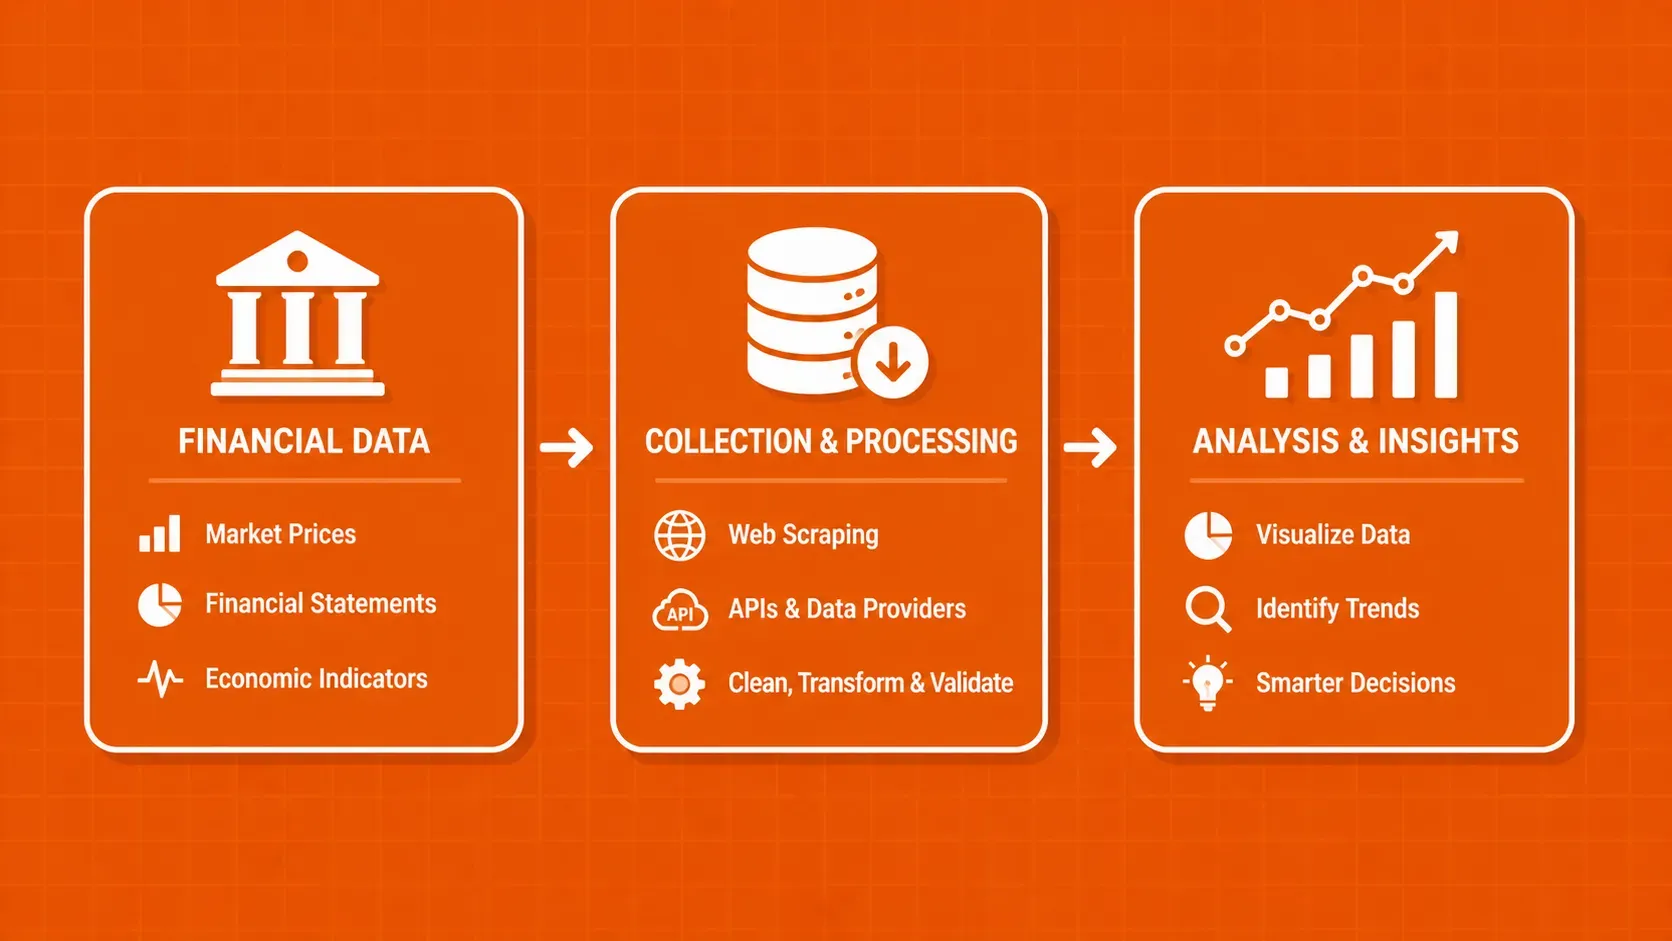
TL;DR: Financial data is the collection of quantitative records (income, expenses, assets, liabilities, cash flow) that organizations and individuals use to make informed economic decisions. This guide breaks down the four core financial statements, compares traditional and alternative data sources, walks through modern collection methods, and covers the tools professionals rely on for analysis.

Suciu Dan12 min read
Read Article
Data Parsing
Science of Web Scraping

Data Parsing

TL;DR: Data parsing converts raw content (HTML, JSON, XML, PDFs) into structured fields your code can actually use. This guide walks through how data parsing works step by step, compares the major techniques and libraries, and gives you a practical framework for deciding whether to build or buy your parsing layer.

Suciu Dan14 min read
Read Article
How to Set Up Axios Proxy in Node.js: Auth, Rotation, SOCKS5
Guides

How to Set Up Axios Proxy in Node.js: Auth, Rotation, SOCKS5

TL;DR: Axios routes requests through a proxy by accepting a proxy object with host, port, and optional auth fields. This guide covers how to set up Axios proxy configuration from scratch: basic wiring, authenticated proxies, HTTPS tunneling, a rotation system using interceptors, SOCKS5 via socks-proxy-agent, and diagnosing common errors. Every snippet is copy-pasteable Node.js code.

Suciu Dan10 min read
Read Article
How to Use a Proxy with HttpClient in C#
Guides

How to Use a Proxy with HttpClient in C#

TL;DR: To use a proxy with HttpClient in C#, build a WebProxy, attach it to an HttpClientHandler (or SocketsHttpHandler), and pass that handler to the HttpClient constructor. For production, swap manual loops for IHttpClientFactory, add NetworkCredential for authenticated proxies, and wrap calls in retries with Polly so dead IPs do not take your worker down.

Suciu Dan16 min read
Read Article
How to Build a Python Web Crawler: From Start to Scale
Science of Web Scraping

How to Build a Python Web Crawler: From Start to Scale

TL;DR: A python web crawler automates the tedious work of following links across a website to discover and collect content. This guide walks you through building one from scratch with requests and BeautifulSoup, then graduating to Scrapy for concurrent crawling, item pipelines, and structured data exports. You will also learn how to crawl responsibly, rotate proxies to avoid blocks, and handle JavaScript-rendered pages.

Suciu Dan27 min read
Read Article
LinkedIn Scraper: How to Scrape LinkedIn with Python
Guides

LinkedIn Scraper: How to Scrape LinkedIn with Python

TL;DR: Scraping LinkedIn means working around an aggressive auth wall, behavioral tracking, and TLS fingerprinting. This guide gives you a method-by-page-type decision tree, working Python patterns for jobs, profiles, and companies (hidden API, JSON-LD, Selenium when needed), and a consolidated anti-block checklist for 2026.

Suciu Dan11 min read
Read Article
12 Best Free Web Scraping Tools in 2026: Compared
Guides

12 Best Free Web Scraping Tools in 2026: Compared

TL;DR: The 12 best free web scraping tools in 2026 split into four buckets: managed APIs with free credits, open-source frameworks, no-code browser extensions, and AI extractors. Pick by use case first (one-off scrape vs. scheduled pipeline), then by skill level. Most free tiers cover evaluation, not production; the moment your success rate drops below ~90% or you burn more hours on blocks than on data, it is time to graduate to a paid API.

Suciu Dan24 min read
Read Article
Is Web Scraping Legal in 2026? Compliance Framework
Guides

Is Web Scraping Legal in 2026? Compliance Framework

TL;DR: Is web scraping legal? Usually yes, with caveats. Legality depends on the data type, the access path, the jurisdictions involved, and what you do with the output. This guide gives you a direct verdict, a five-minute pre-scrape framework, the cases that matter, and a checklist you can run before you ship.

Suciu Dan12 min read
Read Article
Best Web Scraping APIs in 2026: 12 Compared by Job and Cost
Guides

Best Web Scraping APIs in 2026: 12 Compared by Job and Cost

TL;DR: The best web scraping API depends on the job: a cheap page API wins on static HTML, a render flag or hosted browser on JavaScript-heavy apps, a SERP or ecommerce endpoint for parsed records, and a markdown-focused API for LLM pipelines. Shortlist two or three providers, then compare cost per usable page on your own URLs, because credit multipliers and failed-request billing decide the real cost.

Suciu Dan23 min read
Read Article
webscraper.io Review: Pricing, Limits, and When to Switch
Guides

webscraper.io Review: Pricing, Limits, and When to Switch

TL;DR: Web Scraper from webscraper.io is a free Chrome and Firefox extension plus a paid Web Scraper Cloud, and it's a sound pick for small and medium recurring jobs on ordinary public sites. Keep it when a few people refresh a handful of sites daily or weekly and someone maintains the selectors. Switch when you need many sites, protected or JavaScript-heavy targets, or code-level control.

Suciu Dan15 min read
Read Article
Puppeteer Alternatives: Top Tools for Scraping & Testing
Guides

Puppeteer Alternatives: Top Tools for Scraping & Testing

TL;DR: Puppeteer is great for quick Chromium automation, but its single-browser lock-in, resource-heavy scaling, and zero built-in anti-bot support push many teams toward alternatives. This guide breaks down the strongest Puppeteer alternatives by use case (scraping, E2E testing, cross-browser QA, mobile), gives you a side-by-side comparison table, and ends with a decision framework so you can pick the right tool without trial-and-error.

Suciu Dan14 min read
Read Article
Web Scraper Alternative: Match the Workflow First
Guides

Web Scraper Alternative: Match the Workflow First

TL;DR: Compare Octoparse, Browse AI, Apify, and Playwright by authoring model. Preserve navigation, record identity, and delivery behavior when replacing Web Scraper.

Suciu Dan13 min read
Read Article
WebHarvy Alternative: Compare Four Tools
Guides

WebHarvy Alternative: Compare Four Tools

TL;DR: Compare Octoparse, ParseHub, Web Scraper, and Apify for product extraction. Validate variants, offers, missing items, and exports before replacing WebHarvy.

Suciu Dan13 min read
Read Article
Node.js Web Scraping: 6 Best Libraries Compared for 2026
Guides

Node.js Web Scraping: 6 Best Libraries Compared for 2026

TL;DR: The best Node.js web scrapers in 2026 split into two camps: HTTP clients like Axios and Superagent for static pages, and headless browsers like Puppeteer and Playwright for JavaScript-heavy sites. Pick by workflow, not popularity, and offload rendering to a managed scraping API once anti-bot defenses or scale start eating your engineering time.

Suciu Dan10 min read
Read Article
Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.