Skip to content
Start free
Back to Blog

Niche Scraper Alternative: Pick by Research Task

Mihnea-Octavian ManolacheLast updated on 12 min read
Niche Scraper Alternative: Pick by Research Task
TL;DR: Choose a Niche Scraper alternative for the research job you actually need: curated product ideas, an integrated store workflow, marketplace analysis, or your own data pipeline. Compare evidence provenance, matching quality, and exportability before treating a product score as a buying decision.

A product card says an item is trending. Your application needs to know which item, in which market, over what period, and on what evidence. That gap is the real starting point when choosing a Niche Scraper alternative.

Product-discovery software and web extraction infrastructure solve different problems. Discovery tools organize candidate products and market signals. A collector retrieves information from specified sources. Neither automatically provides verified demand, reliable supplier fulfillment, or your eventual margin.

This guide compares several practical routes without pretending that an editorial shortlist is a performance benchmark. The recommendations are based on publicly documented workflows, not paid-account testing. Your trial should establish whether the product supports your required fields and delivery method.

For developers, the useful outcome is not a longer list of supposedly winning products. It is a research process that a teammate can reproduce, inspect, and connect to a decision. Start with the question, then choose the interface and the evidence needed to answer it. Keep a distinction between what a source observed, what a vendor estimated, and what your own business has measured.

Reseller research tools raise the same question, and our comparison of Profit Scraper alternatives draws that line across current offers, sold-price evidence, supplier comparisons, and cost-based estimates.
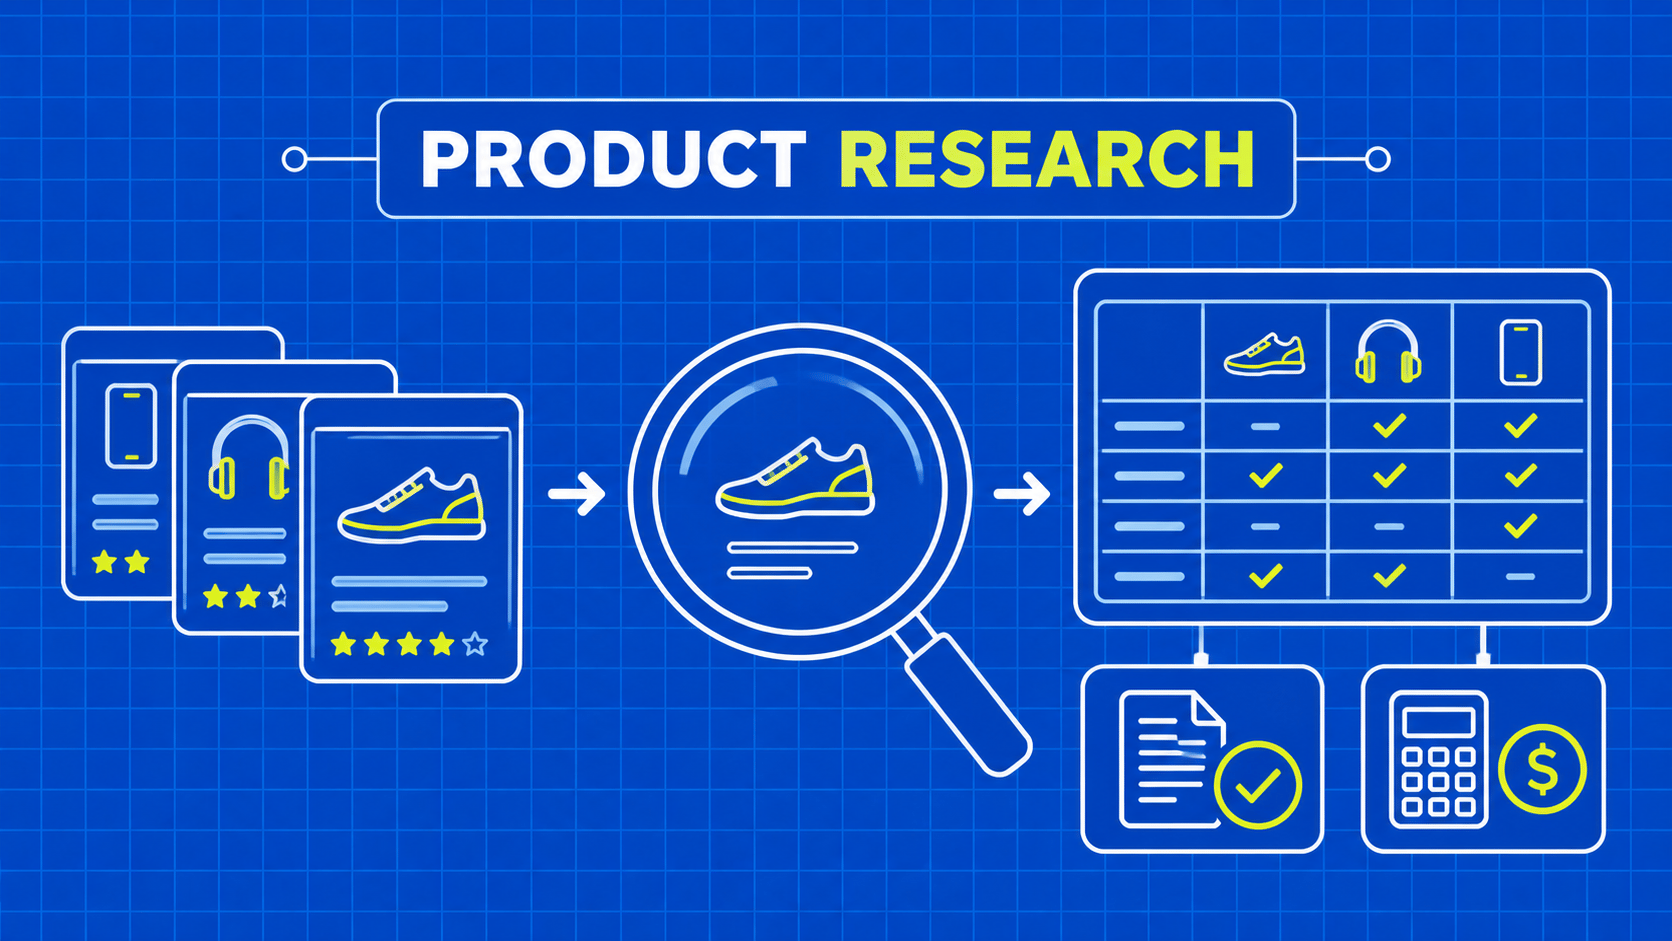
Choose a Niche Scraper alternative by the research job

Write the missing capability as a sentence: “We need fresh supplier offers for these product variants,” or “We need comparable sold-price evidence for this marketplace.” These are more useful requirements than “We want better product research.”

Amazon is one of those marketplaces, and our walkthrough on scraping Amazon product data collects titles, prices, ratings, and ASINs with Python. For the same fields without maintaining a parser, see our Amazon Scraper API quick start.

Niche Scraper positions its service around product discovery and related research. Its own FAQ also emphasizes testing rather than assuming that a selected product will succeed. That is a useful boundary for evaluating any replacement. Niche Scraper's FAQ provides the baseline product context.

Route

Best starting question

What to validate before adopting it

Ecomhunt

Which curated products deserve investigation?

Evidence behind a card and a usable handoff

Sell The Trend

Can research connect to our store workflow?

Supported integration and review controls

ZIK Analytics

What marketplace product opportunities deserve analysis?

Marketplace coverage and metric definitions

Google Trends plus your own collector

How does interest compare, and what do our selected sources show?

Signal interpretation, source permissions, and maintenance

These are different workflow choices, not four interchangeable APIs. A dashboard might help an analyst while remaining awkward for an application that needs scheduled records. Conversely, an excellent extraction pipeline might provide no useful product-discovery ranking.

Classify your requirements as mandatory or optional before starting a trial. Mandatory might mean a particular marketplace, variant identity, or export right. An attractive feature should not compensate for failure on that requirement. This is the same discipline that makes broader web scraping for market research useful rather than merely extensive.

Use Ecomhunt for a curated candidate list

A small team may need a reviewed starting list more than another crawler. Ecomhunt presents curated products alongside information such as supplier context, advertising examples, and engagement-related signals. Those documented features make it a candidate for discovery-led workflows. They do not establish the accuracy of every product-level claim. See the Ecomhunt product overview.

Evaluate one card as a collection of evidence, not as a verdict. Can you identify the underlying product? Can you tell whether the displayed metric is observed or estimated? Can a colleague revisit the source after the card moves out of the main feed? Record unanswered questions instead of filling them with assumptions.

For a development team, handoff matters as much as discovery. Ask whether your chosen plan and terms support the export or integration you need. Do not infer API access because a dashboard contains structured fields. If the workflow is manual, make that explicit in the system design and account for analyst time.

This route fits a human-reviewed queue: an analyst selects a candidate, verifies its identity, and adds it to an internal research record. It is less suitable as an assumed source of complete marketplace history. You are buying a discovery workflow, not independent proof that every candidate will sell.

A sensible acceptance test is to select several distinct product types, including a variant-heavy item and a product with multiple suppliers. Check whether the evidence still makes sense after matching exact size, material, and destination. A polished card loses much of its value when its supplier offer describes a different bundle.

Consider Sell The Trend when research must reach the store

Research sometimes stalls after the shortlist. Someone still has to prepare product records, review supplier choices, and move approved items into the operational workflow. Sell The Trend documents research tools alongside store integrations and fulfillment-related functionality. That makes it worth evaluating when the gap is between discovery and execution. Its official product overview describes those workflow categories.

Keep the trial deliberately narrow. Choose one supported store connection and one approved sample product. Establish what data moves, which fields are transformed, and where a human can stop the process. A successful connection is not enough if descriptions, variants, or shipping assumptions change without a review step.

For developers, write down the system of record for each field. Your internal catalog might own product identity, a supplier might own availability, and the store might own the customer-facing description. If every integration can overwrite every field, debugging becomes a search through competing versions of the truth.

An integrated suite can reduce handoffs, but it can also increase switching cost. Ask how you would recover approved candidates, identifiers, and research notes if you changed tools. Confirm actual export behavior rather than accepting a screenshot of an export button as proof that every necessary field is included.

Use this option when integration reduces a recurring operational bottleneck. Do not choose it simply because it has more features than a research-only tool. Features outside your workflow create configuration and review obligations without necessarily improving the quality of your decisions. Keep publication and purchasing actions outside the research pilot so an experiment cannot silently become a live merchandising change.

Evaluate ZIK Analytics for marketplace-focused research

A marketplace seller and a standalone-store operator do not ask identical questions. Marketplace research often needs comparisons within a particular category, condition, and listing format. ZIK Analytics documents eBay-oriented product and competitor research, making it a candidate for that narrower job. Its eBay product-research page is the appropriate source for its positioning.

Begin with a known category rather than a broad keyword. Separate used products from new ones, accessories from main units, and multipacks from single items. A result set containing all of them can look substantial while answering no coherent pricing question.

Ask the vendor to explain each metric you intend to consume. A sales estimate, listing count, and observed transaction value are different fields. Do not combine them under a generic demand column. If the definition or time window is unavailable, flag the field as unsuitable for that particular automated decision.

This is a good place for an analyst-assisted pilot. Have an experienced operator label a small evaluation set, then compare the tool's retrieved candidates against those labels. Record false matches and missing relevant items, not just impressive examples. You are testing whether the workflow can support your categories, not proving that a vendor is universally best.

A Niche Scraper alternative chosen for marketplace analysis should remain accountable to marketplace-specific evidence. It may be useful even if it does not replace an existing supplier-monitoring collector. Two clearly separated components are often easier to reason about than one suite whose output fields hide several incompatible assumptions.

Combine first-party signals with a collector when you need control

You may not need a single replacement application. A research workspace can combine a relative-interest signal with authorized collection from sources you select. This route is appropriate when you need explicit provenance, custom fields, or a repeatable history under your own schema.

Google Trends provides relative, normalized search-interest information. It is not an absolute sales counter, and values depend on the comparison context. Use it to investigate patterns rather than convert a displayed score directly into expected orders. Google's explanation of Trends data describes that interpretation boundary.

For the collection component, prefer an official API or permitted export when it supplies the required data. Otherwise, establish that your proposed collection and downstream use are authorized before implementing a bounded collector. A browser-visible page is not a blanket license to copy its content or republish its images.

Choose the simplest extraction method that works for the source. Static structured information may not require a browser. An interactive page may need a controlled rendered-page workflow. Our JavaScript web scraping guide provides a separate technical starting point; the business question should determine what that collector retrieves.

Ownership includes maintenance. Save source timestamps, distinguish empty results from failed runs, and assign someone to investigate schema changes. If no one can own those tasks, a managed research workflow may be more practical even when it offers fewer custom fields. Flexibility is useful only when the team can sustain it.

Preserve evidence in a schema your team understands

A durable research record separates product identity from individual observations. The same product can have several supplier offers, several marketplace listings, and multiple research scores. Treating those as one row with a single price destroys the distinctions you need later.

Record group

Example fields

Why it belongs separately

Identity

Internal product ID, variant, manufacturer identifier

Supports matching across sources

Observation

Source URL, observed time, displayed amount, currency

Preserves what was actually seen

Interpretation

Metric definition, estimate flag, review notes

Prevents inferred demand becoming a fact

Decision

Reviewer, status, reason, next check

Makes the research actionable and auditable

Keep the original displayed value alongside a normalized value when transformation is necessary. A price parser should not silently discard currency, unit quantity, or shipping context. Preserve null for missing evidence rather than converting it to zero. An unknown shipping charge is not free shipping.

Use explicit states such as candidate, needs review, rejected, and approved for further testing. Approval should describe the next permitted step, not imply guaranteed commercial success. A candidate approved for supplier sampling is not automatically approved for a large inventory purchase.

For recurring collection, retain a run identifier and an explanation for missing observations. A product can disappear because the listing ended, the page changed, or the collector failed. Those events have different consequences. The operational principles in automated web scraping help keep that distinction visible after the pilot becomes a scheduled job.

Run a bounded comparison before migrating

Give each shortlisted route the same research question and the same review criteria. Choose a small, varied sample that includes ordinary products, ambiguous variants, and at least one candidate your team expects to reject. This is an evaluation design, not a claim about any tool's measured performance.

Record whether each route supplies the mandatory fields, how long review takes, and which uncertainties remain. Count usable, reviewed records rather than raw result volume. A large export that requires extensive identity repair may be less useful than a smaller, well-understood shortlist.

Include the human handoff. Ask a teammate who did not run the search to explain why a candidate was retained. If the evidence cannot support that explanation, improve the record format or reject the workflow. Research that lives only in the operator's memory will not scale cleanly.

Calculate total operational cost from subscription, integration work, review time, and ongoing maintenance. Use your own measured pilot time and current vendor terms. Do not treat an advertised monthly price as the total cost of a production process, and do not extrapolate a short trial into a revenue forecast.

Test one correction as part of that handoff. Give the second reviewer a candidate whose package quantity was initially misunderstood. Ask them to amend the interpretation without deleting the original observation. The resulting record should show what changed, why it changed, and which downstream comparison needs to be recomputed. This small exercise exposes whether the workflow supports review or merely stores final-looking values.

Also test an interrupted collection or unavailable export. Your team should know whether to retry, continue with the previous snapshot, or pause the research decision. Make the fallback visible to the analyst. Silently displaying old values with a fresh dashboard timestamp creates confidence the evidence does not justify.

Finally, separate adoption from expansion. A successful pilot for one category does not establish coverage for every category or destination. Add new scopes deliberately, with matching examples and a review owner. Keep the initial acceptance criteria alongside later changes so the meaning of success does not drift each time someone adds a source.

Finish with a decision memo: selected route, scope, known limitations, review owner, and exit plan. A Niche Scraper alternative is successful when it improves a defined research task while keeping uncertainty visible. It does not need to replace every tool your team already uses.

Key Takeaways

  • Choose the research job first: curated discovery, integrated operations, marketplace analysis, or a custom evidence pipeline.
  • Separate observed values, vendor estimates, and your own decisions in the data model.
  • Verify product variants, currency, destination, and observation time before comparing offers.
  • Test actual handoff and export behavior with your own sample; do not infer API access from a dashboard.
  • Budget for review and maintenance, not just the subscription.

FAQ

Should archived research records retain a rejected candidate?

Yes, when retention is permitted and the rejection reason remains useful. A minimal record can prevent the team from repeatedly investigating the same unsuitable product. Keep the reason and relevant timestamps, apply your retention policy, and avoid retaining unnecessary personal data or copied creative assets simply because they appeared during research.

Can one researcher approve their own data correction?

For low-impact corrections, that may be reasonable. For changes that affect purchasing or automated selection, a second review provides a clearer control. Record the original value, corrected value, reason, and reviewer so an apparent improvement can be traced without rewriting the underlying observation history.

Should a research dashboard sort unknown values last?

Usually, but display that choice explicitly. An unknown value should not be visually indistinguishable from a poor measured result. Separate incomplete candidates into a review queue when the missing field is essential. That avoids quietly excluding potentially relevant products merely because a source did not expose the same information.

Conclusion

The right replacement starts with a question your current process cannot answer reliably. Curated discovery can help an analyst build a shortlist. An integrated suite can reduce handoffs. Marketplace-oriented research can sharpen category comparisons. A custom pipeline can preserve the exact evidence and history your application requires.

None of those routes removes the need to understand what a metric represents. Keep product identity, source observations, estimates, and decisions separate. Test ambiguous cases as deliberately as straightforward ones, and make the exit path part of the trial rather than an afterthought.

If your chosen workflow needs an API-based retrieval component for authorized sources, evaluate WebScrapingAPI's Scraper API alongside your parsing and validation requirements. Keep the collector's responsibility narrow: retrieve the evidence your process needs, while your team remains responsible for interpreting it and deciding what happens next.

About the Author

Mihnea-Octavian Manolache, Full Stack Developer @ WebScrapingAPI

Mihnea-Octavian Manolache

Full Stack Developer

Mihnea-Octavian Manolache is a Full Stack and DevOps Engineer at WebScrapingAPI, building product features and maintaining the infrastructure that keeps the platform running smoothly.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.