Skip to content
Start free

Blog

Insights & Engineering

Deep dives into web data infrastructure, extraction techniques, and the future of structured data at scale.

Latest Articles

155 articles

Web Scraping with PHP in 2026: Libraries and Real Code
Guides

Web Scraping with PHP in 2026: Libraries and Real Code

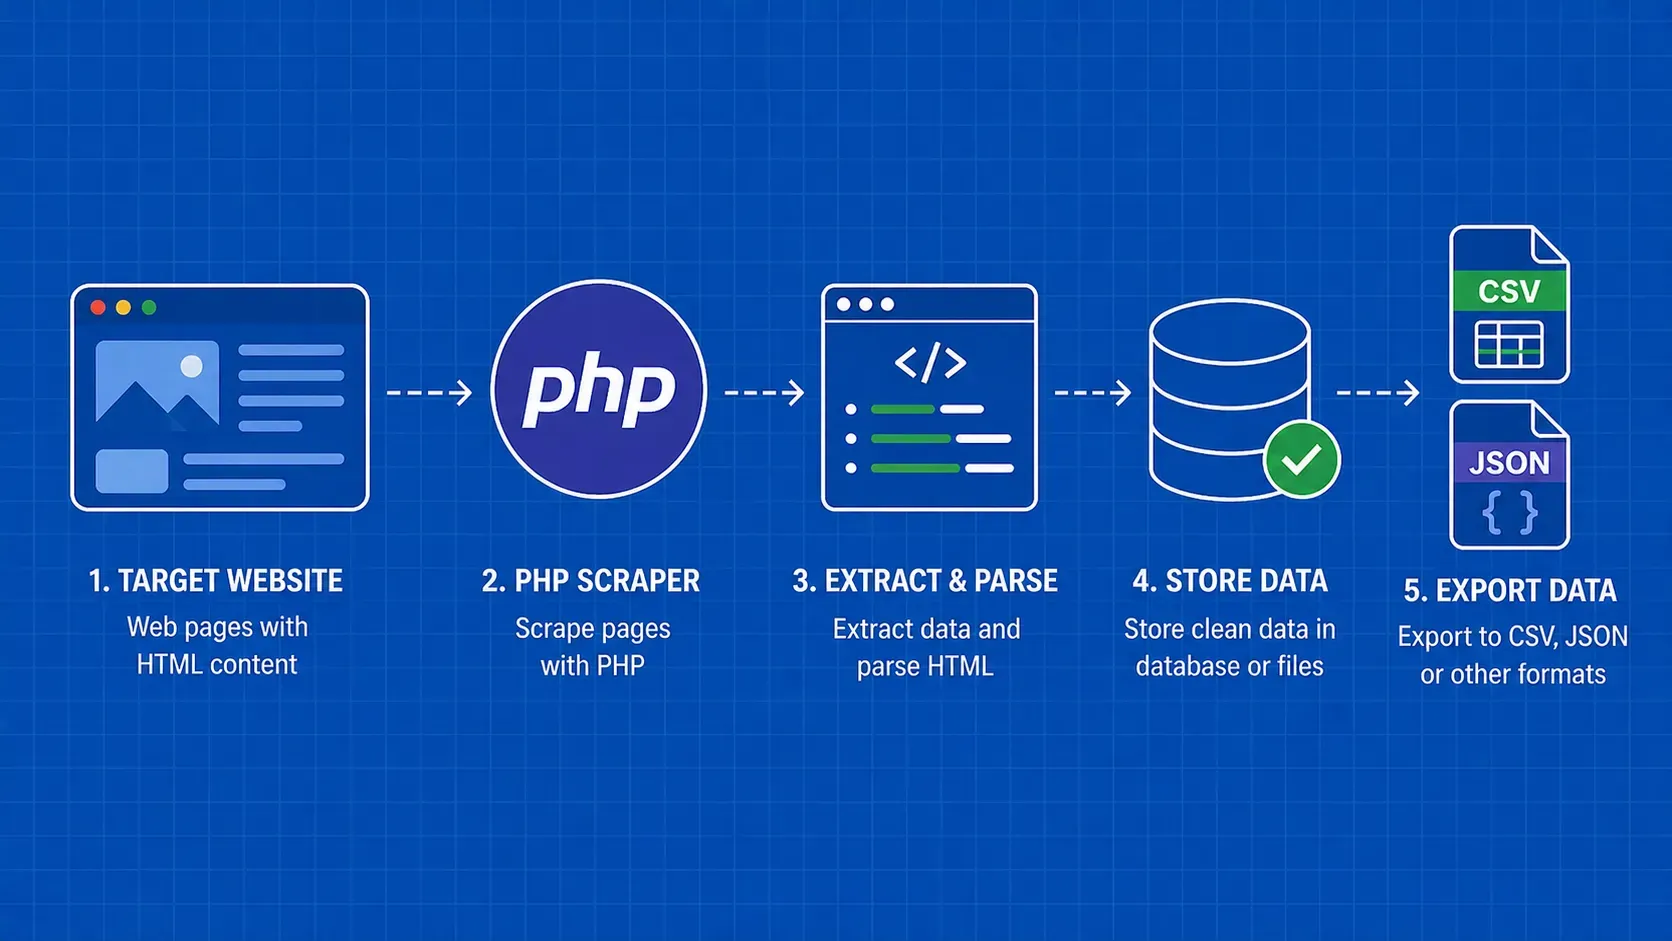
TL;DR: PHP is a perfectly capable language for web scraping, thanks to built-in extensions like cURL and DOMDocument, plus a rich Composer ecosystem that includes Guzzle, Symfony DomCrawler, and Symfony Panther for headless browsing. This guide walks you through the full workflow: fetching pages, parsing HTML, storing results in CSV/JSON/MySQL, handling errors, and avoiding blocks.

Sorin-Gabriel Marica16 min read
Read Article
Rotating Proxies: How IP Rotation Works for Web Scraping
Science of Web Scraping

Rotating Proxies: How IP Rotation Works for Web Scraping

TL;DR: So what are rotating proxies, in one line? Proxy servers that assign a different IP to each request from a managed pool, which is how scrapers slip past per-IP rate limits, CAPTCHAs, and geo-filters. This guide covers how rotation works, the four pool types, setup code in three languages, and how to pick a provider.

Raluca Penciuc10 min read
Read Article
XPath Cheat Sheet for Web Scraping: Syntax, Axes, Code
Guides

XPath Cheat Sheet for Web Scraping: Syntax, Axes, Code

TL;DR: This XPath cheat sheet covers the syntax, predicates, axes, and functions you actually need for web scraping, plus a CSS-to-XPath translation table and runnable Puppeteer and Scrapy examples. Use it as a desk reference next time a CSS selector quietly breaks on a site you depend on.

Mihai Maxim13 min read
Read Article
How to Build a Python Web Crawler: From Start to Scale
Science of Web Scraping

How to Build a Python Web Crawler: From Start to Scale

TL;DR: A python web crawler automates the tedious work of following links across a website to discover and collect content. This guide walks you through building one from scratch with requests and BeautifulSoup, then graduating to Scrapy for concurrent crawling, item pipelines, and structured data exports. You will also learn how to crawl responsibly, rotate proxies to avoid blocks, and handle JavaScript-rendered pages.

Suciu Dan27 min read
Read Article
Premium Proxy List 2026: 9 Paid Proxy Services Ranked
Science of Web Scraping

Premium Proxy List 2026: 9 Paid Proxy Services Ranked

TL;DR: For most scraping teams, Oxylabs and Decodo are the strongest all-round premium proxy services, Bright Data suits enterprise budgets, and Webshare is the cheapest way to start with a static list. Choose a static list when you want IPs that stay yours for the rental period, and a rotating gateway when every request or session should leave through a different IP.

Gabriel Cioci22 min read
Read Article
How to Use cURL With Python in 2026
Guides

How to Use cURL With Python in 2026

TL;DR: There are three sensible ways to use cURL with Python: shell out to the curl binary with subprocess, bind to libcurl through PycURL, or skip curl entirely and use the Requests library. Knowing how to use cURL with Python well means knowing all three. This guide gives you runnable examples for all three, a curl-flag-to-Python translation table, and a decision matrix so you can pick the right tool the first time.

Andrei Ogiolan13 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.