Web Scraping vs Web Crawling: A Beginner's Guide
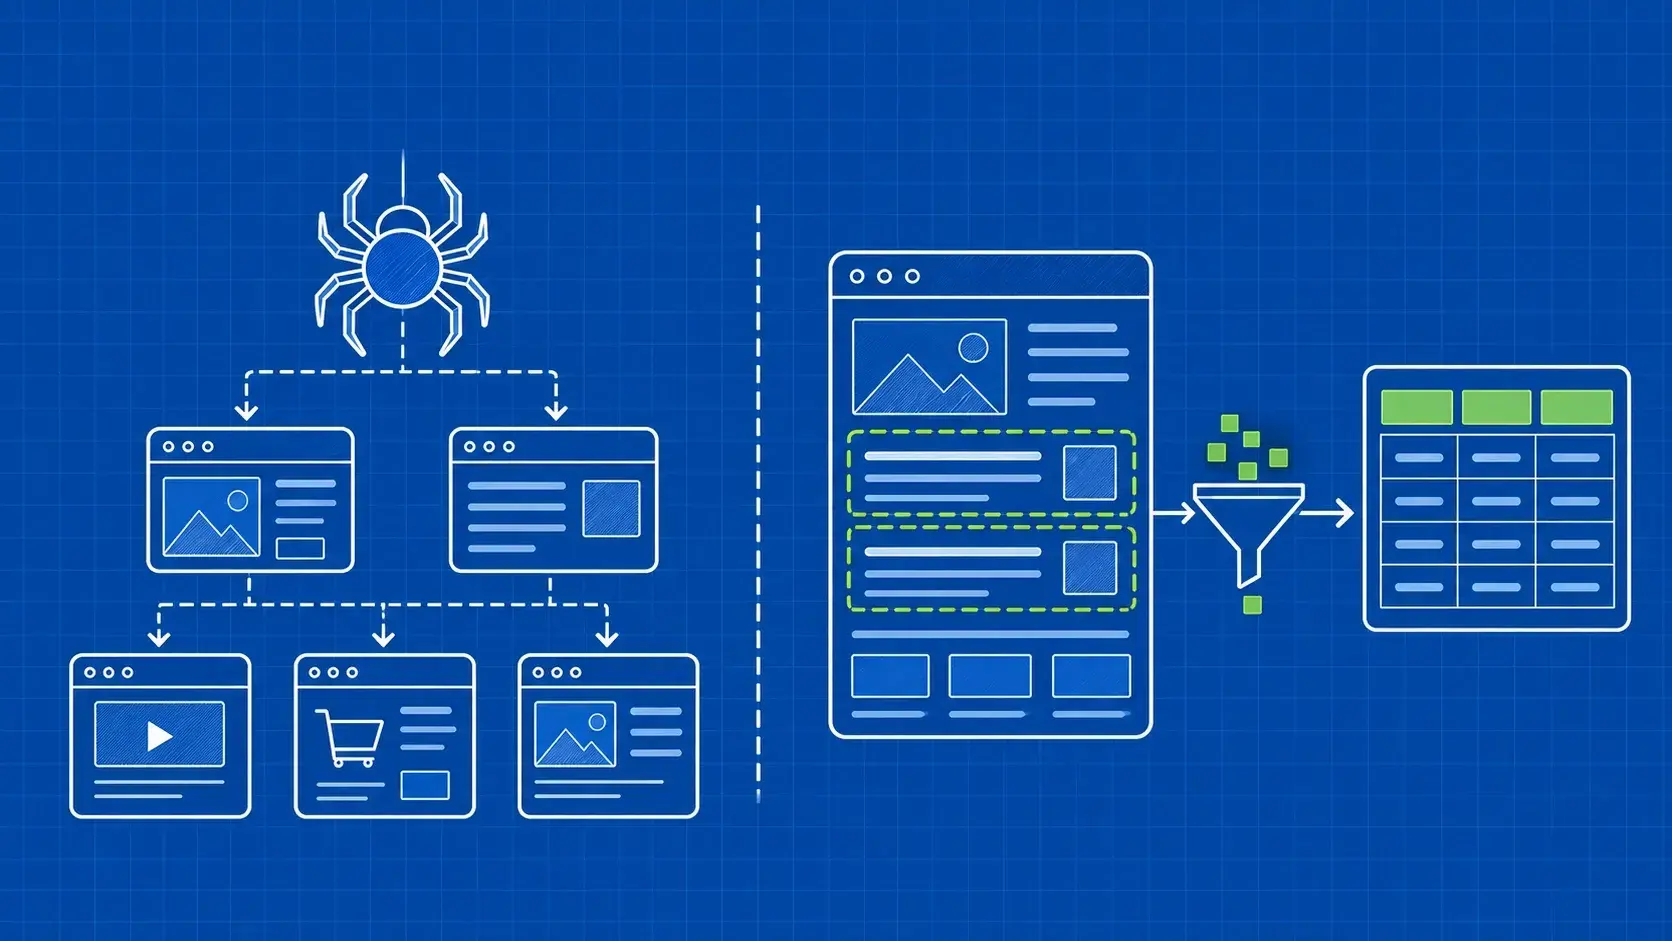
TL;DR: Learn how crawlers find pages and scrapers extract useful data. Follow a bookstore example, compare their outputs, and choose the right workflow for your first project.
Blog
Deep dives into web data infrastructure, extraction techniques, and the future of structured data at scale.
155 articles

TL;DR: Learn how crawlers find pages and scrapers extract useful data. Follow a bookstore example, compare their outputs, and choose the right workflow for your first project.

TL;DR: Decodo is the best all-round mobile proxy for most scraping teams, Oxylabs suits precise carrier and ASN targeting at volume, and SOAX gives the most rotation control. Buy rotating mobile proxies, billed per GB, when each request should come from a different carrier IP; buy a dedicated mobile IP when you need one stable identity. Most public pages scrape fine on cheaper proxy types.

TL;DR: Web scraping best practices are the habits that keep a scraper legal, polite, accurate, and cheap to run. Write a data contract, prefer APIs or JSON over HTML, follow robots.txt as RFC 9309 defines it, pace each host, honor Retry-After, and validate every record before saving it. This playbook applies them to each stage of a scraper's lifecycle, with working Python snippets.

TL;DR: Build an authorized SEO audit that separates observed page evidence from search-engine outcomes. Compare rendering, canonical signals, directives, and template defects.

TL;DR: Design APIs that collectors can consume reliably. Define pagination, retries, validators, authentication, schema evolution, and recovery as explicit contracts.

TL;DR: Is there an easy and fast way to extract data from Airbnb? Yes, and this is where web scrapers come into play. Let us show you how, using WebScrapingAPI.
Start Building
Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.