Skip to content
Start free

Blog

Insights & Engineering

Deep dives into web data infrastructure, extraction techniques, and the future of structured data at scale.

Latest Articles

155 articles

What Are ISP Proxies? Static Residential IPs Explained
Science of Web Scraping

What Are ISP Proxies? Static Residential IPs Explained

TL;DR: What are ISP proxies? They are static residential IPs hosted in a datacenter. Detection systems see a residential ASN; you get datacenter throughput. They are the right pick when sessions, account binding, and predictable per-IP pricing matter more than raw geographic reach.

Mihnea-Octavian Manolache9 min read
Read Article
How to Bypass Cloudflare in 2026: Tools, Code & Tactics
Guides

How to Bypass Cloudflare in 2026: Tools, Code & Tactics

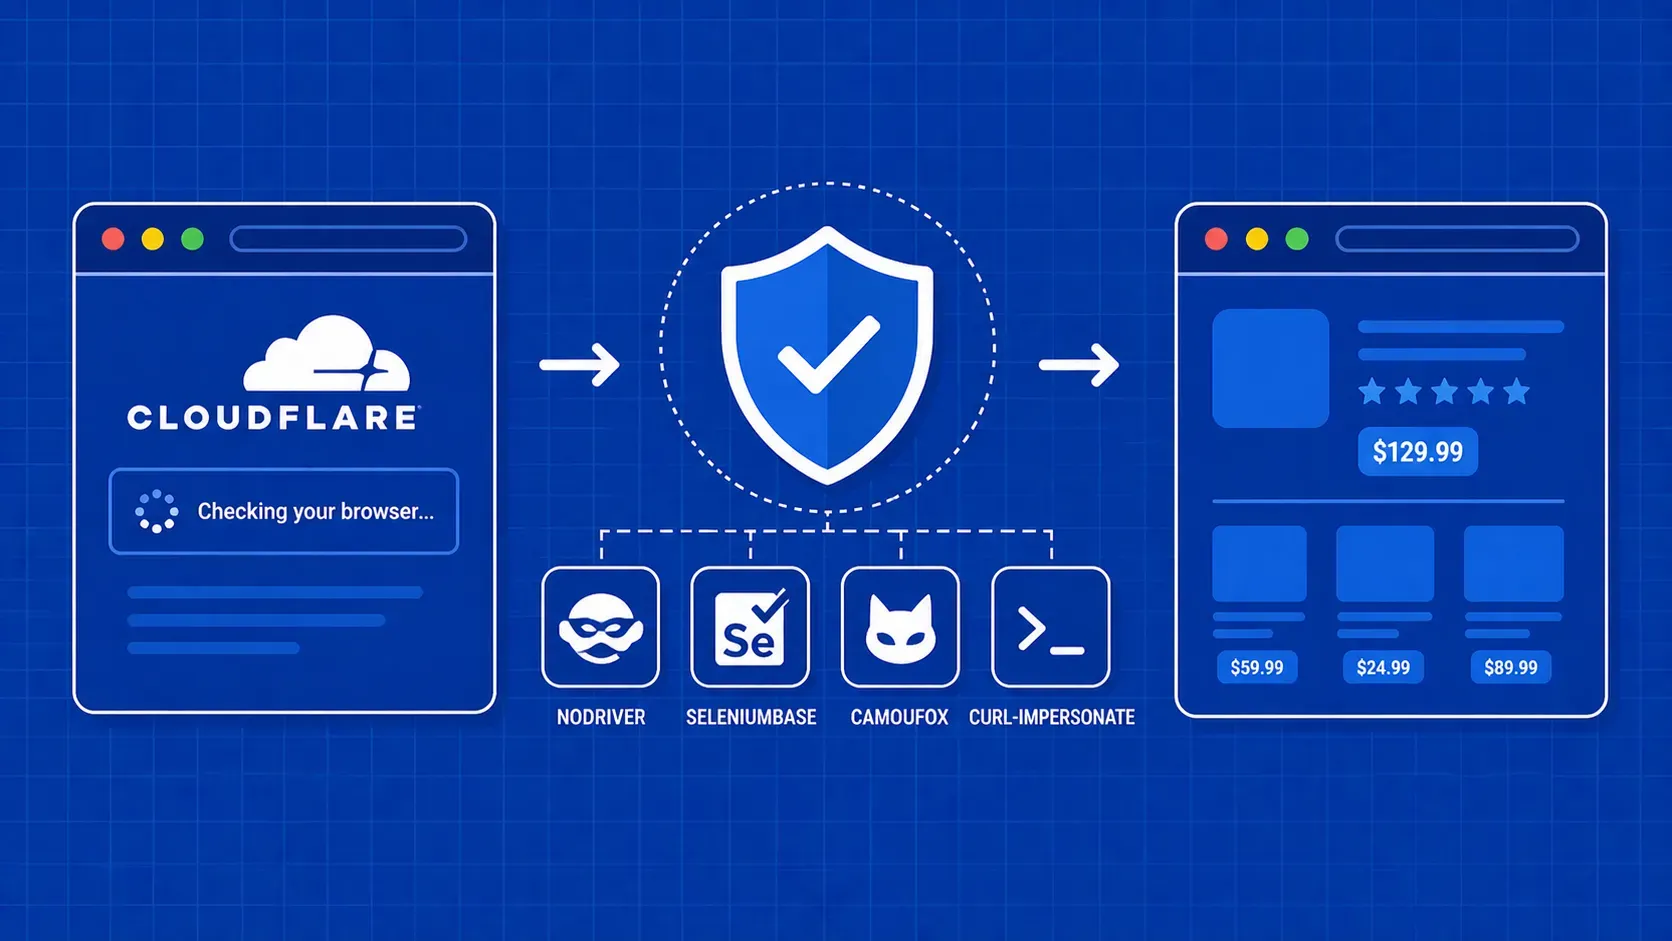
TL;DR: Cloudflare blocks scrapers by layering TLS fingerprinting, JavaScript challenges, behavioral analysis, and Turnstile CAPTCHAs into a composite trust score. To bypass Cloudflare reliably, you need to match every layer simultaneously. This guide covers the detection stack, compares four practical tools (Nodriver, SeleniumBase UC, Camoufox, curl-impersonate), and walks through proxy strategies, session persistence, error troubleshooting, and production scaling.

Mihnea-Octavian Manolache13 min read
Read Article
Start Using Web Stealth Proxy like a Pro: Quick Start Guide
Guides

Start Using Web Stealth Proxy like a Pro: Quick Start Guide

TL;DR: Discover how to use Web Stealth Proxy like a pro with our quick start guide. Get step-by-step instructions to boost your proxy game and take your online privacy to the next level. Start today!

Mihai Maxim5 min read
Read Article
Web Scraping YouTube with Python: Videos, Comments, Data
Guides

Web Scraping YouTube with Python: Videos, Comments, Data

TL;DR: This is a 2026 playbook for how to scrape YouTube with Python. You'll pick the right method (Data API v3, yt-dlp, hidden /youtubei/v1/ endpoints, or a managed scraper) using a decision matrix, then run code for video metadata, comments, channels, search, Shorts, and transcripts, with a production section on proxies, headers, and 429 backoff so you don't get blocked.

Raluca Penciuc17 min read
Read Article
Python Headless Browser Libraries For Web Scraping in 2026
Guides

Python Headless Browser Libraries For Web Scraping in 2026

TL;DR: A Python headless browser lets you render JavaScript, click through SPAs, and scrape sites that plain HTTP clients can't reach. Selenium is the safest default, Playwright is the modern pick for new code, Pyppeteer and Splash still have niche uses, and a hosted browser API is what you reach for when anti-bot defenses or scale start to bite.

Mihnea-Octavian Manolache18 min read
Read Article
HTTP Headers Web Scraping: Stop Getting Blocked
Science of Web Scraping

HTTP Headers Web Scraping: Stop Getting Blocked

TL;DR: HTTP headers are usually why your scraper gets a 403 while your browser loads the same URL fine. This guide shows which headers anti-bot systems actually inspect, how to capture a real browser's header set from DevTools, how to send and rotate them correctly in Python and Node.js, and when manual tuning stops paying off and a managed scraping API is the better move.

Raluca Penciuc12 min read
Read Article

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.