Skip to content
Start free
Back to Blog

Web Scraping Sitemaps to Discover URLs

Robert MunceanuLast updated on 12 min read
Web Scraping Sitemaps to Discover URLs
TL;DR: A sitemap is a discovery input, not a complete dataset or permission to fetch every listed URL. Distinguish URL sets from indexes, parse namespaces deliberately, treat freshness metadata as a source claim, and enforce retrieval boundaries before adding targets to a collection queue.

A product category shows twenty links, but its sitemap lists thousands of product addresses. Web scraping sitemaps can help you discover that larger candidate set without navigating every menu. The important distinction is that a sitemap supplies locations and limited metadata; it does not supply the product records themselves or guarantee that every listed page is available.

Link following fills gaps when a sitemap is missing or incomplete, which our guide to web crawling with Python works through.

Sitemap-based discovery also changes the trust boundary. XML files and the URLs inside them are external input. A parser may recognize a document successfully while the resulting address is outside your collection scope. An index can point to many documents, and compressed files can expand far beyond their transferred size.

This guide separates discovery, validation, and collection. You will inspect the two main XML shapes, run a local Python fixture, define traversal limits, and decide how to use lastmod without treating it as proof of change. The exercise uses fictional documents held in memory and makes no network requests. Apply the same reasoning to an approved site before adding its discovered pages to a real fetch queue.
Use web scraping sitemaps as a discovery input

Begin with the collection objective. If you need product details, a list of page URLs is an intermediate result. You still need to identify which addresses represent products, retrieve appropriate pages, extract fields, and validate the resulting records.

A sitemap may be declared by the site or supplied directly by its owner. A conventional filename is a useful candidate, not a promise that every site uses it. Treat discovery of the sitemap address and authorization to collect its contents as separate questions.

For web scraping sitemaps, keep a queue of candidates rather than immediately fetching every location. Store where each URL was discovered and which rule admitted it to the page queue. This makes a broad index or an unexpected document easier to investigate later.

Layer

Input

Useful output

Sitemap discovery

Approved site and known sitemap locations

Sitemap-document work list

XML interpretation

Bounded sitemap content

Classified child sitemap or page locations

Scope validation

Parsed candidate URLs

Allowed targets and rejected-target reasons

Page collection

Approved page queue

Retrieved representations

Record extraction

Page content and field rules

Validated business records

Do not confuse publication intent with completeness. A site can omit pages, publish stale entries, or maintain several sitemap collections for different content. Your discovery report should describe what the inspected documents contained, not assert that no other pages exist.

Also separate a failed fetch from a removed page. A temporary gateway error during discovery says nothing conclusive about whether the listed content still exists. The proxy status diagnosis guide explains why response categories need evidence before they become conclusions about the source.

Keep the initial scope small enough to inspect manually. A single approved sitemap and a few representative page types can reveal whether this discovery method fits the task before a large traversal hides mismatches.

Distinguish URL sets, indexes, and extension data

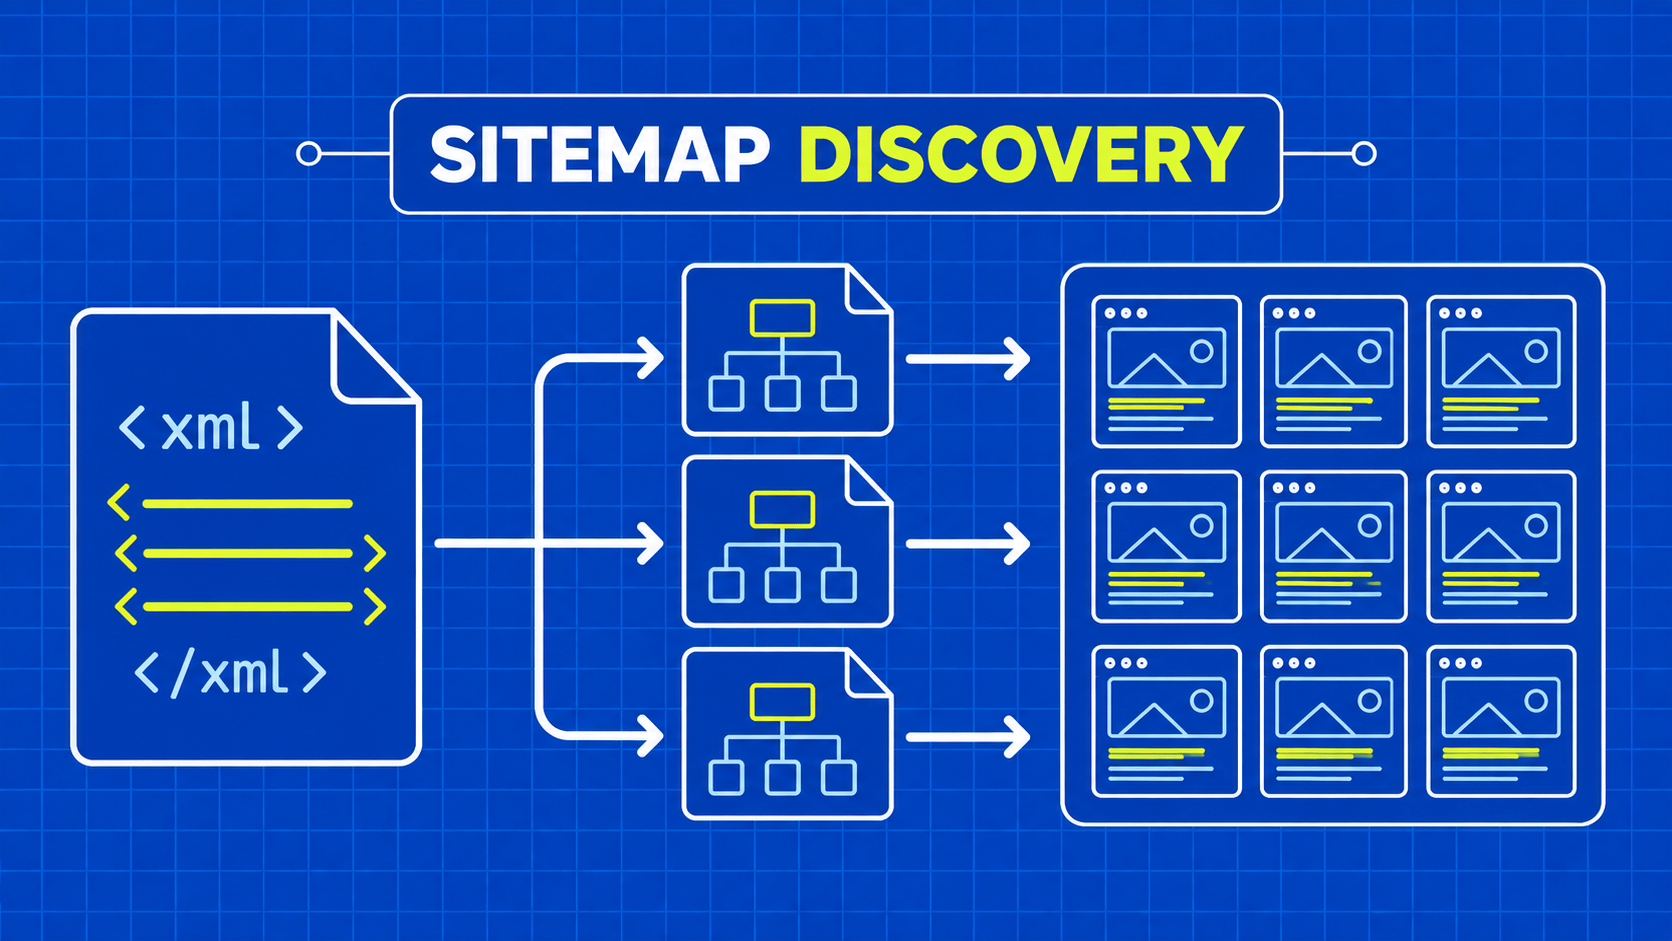
The XML root tells you what the document contains. A urlset contains page entries; a sitemapindex contains entries pointing to sitemap documents. Both use the Sitemaps namespace, and their required loc elements have different jobs. The Sitemaps protocol defines those structures.

Document or element

Meaning for the collector

Treatment

urlset containing url/loc

Page candidates

Validate and add to page discovery output

sitemapindex containing sitemap/loc

Sitemap document candidates

Validate and add to sitemap traversal

Page-entry lastmod

Publisher's page modification value

Preserve as metadata with its source

Index-entry lastmod

Publisher's sitemap modification value

Keep separate from page freshness

Extension namespace elements

Additional domain-specific metadata

Interpret only under an explicit extension contract

XML namespaces matter even when the visible tag looks simple. With a default namespace, an XML parser identifies the element using the namespace URI and local name together. Searching for bare url elements can therefore return nothing from an otherwise valid sitemap.

When web scraping sitemaps, select the specific structural path you need. A broad search for every element named loc can mix page locations with sitemap references or extension metadata. Distinguish the main namespace from image, video, news, or other extensions rather than stripping every namespace indiscriminately.

Let the XML parser handle entity escaping. A URL containing a query separator can appear with & in XML and yield & in parsed text. Do not replace arbitrary strings before parsing or repeatedly decode URLs until they look convenient.

Preserve the original discovered address alongside any normalization you apply. Normalization should implement known identity rules, not guess that different paths or query strings are equivalent. A URL list becomes useful input only when its interpretation remains consistent with the source contract and your collection scope.

Parse a local namespace-aware sitemap fixture

Save this exercise as sitemap_fixture.py and run it with Python 3. It uses only the standard library, parses fixed in-memory Unicode strings, and performs no network retrieval. The fixture classifies one index and one URL set, then checks that an unrelated host is rejected.

from urllib.parse import urlsplit
from xml.etree import ElementTree as ET

NS = "http://www.sitemaps.org/schemas/sitemap/0.9"
INDEX = f'''<sitemapindex xmlns="{NS}">
  <sitemap><loc>https://catalog.example/products.xml</loc></sitemap>
</sitemapindex>'''
URLS = f'''<urlset xmlns="{NS}">
  <url><loc>https://catalog.example/products/lamp</loc>
    <lastmod>2026-09-01</lastmod></url>
  <url><loc>https://catalog.example/products/book?lang=en&amp;view=full</loc></url>
</urlset>'''

def allowed_url(value):
    if not value or any(ord(char) <= 32 for char in value):
        raise ValueError("missing URL or control/space character")
    parts = urlsplit(value)
    if (parts.scheme != "https" or parts.netloc != "catalog.example"
            or parts.fragment):
        raise ValueError("URL outside fixture scope")
    return value

def parse_fixture(text):
    if len(text.encode("utf-8")) > 10_000:
        raise ValueError("fixture byte budget exceeded")
    upper = text.upper()
    if "<!DOCTYPE" in upper or "<!ENTITY" in upper:
        raise ValueError("declarations not accepted in this fixture")
    root = ET.fromstring(text)
    shapes = {
        f"{{{NS}}}urlset": ("pages", "url"),
        f"{{{NS}}}sitemapindex": ("sitemaps", "sitemap"),
    }
    if root.tag not in shapes:
        raise ValueError("unsupported root or namespace")
    kind, child = shapes[root.tag]
    entries = root.findall(f"{{{NS}}}{child}")
    if len(entries) > 10:
        raise ValueError("fixture entry budget exceeded")
    result = []
    for entry in entries:
        locations = entry.findall(f"{{{NS}}}loc")
        if len(locations) != 1:
            raise ValueError("expected exactly one location")
        location = allowed_url((locations[0].text or "").strip())
        modified = entry.findtext(f"{{{NS}}}lastmod")
        result = [*result, {"url": location, "lastmod_raw": modified}]
    return kind, result

kind, children = parse_fixture(INDEX)
assert kind == "sitemaps" and len(children) == 1
documents = {"https://catalog.example/products.xml": URLS}
kind, pages = parse_fixture(documents[children[0]["url"]])
assert kind == "pages" and len(pages) == 2
assert pages[0]["lastmod_raw"] == "2026-09-01"
assert pages[1]["url"].endswith("?lang=en&view=full")
for invalid in [
    URLS.replace("catalog.example", "other.example"),
    '<!DOCTYPE urlset><urlset/>',
    '<urlset><url><loc>https://catalog.example/x</loc></url></urlset>',
]:
    try:
        parse_fixture(invalid)
    except ValueError:
        pass
    else:
        raise AssertionError("invalid fixture accepted")
print("index classified; 2 page URLs parsed; rejection checks passed")

The fixture deliberately permits one exact HTTPS authority. It does not follow redirects, resolve DNS, decompress data, or claim that string-level URL checks prevent server-side request forgery. Those controls belong to a production retrieval layer.

The declaration check is also limited to the fixture's already-decoded strings. It is not a general XML firewall for arbitrary remote encodings. Use an appropriately configured parser and retrieval limits for untrusted input rather than copying this check as a complete defense.

Notice how lastmod is retained as raw source metadata. The exercise does not convert it into a proof that the page changed or a scheduling command. The second page has no modification value, which is different from a known old timestamp.

This small test covers the interpretation boundary in web scraping sitemaps: root classification, namespace-aware paths, entity decoding, one allowed host, and rejected malformed structure. Keep those tests when adding transport, then add separate tests for the transport's redirect, size, and destination rules.

Traverse indexes with budgets and a visited set

Use separate queues for sitemap documents and page candidates. Start the document queue with the approved index, fetch and classify a bounded document, then place its child sitemap locations or page locations in the appropriate destination. Do not enqueue a page as another sitemap simply because both contain URLs.

Maintain a visited set for document locations so repeated references do not cause repeated work indefinitely. If a provider publishes unexpected index nesting, define whether your collector rejects it or supports a bounded traversal. Do not assume that arbitrary nesting is a portable protocol guarantee.

Protocol limits and operational budgets are different. A standard sitemap permits at most 50,000 URLs and 50 MB, specifically 52,428,800 bytes, when uncompressed. Sitemap indexes also have entry and size limits. Compression reduces transfer size without removing the uncompressed limit. Your job may need lower limits to fit its memory, time, and approved scope.

For web scraping sitemaps at scale, bound transferred bytes, decompressed bytes, documents, entries, elapsed time, and traversal depth where applicable. A small compressed response can still produce a large body after expansion. Enforce bounds while reading and decompressing, not only after allocating the complete expanded document.

Record rejected and skipped references. “Already visited” is different from “host not allowed,” “document too large,” or “XML could not be parsed.” Those categories explain why the discovered page count differs from the number of entries initially encountered.

Checkpoint after durable output has been recorded. If discovery results are stored separately from traversal state, design restart behavior that can safely replay a document. Deduplication should prevent duplicate queue entries without concealing changes to metadata that matter to the job.

Finally, keep the document's retrieval time and final approved location. A redirect or changed document can otherwise make two runs look identical when they actually inspected different inputs.

Treat lastmod and other metadata as source claims

The page-level lastmod field represents the publisher's stated last modification of that page. It is not supposed to mean the time the sitemap generator ran. An index-level modification value refers to the sitemap document instead. Mixing those meanings can trigger unnecessary page refreshes or skip relevant ones.

For web scraping sitemaps, preserve the raw value and parse it only under an explicit date policy. A date without a time is less precise than a timestamp. A missing or malformed value should remain unknown, not become today's date or a default that implies certainty.

Treat the value as a prioritization hint until the source has demonstrated useful accuracy for your task. Compare a sample of advertised changes with actual page observations. A trustworthy timestamp for editorial content may still be too coarse for frequently changing stock values.

Google's sitemap guidance explains its use of accurate lastmod values and says that it ignores priority and changefreq. That describes Google's behavior, not a requirement that your collector copy its scheduling policy. Do not turn optional publisher metadata into a universal fetch instruction.

HTTP validation is separate again. A server's entity tag or last-modified response header can participate in conditional retrieval under HTTP rules. A sitemap date does not replace those validators or guarantee a 304 response. RFC 9111 defines cache freshness and validation behavior.

For the collection report, retain source modification metadata, discovery time, and page observation time separately. They answer when the publisher claims a change, when you found the address, and when you observed the actual representation.

Use that distinction when scheduling. Prioritizing recently advertised changes can improve the order of work while periodic reconciliation covers missing or unreliable dates. Document that policy so consumers understand what “recently refreshed” really means.

Constrain retrieval before trusting discovered URLs

XML parsing and URL parsing do not grant permission to make a network request. A location can point outside the approved site, contain credentials, use an unexpected scheme, or reach an address that should not be accessible from the collector. Treat every discovered location as untrusted input to a separate admission check.

Python's URL parsing documentation explicitly warns that parsing functions do not validate inputs. A successful split into scheme and hostname is therefore not a security decision. Apply an explicit policy for schemes, hosts, ports, user information, and scope.

Server-side request forgery becomes relevant when an automated service fetches destinations influenced by external input. Keep destination controls at the actual network boundary, including redirects and resolved addresses. A hostname allowlist alone does not address every DNS or redirect scenario, and validating one hop does not authorize the next.

When web scraping sitemaps, avoid forwarding credentials from the original request to a newly discovered host. Some publishers use supported cross-site hosting arrangements, but your collector should enable only arrangements it has explicitly approved. An external reference is not an instruction to expand collection scope automatically.

Untrusted XML adds another boundary. Entity expansion, external resource access, and large-token behavior depend on the parser and its configuration. The Python XML security documentation summarizes risks and notes the importance of the underlying parser version. Do not assume that all XML libraries share the same defaults.

Use current, appropriate parser defenses together with size and execution budgets. Reject unsupported document features rather than enabling external entity resolution to make one file parse. Keep a malformed sitemap classified as a discovery failure, with a sanitized diagnostic that helps the source owner investigate.

These controls are complementary. Namespace-aware parsing prevents structural confusion; URL policy controls destinations; network enforcement checks the connection; and resource budgets constrain work. None can safely stand in for all the others.

Measure discovery coverage before scraping pages

At the end of traversal, report what was inspected and why work stopped. Include document counts, accepted page candidates, duplicates, rejected destinations, parse failures, and budget stops. A large URL count alone does not demonstrate complete or correct discovery.

Sample the admitted URLs against your target schema. Product, category, search, and editorial pages can coexist in one sitemap set. Define a routing rule for each relevant type and keep unrelated types out of the extraction queue rather than allowing their missing fields to pollute record-validation metrics.

Web scraping sitemaps solves address discovery, not page rendering. If the selected pages expose data only after browser execution, the screen scraping guide explains how to choose a readiness condition and extract rendered fields. Do not assume a sitemap guarantees static HTML content.

Preserve provenance through that handoff. A page record should retain the discovered URL, sitemap source, observation time, and extraction version where relevant. Redirected or canonicalized addresses need an explicit identity policy rather than an undocumented replacement.

The automated collection workflow guide connects discovery to durable processing, retries, and delivery. Keep those stages observable so a retrieval outage does not make the sitemap parser appear to have returned fewer entries.

Before scaling, test one duplicate document reference, one rejected URL, one malformed XML file, and one exhausted budget. The useful result is not merely that the script stops. It should stop with a classification that explains which part of the intended discovery scope remains unresolved.

Key Takeaways

  • Use web scraping sitemaps to build a candidate queue, then validate destinations and extract page records in separate stages.
  • Parse the root and namespace deliberately so sitemap references, page locations, and extension data are not mixed.
  • Enforce protocol-aware size checks alongside stricter operational budgets, including decompressed bytes and total traversal work.
  • Preserve lastmod as publisher metadata; distinguish it from discovery time, observation time, and HTTP validators.
  • Keep URL admission, network destination controls, XML defenses, and completeness reporting independently testable.

FAQ

Can a site have more than one sitemap index?

Yes. The protocol permits more than one sitemap index. For web scraping sitemaps, discover or receive the approved set rather than assume that finding a single index identifies every sitemap. Keep provenance for each starting document and define whether their results are combined into one collection scope or reported separately.

Should query parameters be removed from sitemap URLs?

Not automatically. Query parameters can identify language, content, or another meaningful variant. Remove them only under a verified identity rule for that source. Preserve the discovered URL so a later correction remains possible, and test that any normalization does not collapse distinct records or change the retrieved representation.

Do sitemap entries prove that a page is indexable?

No. A listed address is a discovery signal, not proof that a search engine can or will index it. Other page and access conditions still apply. For data collection, verify the actual response and required content rather than interpreting sitemap presence as a guarantee of availability or suitability.

Conclusion

Web scraping sitemaps works best when discovery remains a distinct, measurable stage. Classify the document, parse the right namespace, retain source metadata, and admit only targets that fit the collection policy. Then report both the discovered candidates and the reasons parts of the traversal remained incomplete.

Start with the local fixture and extend one boundary at a time. Add bounded retrieval before large files, destination enforcement before external references, and durable progress before a long-running traversal. Keep the test cases that show a clear failure when those boundaries are crossed.

When the approved page queue is ready, evaluate WebScrapingAPI's Scraper API for the retrieval stage. Retain your own discovery provenance and record checks so the resulting dataset explains both where its URLs came from and what was actually observed.

About the Author

Robert Munceanu, Full-Stack Developer @ WebScrapingAPI

Robert Munceanu

Full-Stack Developer

Robert Munceanu is a Full Stack Developer at WebScrapingAPI, contributing across the product and helping build reliable tools and features that support the platform.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.