Skip to content
Start free
Back to Blog

Alternative to import.io: Choose by Data Workflow

Ștefan RăcilăLast updated on 13 min read
Alternative to import.io: Choose by Data Workflow
TL;DR: The right alternative to import.io depends on who builds the extractor, who repairs it, and how validated data reaches its destination. Evaluate Octoparse for visual task building, Browse AI for extraction and monitoring workflows, Apify for hosted automation, and Scrapy for a developer-owned framework using the same sample workload.

A spreadsheet arrives on time, but half the prices are blank and several products appear twice. The extraction run reports success. Your analysts still cannot use the result. This is the problem a useful alternative to import.io evaluation should address: whether a replacement delivers data your team can trust, not simply whether it can select text from a page.

Import.io currently presents an enterprise web data extraction offering on its official site. Your existing arrangement may include more than an extraction interface, so inventory what you actually receive before comparing replacements. Configuration, recurring delivery, support, and maintenance responsibilities can matter as much as the visible rows in an export.

The tools below are concrete candidates for different operating models. They are not interchangeable, and their order is not a performance ranking. This guide uses current official documentation for feature descriptions and an original evaluation method for the recommendations. It does not assume a particular contract, quote prices, or promise that any tool can extract every website.

Open-source frameworks and managed APIs sit in the same landscape, sorted by job in our best web scraping tools roundup.

Start with a sample dataset and a clear definition of a usable record. Then compare the complete path from source page to downstream consumer, including the person who will fix the job when the page changes.
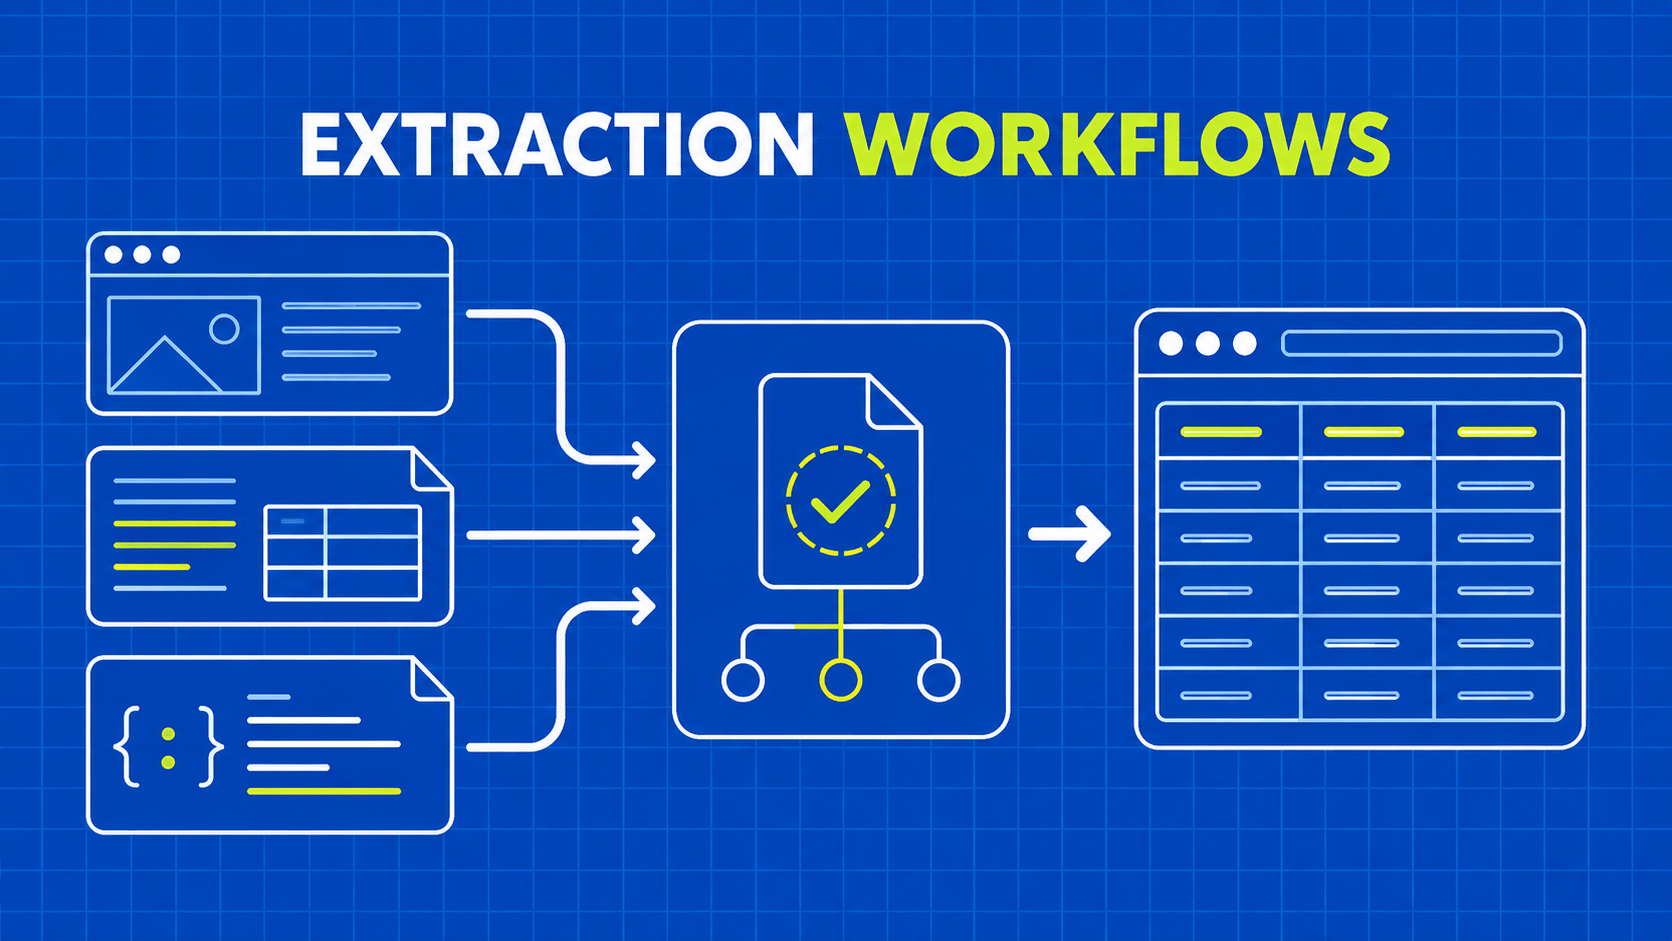
Choose an alternative to import.io by ownership

Before building a shortlist, answer three questions: who can change the extraction logic, who notices a bad delivery, and who repairs it? “The vendor” is not specific enough unless the scope of that responsibility is established. “The analyst” is not sustainable if the repair requires code that only an occasional contractor understands.

Candidate

Operating model to evaluate

Good first pilot

Responsibility to clarify

Octoparse

Visual extraction tasks with local or cloud execution

A catalog with list and detail pages

Who updates the task and manages exports

Browse AI

Trained extraction and monitoring workflows

A repeating list with a change-monitoring need

Who retrains workflows and reviews change alerts

Apify

Hosted Actors and automation

A maintained Actor or custom job with structured output

Who owns the Actor, version, and data validation

Scrapy

Python crawling and extraction framework

A developer-owned collector with explicit parsing rules

Your team owns deployment, scheduling, and repairs

The table describes starting points, not exclusive features or suitability guarantees. For each alternative to import.io, verify the current plan and product behavior before committing. A feature documented by a vendor may still have account, workflow, or edition requirements that matter to your specific project.

Distinguish a tool purchase from a data delivery agreement. With a tool, your team usually remains responsible for defining what the data means and confirming that it is correct. A managed arrangement may allocate some of that work differently, but you need explicit acceptance criteria either way. A file delivered every morning is not necessarily a complete, fresh, or correctly normalized dataset.

Write a short ownership statement before the pilot. For example: “An analyst maintains field selection; an engineer owns the import; the data owner approves schema changes.” If nobody can accept one of those responsibilities, solve that gap before selecting a product on interface preference.

Evaluate Octoparse for visual extraction tasks

Octoparse is worth testing when the people defining fields prefer a visual workflow and need to move extracted data into familiar destinations. Its current data export lesson distinguishes local execution from cloud execution and describes file, database, and cloud storage exports. Those are relevant capabilities for a team replacing an established delivery process.

Build the pilot around representative page structure. Include a list page, a detail page, an optional field, and pagination. Ask the future operator to explain how each output field maps to the source. If the result works but nobody understands why a selector captured a value, the task may be difficult to maintain when the layout changes.

When considering Octoparse as an alternative to import.io, run the task in the environment you intend to use. A local success does not establish cloud success. Authentication, available state, timing, and destination access should be tested in the final execution mode. Record whether the operator must keep a machine running and how they discover an unsuccessful or incomplete run.

Inspect exported files as carefully as the preview table. A column that looks numeric may contain currency symbols or mixed decimal conventions. A product with several variants may require multiple records rather than one concatenated cell. Decide those representations before wiring the export to a downstream spreadsheet or database.

The main fit question is whether visual task maintenance remains understandable for your workload. Do not assume that a visual interface eliminates technical decisions. It changes where those decisions are expressed. Have the intended maintainer repair a deliberately changed sample page and document the work needed; that is better evidence than a demonstration performed entirely by an expert operator.

Consider Browse AI for extraction and monitoring

Browse AI documents workflows for extracting structured data and monitoring changes. Its current robot-building guidance recommends Table Studio when data is already visible, Robot Studio when actions are needed, and the Chrome extension when those approaches cannot train the site. Follow that current routing instead of relying on an older extension-only tutorial.

This is a candidate when the result is a recurring observation: a list of listings, availability changes, or newly added items. In the pilot, separate extraction correctness from change detection. First verify the full record. Then change one controlled value and confirm that the monitoring workflow produces the notification or data update your consumer expects.

For this alternative to import.io, define the identity of an item early. If a listing changes position, it should not automatically become a new entity in your reporting. If the same item appears in two categories, decide whether that represents one product with two memberships or two separate observations. These are data modeling choices; a monitoring interface cannot decide them for you.

Also test list boundaries. Include a short list, an empty result, and a list requiring another page or scroll. A workflow that captures the first visible items may look convincing while missing the part that matters most to the business. Keep a manually checked expected sample so you can distinguish “no changes” from “nothing was collected.”

Evaluate who will review alerts after launch. An alert stream that nobody owns is not an operational improvement. The right fit is a workflow the intended operator can train, inspect, and repair, with output that your team can reconcile. Treat claims about ease as hypotheses for that operator to test, rather than universal properties of the product.

Use Apify when hosted automation fits your team

Apify's Actor documentation describes runnable programs that can be invoked through its console, API, command line, or schedules. This model is useful to evaluate when you want hosted execution and are comfortable treating extraction as a configurable job. You can assess an existing Actor or a custom implementation according to the same output contract.

An existing Actor can reduce the amount of initial implementation you need, but its input and output still require review. Confirm who maintains it, what inputs your use case requires, and whether the returned fields have the meaning your consumer expects. A field called “price” does not tell you whether it includes a discount, tax, shipping, or a selected variant.

For Apify as an alternative to import.io, test the job boundary as well as extraction. How does your system learn that a run completed? Where does it retrieve the result? What happens when a run fails after producing some records? The dataset documentation provides the relevant storage model to examine when designing that handoff.

Scheduling needs a separate check. The platform's schedule documentation explains recurring Actor and task execution. Decide which timezone your business deadline uses and what your consumer should do if the expected dataset has not arrived. A schedule starts work; your acceptance logic determines whether the resulting delivery is ready to use.

This candidate fits a team willing to own integration and validation while delegating part of execution to a platform. Keep the Actor input, expected schema, and consumer checks under change control. If you evaluate a third-party Actor, include maintenance expectations in the decision rather than treating the platform name as a guarantee about every available implementation.

Choose Scrapy when your engineers should own the collector

Scrapy is a Python framework for crawling websites and extracting structured data, as described in its official overview. It is a different kind of alternative: your team owns the collector's behavior and operates the surrounding system. Compare it with a platform only after accounting for that responsibility.

The attraction is explicit logic. Engineers can define what identifies a record, how pages are followed, which fields are required, and how a malformed response is handled. That control is useful when the data model has important domain rules or the collector must integrate closely with an existing application. It also means somebody must understand and maintain those decisions.

As an alternative to import.io, a framework should be evaluated with deployment, scheduling, observability, and storage included in the pilot. A script that works on its author's laptop is an incomplete replacement for a recurring delivery. Ask another engineer to run it from the documented environment and diagnose a controlled failure using the available logs.

Page rendering is another boundary to make explicit. Inspect whether the required data is present in the response your collector receives or requires browser interaction. If the latter is necessary, design that part intentionally. The site's Playwright scraping and automation guide is useful background for understanding the additional browser workflow; do not assume that every Python crawler executes a page like a browser.

Choose this direction when ownership and customization justify the engineering work. It is not automatically cheaper because the framework is open source. The relevant cost includes operating the job, reviewing source changes, responding to failures, and keeping the data contract stable for its consumers.

Build one pilot that exposes incomplete data

Use the same authorized source scope and expected records for every alternative to import.io. Include ordinary pages and difficult but representative cases. Do not build the evaluation entirely from the easiest page or from a vendor-selected demonstration, because that leaves the most expensive maintenance problems untested.

A small product catalog example makes the contract concrete. Each record needs a source URL, stable product identifier, observed time, name, price value, currency, and availability. Treat a missing price differently from a genuine zero. Keep the raw observed value where practical so that normalization decisions can be audited without immediately recollecting the page.

Pilot case

Expected check

Why it matters

Optional field absent

Record remains valid with an explicit missing value

Missing data should not shift fields

Same item on two pages

Identity rule handles repeated observations

Row count alone can hide duplication

Empty result page

Delivery is marked empty with context

Empty data and failed extraction differ

Layout changed

Validation identifies affected fields

A successful run can still return bad records

Delayed run

Consumer keeps the freshness state visible

Yesterday's result should not look current

Calculate metrics from your actual pilot rather than borrowing benchmark claims. Useful measures include required-field completeness, duplicate rate under your identity rule, freshness at the delivery deadline, and operator repair time. Preserve the manually checked sample and the evaluation date. Explain how you calculated each measure so another person can reproduce it.

Test the handoff to the real destination. CSV escaping, date interpretation, decimal formats, and repeated imports can create defects after extraction has succeeded. Import the same delivery twice into a test destination and verify your intended behavior. Either the process should recognize the same batch or explicitly create a new observation, depending on your data model.

Finally, inspect unsuccessful responses before parsing them. A collection client can receive a login page or an unexpected document instead of the desired content. The guide to Python HTTP clients provides context if engineers are building this validation into the request layer. Count only accepted records as usable output when comparing candidates.

Compare total work and migrate in controlled batches

Price comparisons are meaningful only after the workload is defined. List expected pages, recurrence, rendering needs, result retention, export destination, and support requirements. Ask each provider how the proposed workload maps to its current charging model. This guide provides no numeric price ranking because a plan label alone does not establish the cost of your project.

For each alternative to import.io, distinguish the subscription or infrastructure charge from internal work. Include task setup, schema mapping, repair effort, monitoring, and downstream import maintenance. If one option moves those responsibilities onto your engineers, show that explicitly instead of treating them as free. If a managed offering covers them, verify the scope rather than assuming it.

Migrate by dataset or source group, with a stable comparison period. Export the current field definitions, destination mappings, schedules, and known exceptions before changing anything. Keep the existing delivery available while the replacement produces test output, and compare representative records using the same identifiers. Avoid changing the schema and the extraction provider simultaneously unless the consumer can distinguish those changes.

Set rollback criteria in terms of data usability. Missing required fields, unacceptable freshness, or unexplained record differences should hold the affected batch for review. A single run marked successful is not a reason to disconnect the previous workflow. Document who decides that the replacement is ready and how consumers will identify the first accepted delivery.

Limit the source scope to data your organization is authorized to collect and retain. Keep credentials out of exported files and use the narrowest necessary access for test accounts. For authenticated workflows, understand HTTP cookie and session behavior before transferring a task between local and hosted execution. Access to a page does not by itself define the allowed uses of its data.

Key Takeaways

  • Select an alternative to import.io around maintenance ownership and delivery requirements, then compare features.
  • Test Octoparse, Browse AI, Apify, or Scrapy according to the operating model your team can support.
  • Validate record identity, required fields, freshness, and destination imports; a completed run is not enough.
  • Use your own measured pilot results and current provider quotes instead of invented savings or universal performance rankings.
  • Preserve the old delivery until the new workflow meets explicit acceptance and rollback criteria.

FAQ

Can I recover historical observations by switching providers?

Not automatically. A new collection run observes what is available when it runs; it does not reconstruct earlier page states. Identify historical files and retention requirements before ending the existing arrangement. If you need older observations, establish whether you already hold them or whether a separately sourced historical dataset meets your requirements.

Should screenshots count as structured records?

Usually they should be supporting evidence, not a substitute for the fields your consumer expects. A screenshot can help a reviewer understand an observation, but it is difficult to query consistently as a table. Keep a link between the image and the corresponding record if your workflow needs visual evidence, and define an appropriate retention period.

Can two correct observations contain different prices?

Yes. Observations made under different conditions can legitimately differ, so preserve the context needed to interpret them. That might include observation time, selected variant, delivery location, or account state when relevant and permitted. Decide which conditions your dataset standardizes before labeling every difference an extraction defect or overwriting the earlier value.

Choose a replacement your team can maintain

The best alternative to import.io for your project is the one that produces accepted data under a clear ownership model. Octoparse and Browse AI are worth testing when the intended operators prefer visual workflows. Apify offers a hosted job model to evaluate, while Scrapy puts the collector's implementation and operation in your team's hands. Your pilot should determine which arrangement actually fits.

Make the decision with a sample dataset, measurable acceptance checks, and a named maintainer. Include export behavior and failure recovery in the trial, then migrate in batches while preserving a way back. That gives the data consumer a stable contract even when the machinery behind it changes.

If your engineers want to retain parsing and validation while evaluating an external fetching layer, include WebScrapingAPI's Scraper API in that focused pilot. Judge it against the same authorized source sample and delivery checks. The useful comparison is the amount of dependable, usable data your workflow delivers and the work your team must do to keep it that way.

About the Author

Ștefan Răcilă, Full Stack Developer @ WebScrapingAPI

Ștefan Răcilă

Full Stack Developer

Stefan Racila is a DevOps and Full Stack Engineer at WebScrapingAPI, building product features and maintaining the infrastructure that keeps the platform reliable.

Start Building

Ready to Scale Your Data Collection?

Join 2,000+ companies using WebScrapingAPI to extract web data at enterprise scale with zero infrastructure overhead.